The Elevate Blog banner: Real Classrooms. Practical Ideas. Higher Expectations. Three students climb a rocky ridge at sunrise, each pulling the next one up, toward a teacher reaching down to help.

Author: Clay Shumate

  • Accountable Talk in Grades 6–12: The Moves, the Standards, and What the Research Found

    Accountable Talk in Grades 6–12: The Moves, the Standards, and What the Research Found

    By Clay Shumate

    Accountable talk is a framework from the University of Pittsburgh that holds class discussion to three standards: accountability to the learning community, to accurate knowledge, and to rigorous thinking. It names twelve teacher moves and publishes the wording for each one. The moves are free to use. The evidence behind them is thinner than the training slides suggest.

    Key Takeaways

    • Accountable talk is a standard for what counts as a contribution, not a discussion format. It does not tell you to run a seminar or a fishbowl. It tells you what a student’s sentence has to do before it earns the air it takes up.
    • The moves are published and cost nothing. The Accountable Talk Sourcebook names twelve of them with the example wording printed next to each. The phrase itself is a registered trademark of the University of Pittsburgh, which affects what a consultant may sell, not what you may say on Tuesday.
    • There is no randomized trial of accountable talk itself. The “two months’ extra progress” number that gets attached to it belongs to a different program — and the same funder’s 2019 follow-up found no impact on those pupils’ end-of-primary results.
    • The signature move is the one that barely happens. When Pittsburgh’s own researchers scored 21 real lessons, students linking their comments to each other was the weakest thing they measured, at a mean of 2.00 on a four-point scale, and linking moves were “rarely observed.”
    • Almost none of this research is about teenagers. The field’s own meta-analysis of classroom discussion had a mean participant age of 10.39, with only two of 42 studies drawn from secondary samples. The best secondary evidence is correlational, and its most useful finding is how little discussion actually happens.

    What is accountable talk?

    Accountable talk is classroom discussion held to three standards at once: students are accountable to the learning community, to accurate knowledge, and to rigorous thinking. It is a set of expectations for what a contribution has to do, enforced by a short list of things the teacher says.

    The framework comes out of the Institute for Learning at the University of Pittsburgh, in a document called the Accountable Talk Sourcebook, written by Sarah Michaels, Mary Catherine O’Connor, Megan Williams Hall and Lauren Resnick. Pittsburgh’s own learning-research centre put the three standards this way in a 2004 conference paper, and these are the definitions worth quoting because they are the tightest version anyone has published.
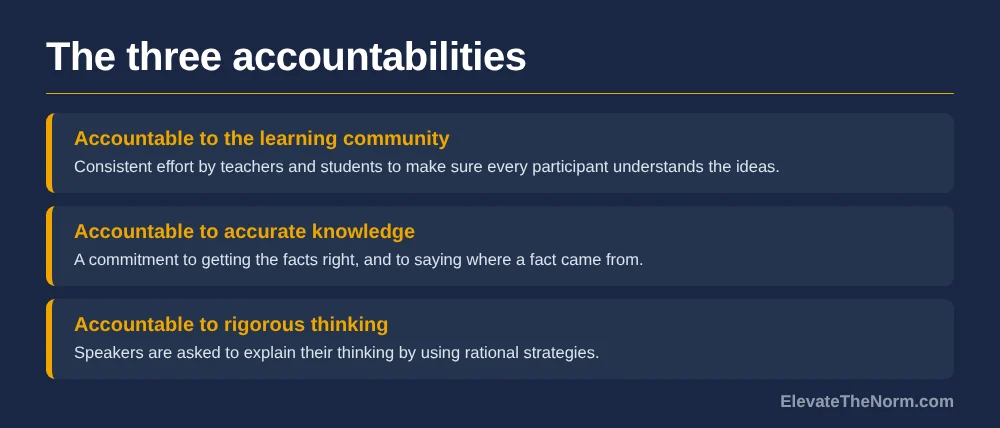
    Three stacked panels naming accountability to the learning community, to accurate knowledge, and to rigorous thinking, each with the definition published by Pittsburgh's learning research centre.
    The three standards, in the wording Pittsburgh’s own researchers used in 2004.

    Notice what is missing. There is no seating arrangement, no timer, no protocol. You can run accountable talk inside a full-class seminar, inside a two-minute pair turn, or in the four minutes between a reading and a bell. That is the useful thing about it and also why it is so easy to fake.

    It sits one level below the formats, in other words. A seminar, expert groups and randomly called group answers all decide who speaks and when. Accountable talk decides what a sentence has to contain once somebody does speak, which is the gap getting students talking to each other leaves open.

    The Sourcebook is unusually blunt about the faking. It says outright that having students talk does not guarantee learning, that going through the motions without working on the learning problem does not meet the standard, and that the familiar teacher-question-student-answer-teacher-evaluation pattern does not promote rigorous thinking — while allowing that it has uses, such as checking recall.

    What are the accountable talk moves?

    The Sourcebook names twelve moves and prints a sample utterance beside each. Four are general, four build the learning community, two press on accuracy and two press on reasoning. The wording below is exactly as published, which matters, because most lists circulating online are paraphrases of paraphrases.

    MoveWhat the teacher saysWhat it is holding students to
    Marking“That’s an important point”General — flags the idea worth keeping
    Challenging students“What do YOU think?”General — hands the thinking back
    Modeling“Here’s what good readers do.”General — makes the expert move visible
    Recapping“What have we discovered?”General — consolidates
    Keeping the channels open“Did everyone hear that?”The learning community
    Keeping everyone together“Who can repeat…?”The learning community
    Linking contributions“Who wants to add on…?”The learning community — this is the one that makes a reply a reply
    Verifying and clarifying“So, are you saying…?”The learning community
    Pressing for accuracy“Where can we find that?”Accurate knowledge
    Building on prior knowledge“How does this connect?”Accurate knowledge
    Pressing for reasoning“Why do you think that?”Rigorous thinking
    Expanding reasoning“Take your time; say more.”Rigorous thinking

    The instrument Pittsburgh built to score these lessons spells out the student half too, which is the more useful half. Meeting the knowledge standard sounds like “I know that because it says here…”; meeting the reasoning standard, “I think because…”; linking, “I want to add on to what Ann said…” or “I agree with you because…”. Those four sentence shapes are the whole target.

    Are talk moves and accountable talk the same thing?

    Not quite, and the confusion is worth clearing up because it corrupts the evidence. “Accountable Talk” is one named, trademarked framework. “Talk moves” is the generic term for the same kind of teacher utterance, used across several different programs with different move lists and different research behind them.

    The Sourcebook carries the notice “Accountable Talk® is a registered trademark of the University of Pittsburgh.” Practically that changes nothing in your classroom — the document is downloadable and nobody is coming after a teacher for asking “why do you think that?”. What it did do is push everyone else to invent adjacent vocabulary: productive talk, dialogic teaching, quality talk, academic discourse. Four names, overlapping move lists, separate research bases — which is why so much of what gets presented as “the research on accountable talk” is a trial of something else.

    Does accountable talk actually work?

    Nobody has run the trial that would answer that. There is no randomized controlled trial of accountable talk as a named program. What exists is observational work from Pittsburgh itself, plus randomized trials of related dialogue programs, plus one large correlational study in secondary English classrooms.

    The Pittsburgh study is worth reading anyway. Wolf, Crosson and Resnick scored one reading lesson each from 21 teachers across grades 1–8, covering 441 students. What they found is a chain: what the teacher asks for is what comes back. Teacher asking for knowledge correlated with students providing it at r = .90, and asking for reasoning with students providing reasoning at r = .88. Students providing knowledge alone explained 70 percent of the variance in a lesson’s academic rigor.

    That is a strong, useful result, and it is correlational. One lesson per teacher, exact rater agreement on the talk measures of only 57 to 67 percent, and the authors calling their rubrics “still at a developmental stage.” It does not show that installing the moves raises achievement. It shows that where teachers ask for reasoning, students give reasoning.

    The best secondary-grades evidence is Applebee, Langer, Nystrand and Gamoran (2003) — 974 students in 64 English classrooms across five states, grades 7–8 and 10–12. Discussion-based approaches were significantly related to spring literacy performance, with a classroom-level effect size of .53. Also non-experimental: no random assignment, each class observed four times, and school-level reliability of .47. The authors wrote “significantly related to,” and so should anyone quoting them.

    The number from that study I would actually put on a staff-meeting slide has nothing to do with effect sizes. Open discussion averaged 1.7 minutes per 60 minutes of class. In low-track classes it averaged about 42 seconds. In high-track classes, 3.3 minutes. Before anyone argues about whether discussion works, it is worth knowing how little of it there is.

    What is the evidence against it?

    Strong enough that the honest answer to “is this proven?” is no. Two large randomized trials of structured classroom dialogue produced small effects that then failed to hold up, and the field’s own meta-analysis found the gains shrink the longer a program runs.
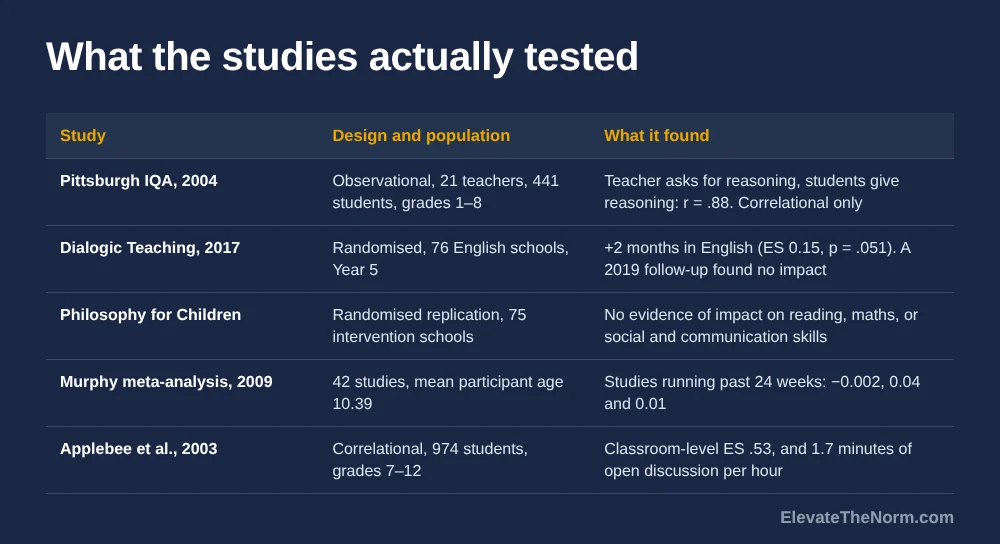
    Table comparing four studies of classroom dialogue by design, population and result, including the two randomized trials whose effects did not hold at follow-up.
    The four studies people are usually pointing at, and what each one actually tested.

    Start with the trial that produced the famous number. The Education Endowment Foundation funded a cluster randomized trial of Alexander’s Dialogic Teaching in 76 English schools, 4,958 Year 5 pupils at randomization, evaluated by Sheffield Hallam. It reported about two months’ additional progress in English (effect size 0.15) and science (0.12), and one month in math (0.09).

    Then read the small print, all of which is in the report. English came in at p = 0.051, with a confidence interval whose lower bound was 0.00. Math was p = 0.19 — not significant, though the months conversion gets applied anyway. Twenty-one percent of pupils dropped out of the analysis, mostly because 7 of 38 intervention schools returned no post-test data. The trial could reliably detect only an effect of 0.25 to 0.28, larger than anything it found. And without the school-level and free-school-meals covariates, the report says, none of the three outcomes were significant.

    Then read the addendum. In April 2019 the same funder published a follow-up finding no impact on those pupils’ end-of-primary results. Anyone quoting “two months’ progress” without that sentence is quoting half a study.

    The same shape happened to Philosophy for Children, the other structured-dialogue program teachers hear about. A 2015 trial in 48 schools reported about two months in reading and math. The larger follow-up found no evidence of impact on reading, math, or social and communication skills, at the highest security rating the funder awards, across 75 intervention and 123 comparison schools. One detail from that trial belongs in every discussion of talk programs: 96 percent of teachers believed their pupils’ respect for other people’s opinions had improved, and the pupil survey showed no significant improvement.

    Three more things worth knowing before you build a semester around this.

    • The gains shrink with time, not grow. In Murphy and colleagues’ meta-analysis of 42 classroom-discussion studies, comparison-group studies running longer than 24 weeks produced effects of −0.002 on text-explicit comprehension, 0.04 on text-implicit, and 0.01 on critical thinking. The “it compounds once the culture takes hold” story is not in the data.
    • What moves most reliably is the talk, not the learning. The same meta-analysis found large shifts in who was speaking — one approach moved student talk by more than four standard deviations — while its inferential comprehension effect was 0.08. Those big numbers are measurements of airtime.
    • Fidelity did not predict results in the one trial that checked. The 2015 Philosophy for Children trial correlated implementation scores against attainment gains and got coefficients between −0.10 and 0.02. That quietly removes the usual defence that a null result means weak implementation.

    How much wait time do students actually need?

    About three seconds, against an untrained baseline of roughly one. The Sourcebook asks for at least 2.7 seconds and prefers three, after the question and again after a student finishes answering. It is the cheapest move on the list and the one most teachers skip.

    The one-second figure comes from Mary Budd Rowe’s 1974 work and is reported in a peer-reviewed review of wait times in physics teaching, which also collects the recommended thresholds: three to four seconds for a recall question, up to fifteen for a question that requires thinking, and more than three seconds after the student stops talking. I have not read Rowe’s original paper, so that is a summary of her finding rather than a direct citation of it.

    The honest caveat sits in the same review: Tobin’s 1987 analysis found the link between wait time and pupil performance “somewhat inconsistent.” Longer waits reliably produce longer answers. Longer answers reliably producing higher test scores is a separate claim, and a shakier one.

    How do you start accountable talk in a grades 6–12 classroom?

    Start with the student sentences, not the teacher moves. The moves exist to produce four kinds of student utterance, and if you teach those four directly you have skipped a term of modelling. Here is a sequence that follows what the sources actually support.

    1. Post the four student sentence shapes where everyone can see them. “I know that because it says here…”, “I think because…”, “I want to add on to what ___ said…”, “I agree with you because…”. These are from Pittsburgh’s own scoring instrument, not an invented poster.
    2. Set the two norms the Sourcebook names, and only those. Nobody gets ridiculed, and critique is aimed at ideas rather than people. Long norm posters die; two rules you enforce every single time do not. Enforce them hardest on the day the topic turns personal, which in a social studies room is most weeks.
    3. Pick one question per lesson worth three seconds of silence. Not every question. One. A recall question answered in a second is doing a different job and the research says that job is legitimate.
    4. Write before anyone speaks. Thirty to ninety seconds of writing means the first student to talk is not also the first student to think. The think-pair-share routine exists for exactly this. It also means the quiet student has produced something you can read, which is the fair way to handle a kid who thinks hard and hates the sound of their own voice.
    5. Use the linking move on purpose, every day, and count it. “Who wants to add on to that?” turns parallel answers into a conversation, and it is the one Pittsburgh’s researchers found almost nobody uses. If you install one move, install this one — and it is the single thing worth tallying in a peer observation.
    6. Press once, then stop. “Why do you think that?” followed by your own answer is not a press. The documented failure mode is exactly that: teachers who asked and then filled the silence themselves.
    7. Mix the groups. In a study of 62 students in grades 4–5 at one school, heterogeneous groups gained more in written argumentation, and the lowest-performing homogeneous groups grew more slowly while needing more teacher intervention. Hold it loosely, but it points the same way as the tracking data above.
    8. Judge it on the work, not on the volume. More student talk is the easiest thing to produce and the weakest evidence of anything. Mark the written argument that comes out the other end. That is a real grading cost, and it is the only one on this list — do not also grade participation, which measures confidence.

    None of that needs a training budget. For scale, the dialogic teaching trial cost about £52 per pupil a year and three training days per teacher — and its teachers still said two terms was too short to embed the approach.

    What goes wrong with accountable talk?

    It becomes a script. Pittsburgh’s researchers separated “formulaic” from “substantial” use after watching teachers ask “do you agree? why?” and then answer their own question or allow no wait time at all. The words were right and nothing happened.
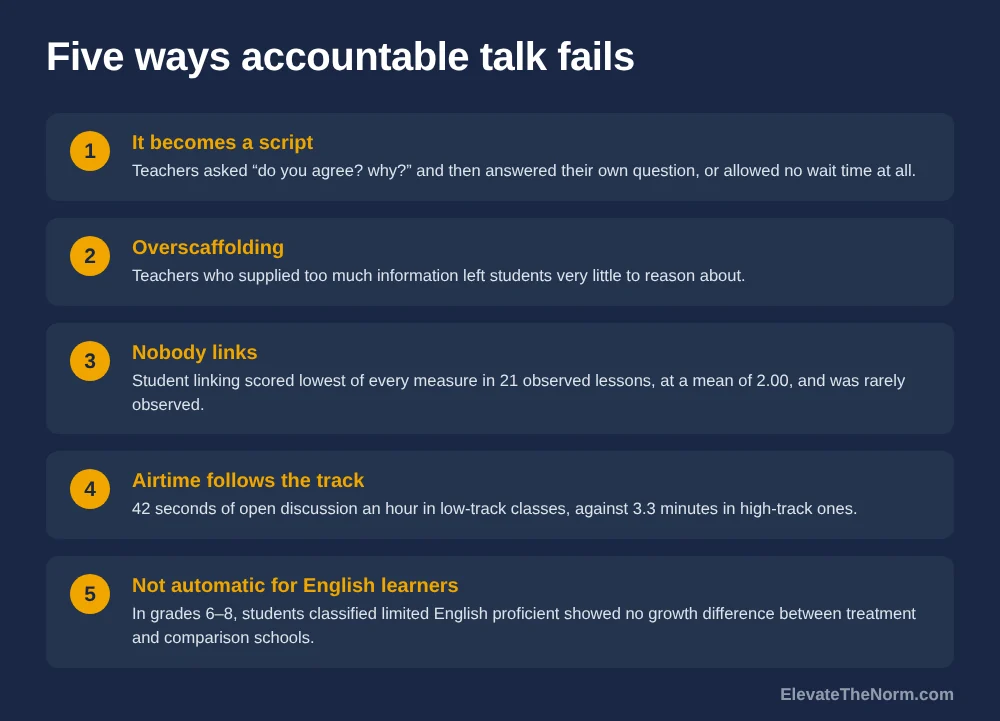
    Five numbered cards naming documented failure modes of structured classroom talk, including formulaic use, overscaffolding, unused linking moves, unequal airtime by track, and the limits for English learners.
    Five failure modes, each one documented in the research rather than guessed at.

    Four more, all of them in the sources rather than in my imagination.

    Overscaffolding. The same study found teachers who supplied too much information left students with little to reason about. The ceiling on student thinking is the question you asked, not the protocol you ran.

    Nobody links. Student linking scored lowest of every measure in those 21 lessons, at a mean of 2.00 with a standard deviation of 1.183, and the researchers specifically called for raising teachers’ awareness of linking moves. The distinctive promise of the framework was the thing least present in the rooms where it was being taught.

    It is worth asking why, from a desk rather than from the front. Saying “I disagree with Ann” out loud costs something when you sit near Ann every day for a year. “Nothing to add” is usually the rational answer, not a lazy one. Which means the repair is not a better stem or a firmer insistence — it is a question with more than one defensible answer, so that adding on is worth the social price. If the question has one right answer, linking is just a public ritual, and teenagers can tell.

    Airtime is already rationed by track. Forty-two seconds an hour in low-track classes against 3.3 minutes in high-track ones is not a discussion-technique problem, and no set of talk moves will fix it on its own. The students who most need practice reasoning out loud are getting the least of it. If your department tracks, that is where the conversation has to start.

    It is not automatically good for English learners. The nearest hard number runs the other way. In a longitudinal study of an academic-discussion program in grades 6–8 in Boston, students classified as limited English proficient showed no difference in vocabulary growth between treatment and comparison schools, with an interaction term of −0.205, while their English-proficient classmates gained. The groups were not well matched at baseline, so this is not the last word — but “talk is good for language learners” is an assumption, not a finding.

    Clay’s take: the question is the ceiling

    I would teach the four student sentences and the linking move, skip the rest of the vocabulary, and stop pretending the research says more than it does. The strongest finding in this whole literature is that what the teacher asks for is what comes back.

    That is also the uncomfortable part. If the room produces thin answers, the protocol is rarely the problem. A better question beats a better framework, and no amount of “who can add on?” rescues a question with one correct answer and no reason to argue.

    What I would not do is buy this as a program. There is no trial of it, the two big trials of its cousins both faded at follow-up, the research base is mostly ten- and eleven-year-olds, and the one secondary study everyone cites is correlational. The moves are good craft, published free, worth using. They are not an intervention with a number attached, and a teacher who treats them as one will be disappointed in a way the evidence predicted.

    The thing I find hardest to argue with is 1.7 minutes an hour. Whatever you call it, the practical question in most secondary classrooms is not which talk framework to adopt. It is whether teenagers get to say anything substantial at all, and who in the building gets to.

    Frequently Asked Questions

    What is accountable talk in simple terms?

    It is classroom discussion held to three standards at once: students have to help everyone else understand, they have to get their facts right, and they have to explain their reasoning. The teacher enforces those standards with a short list of published moves, such as asking who wants to add on and asking why a student thinks that.

    Are talk moves and accountable talk the same thing?

    No. Accountable Talk is one named framework from the University of Pittsburgh with twelve published moves. Talk moves is the generic term for the same kind of teacher utterance, used by several programs with different lists and different research behind them. The distinction matters because evidence from one program is routinely quoted as evidence for another.

    What are the three accountable talk standards?

    Accountability to the learning community, which means consistent effort to make sure everyone understands the ideas. Accountability to accurate knowledge, which means a commitment to getting the facts right. Accountability to rigorous thinking, which means speakers are asked to explain their thinking using rational strategies. Those are the definitions published by Pittsburgh’s own learning research centre.

    Is there research proving accountable talk raises achievement?

    Not for accountable talk specifically. No randomized trial of it as a named program exists. The supporting Pittsburgh study is observational and correlational, and the large randomized trials people cite tested related programs, Dialogic Teaching and Philosophy for Children. Both reported small early effects that did not hold at follow-up.

    Does accountable talk work in middle and high school?

    It is plausible and largely untested there. The field’s meta-analysis of classroom discussion had a mean participant age of 10.39, with only two of 42 studies using secondary samples. The best secondary evidence covers grades 7 to 12 English classrooms and is correlational, reporting a classroom-level effect size of .53 without random assignment.

    Do I need permission to use accountable talk, since it is trademarked?

    No. Accountable Talk is a registered trademark of the University of Pittsburgh, which governs commercial use of the name. The Sourcebook that names the twelve moves and prints the example wording is published and downloadable, and no teacher needs permission to ask a class why they think that or who wants to add on.

    What are accountable talk sentence stems for high school students?

    The four taken straight from Pittsburgh’s scoring instrument are the ones worth posting: I know that because it says here, I think because, I want to add on to what someone said, and I agree with you because. They carry the three standards without a wall of laminated prompts, and older students stop needing them quickly.

    How much wait time should I give after a question?

    At least 2.7 seconds and preferably three, both after the question and after a student finishes speaking. The untrained baseline is roughly one second. Reviewed recommendations run from three to four seconds for a recall question up to fifteen for a demanding one. Longer waits reliably lengthen answers; the link to test scores is less consistent.

    Sources

    • Michaels, S., O’Connor, M. C., Hall, M. W., & Resnick, L. B. Accountable Talk Sourcebook: For Classroom Conversation That Works. Institute for Learning, University of Pittsburgh, 2010. Discussion-moves excerpt (PDF). Source of the twelve named moves and their exact example wording, the trademark notice, the wait-time figures of under a second typical and at least 2.7 preferring three, the two trust norms, and the explicit statements that talk alone does not guarantee learning and that recitation does not promote rigorous thinking.
    • Wolf, M. K., Crosson, A. C., & Resnick, L. B. Classroom Talk for Rigorous Reading Comprehension Instruction. Paper presented at AERA, San Diego, 2004. Learning Research and Development Center, University of Pittsburgh. Full text (PDF). Source of the three accountability definitions as quoted, the student and teacher utterance wording, the correlations of .90 and .88, the 70 percent of variance explained by students providing knowledge, the student-linking mean of 2.00 with SD 1.183, the 57 to 67 percent rater agreement, and the documented formulaic-use and overscaffolding failure modes. Observational and correlational: 21 teachers, 441 students, grades 1–8.
    • Jay, T., Willis, B., Thomas, P., Taylor, R., Moore, N., Burnett, C., Merchant, G., & Stevens, A. Dialogic Teaching: Evaluation Report and Executive Summary. Sheffield Hallam University for the Education Endowment Foundation, July 2017. Evaluation report (PDF). Source of the cluster-randomized design, 76 schools and 4,958 Year 5 pupils at randomization, the effect sizes of 0.15, 0.12 and 0.09 with their p-values and confidence intervals, the 21 percent attrition and seven schools returning no post-test data, the minimum detectable effect of 0.25 to 0.28, the statement that no outcome was significant without the covariates, the cost of about £52 per pupil, and the training-day counts.
    • Education Endowment Foundation. Dialogic Teaching project page, including the April 2019 addendum. Project page. Source of the months-progress headlines, the moderate three-padlock security rating, and the follow-up finding of no impact on end-of-primary results.
    • Education Endowment Foundation. Philosophy for Children — effectiveness trial. Project page. Source of the failed replication: 75 intervention and 123 comparison schools, no evidence of impact on reading for pupils eligible for free school meals or for all pupils, none on math, none on social and communication skills, the highest security rating, and the gap between 96 percent of teachers believing respect had improved and the pupil survey showing no significant improvement. The earlier 2015 trial’s two-months figures and its fidelity-attainment correlations of −0.10 to 0.02 are reported in Gorard, Siddiqui & See, Philosophy for Children: Evaluation Report, Durham University for the EEF, 2015.
    • Murphy, P. K., Wilkinson, I. A. G., Soter, A. O., Hennessey, M. N., & Alexander, J. F. Examining the Effects of Classroom Discussion on Students’ Comprehension of Text: A Meta-Analysis. 2009. Full text (PDF). Source of the 42 included documents, the mean participant age of 10.39 with only two secondary samples, the over-24-week effects of −0.002, 0.04 and 0.01, the large talk-volume effect sizes against small comprehension effects, and the authors’ own conclusion that few approaches improved literal or inferential comprehension or critical thinking.
    • Applebee, A. N., Langer, J. A., Nystrand, M., & Gamoran, A. Discussion-Based Approaches to Developing Understanding: Classroom Instruction and Student Performance in Middle and High School English. American Educational Research Journal, Vol. 40, No. 3, pp. 685–730 (2003). Full text (PDF). Source of the 974 students in 64 classrooms across five states, grades 7–8 and 10–12, the classroom-level effect size of .53, the 1.7 minutes of open discussion per 60 minutes with 42 seconds in low-track and 3.3 minutes in high-track classes, and the authors’ stated limitations including school-level reliability of .47 and four observations per class. Non-experimental and correlational.
    • Wackermann, R., Timmerman, D., & Krabbe, H. Teacher wait-times in physics instruction of different duration. Progress in Science Education, 2018. Full text (PDF). Source of Rowe’s 1974 one-second finding, the three-to-four-second and up-to-fifteen-second thresholds, and Tobin’s 1987 verdict that the wait-time and performance link is somewhat inconsistent. Rowe’s original paper was not read for this article; this is a peer-reviewed summary of it.
    • Lawrence, J. F., Capotosto, L., Branum-Martin, L., White, C., & Snow, C. E. Language proficiency, home-language status, and English vocabulary development: a longitudinal follow-up of the Word Generation program. Bilingualism: Language and Cognition, Vol. 15, No. 3 (2012). Full text (PDF). Source of the grades 6–8 academic-discussion results in Boston, the limited-English-proficiency interaction of −0.205, the finding of no difference in growth for those students between treatment and comparison schools, and the authors’ note that the groups were not well matched at baseline.
    • Murphy, P. K., Greene, J. A., Firetto, C. M., Li, M., Lobczowski, N. G., Duke, R. F., Wei, L., & Croninger, R. M. V. Exploring the influence of homogeneous versus heterogeneous grouping on students’ text-based discussions and comprehension. Contemporary Educational Psychology, Vol. 51 (2017). Full text (PDF). Source of the grouping finding cited in the step list: 62 students in grades 4–5 at one school, heterogeneous groups gaining more in written argumentation, low-ability homogeneous groups growing more slowly and receiving more teacher moves, and no effect of group composition on basic comprehension.
    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • Station Rotation in Grades 6–12: What the Evidence Shows, and How to Build One That Works

    Station Rotation in Grades 6–12: What the Evidence Shows, and How to Build One That Works

    By Clay Shumate

    Station rotation splits one class into groups that cycle on a timer through stations inside the same room, at least one of them online. It is a scheduling structure, not an intervention. The one study that looked for research on it found none, and the evidence that exists belongs to a single station: the teacher-led small group.

    Key Takeaways

    • The people who named the model declined to claim it works. Heather Staker and Michael Horn’s taxonomy says plainly that “the definitions in this taxonomy leave out such appraisals” of quality, and that blended learning “can be both good and bad.”
    • Somebody did go looking, and came back empty. A 2020 study by the American Institutes for Research reports that its literature search “did not yield any empirical research articles on station rotation” — then found the model “was not associated with significantly higher student achievement on standardized assessments.”
    • The evidence lives in one station. Teacher-led small-group instruction has real, replicated effects. It also discounts with age: the Education Endowment Foundation puts small group tuition at +4 months in primary and +2 months in secondary.
    • Group size is the number that matters most. The EEF’s rule of thumb is that “the smaller the group the better,” and that “once group size increases above six or seven there is a noticeable reduction in effectiveness.” A thirty-student class in three stations puts ten at the teacher table.
    • The costs land harder in high school than in elementary. Lost instructional time rises with grade level, and 17 percent of US teens told Pew they are at least sometimes unable to finish homework because they lack reliable internet or a computer.

    What is station rotation?

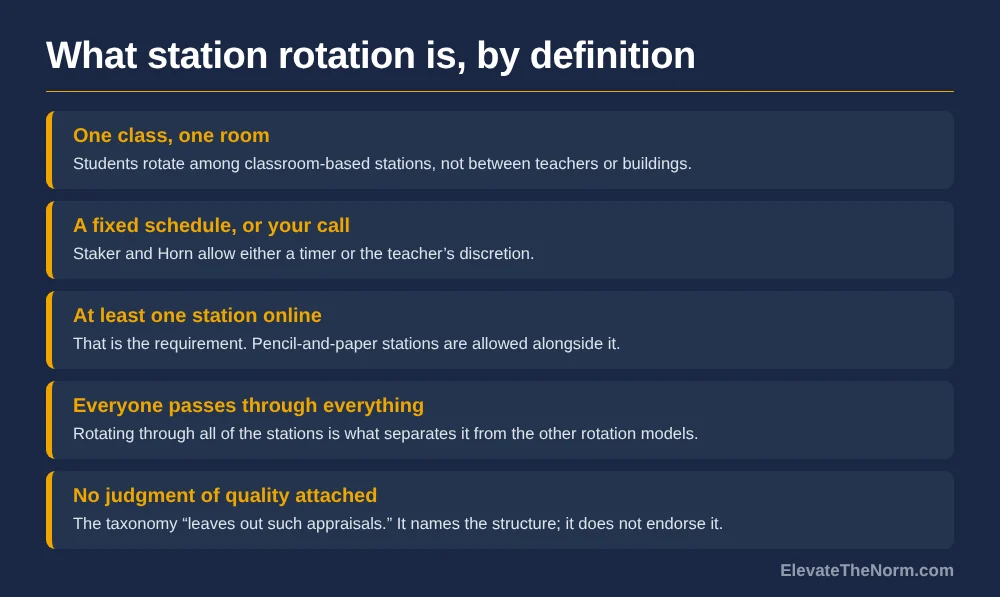
    Station rotation is a blended-learning model in which students in one course rotate on a fixed schedule, or at the teacher’s discretion, among learning stations inside the classroom — and at least one of those stations is online. Every student passes through every station.

    That definition is not a paraphrase. Staker and Horn’s 2012 taxonomy defines the Station-Rotation model as “a Rotation-model implementation in which within a given course or subject (e.g., math), students rotate on a fixed schedule or at the teacher’s discretion among classroom-based learning modalities,” where “the rotation includes at least one station for online learning.” What separates it from the other rotation models is that “students rotate through all of the stations.”

    Five stacked panels setting out the defining features of station rotation: one class in one room, a fixed schedule or teacher discretion, at least one online station, every student rotating through all stations, and no judgment of quality in the taxonomy.
    The taxonomy names the structure. It does not endorse it.

    Two things in that document deserve more attention than they get. The first is the authors’ stated purpose: definitions that “create a shared language that enables people to talk about the new phenomena.” A classification, in other words. The second is their refusal to grade it. The taxonomy “leaves out such appraisals,” and the paper says blended learning “can be both good and bad.”

    Worth noticing where the canonical example comes from. The illustration Staker and Horn use for station rotation is a kindergarten classroom, with fifteen computers, rotating among online learning, small-group instruction and individual assignments. The model’s defining picture is five-year-olds. That is not a reason to dismiss it in grades 6–12, but it is a reason to stop treating it as a secondary practice with a secondary track record.

    Does station rotation actually work?

    Nobody knows. The American Institutes for Research looked for empirical research on station rotation in 2020 and reports that its search “did not yield any empirical research articles on station rotation.” It describes the wider personalized-learning research base as “thin.”

    That is the whole answer to the question most teachers are asking, and it is worth sitting with: the one serious attempt to find evidence for this model came back empty-handed before it had even started looking at students.

    So AIR ran its own descriptive study across five sites, and found that “station rotation was not associated with significantly higher student achievement on standardized assessments.” Attendance showed no significant difference either. Students did generally report positive views of their learning — self-reported, affective, and not the same thing as learning more.

    Read that result with the authors’ own limits attached. Their design “does not allow for strong causal inference”: it is a convenience sample, reporting associations rather than effects. A null association is not proof the model fails. It is the absence of the evidence most people assume is already there.

    And even that study is not about your students. Its surveys went to all grade 4–8 teachers, and it reports station rotation was “more common in elementary grades than in middle grades.” There is no grades 9–12 study of this model at all.

    Why do people think station rotation has evidence behind it?

    Because one federal number gets borrowed constantly. The US Department of Education’s meta-analysis of online learning reported that “the mean effect size in studies comparing blended with face-to-face instruction was +0.35, p < .001.” That figure is real, and it is not about secondary students.

    The report’s authors say so themselves, twice. “The great majority of estimated effect sizes in the meta-analysis are for undergraduate and older students,” and “caution is required in generalizing to the K–12 population.” Then the sentence that undoes the marketing version entirely: “the positive effects associated with blended learning should not be attributed to the media, per se” — because the blended conditions usually added learning time and extra instructional elements on top.

    Purely online against face-to-face, in the same analysis, produced an average effect of +0.05 and was not statistically significant. The blended advantage came from adding things, not from moving things online.

    How thin is the K–12 base underneath all this? A federal regional lab review puts a number on it: of the prior meta-analytic literature, “only 5 of 176 studies that met the authors’ eligibility criteria focused on K–12 schooling.” Of its own 17 studies, “only 7 used a rigorous group research design,” and it concludes that its findings “do not allow for conclusions to be drawn about the effectiveness of these programs as a whole.”

    What does the one secondary study show?

    It contradicts itself, which is more useful than it sounds. Minaz Fazal and Melanie Bryant compared station-rotation blended learning against face-to-face instruction with 413 sixth graders in middle school math, and got opposite answers from two different tests.

    On the MAP growth measure, the blended group came out ahead: t(411) = 3.02, p = .003, d = 0.30. On the STAAR state achievement test, the face-to-face group came out ahead, d = −0.28, p = .005. Same students, same study, two outcome measures, two signs.

    The design limits it further. Students were not randomly assigned; the authors call the work non-experimental, with four teachers and intact classes. Take one number from that study and you can prove whatever you came to prove, which is roughly what has happened to this model in general.

    Where is the real evidence in this model?

    In the teacher station. Small-group instruction from a teacher is one of the better-evidenced things in education, and in a station rotation it is the only part of the structure carrying a track record.

    Andre Nickow, Philip Oreopoulos and Vincent Quan’s meta-analysis of experimental tutoring studies reports “an overall pooled effect size estimate of 0.37 SD” across PreK–12. Two qualifications travel with it. Effects “tend to be strongest among the earlier grades,” a decline the authors attribute entirely to literacy programs — in mathematics they report a reverse trend, which is good news if you teach secondary math. And effects are “stronger, on average, for teacher and paraprofessional tutoring programs” than for volunteers or parents, though that teacher advantage is driven largely by first-grade Reading Recovery studies. The authors call these moderator findings descriptive, not causal.

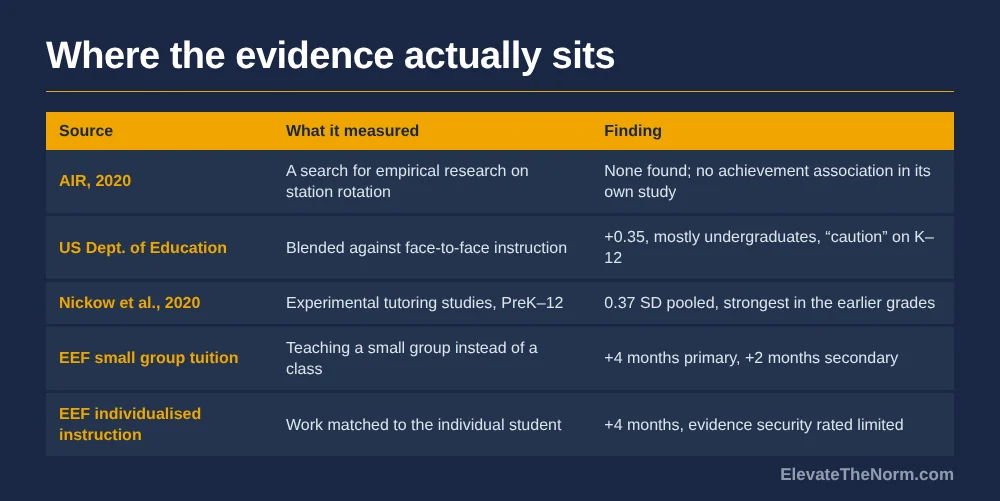
    Table of five sources with what each measured and what it found, including the search that found no empirical research on station rotation and the small-group figures of plus four months in primary and plus two in secondary.
    The rotation itself has no evidence behind it. The teacher station does.

    The EEF’s toolkit entry gives the same shape in school-friendly units: small group tuition averages “four months’ additional progress over the course of a year,” but “impact tends to be greater in primary schools (+4 months) than secondary schools, which has fewer studies overall and a lower impact (+2 months).” Evidence security is rated moderate, and it “lost an additional padlock because a large percentage of the studies were not independently evaluated.”

    The actionable number is group size. “As a rule of thumb, the smaller the group the better,” and “once group size increases above six or seven there is a noticeable reduction in effectiveness.” That single sentence should decide your station design before anything else does. Three stations in a class of thirty puts ten students at the teacher table, which is past the point where the evidence says the thing stops working.

    Does the online practice station do anything?

    Modestly, on limited evidence, and not because it is digital. The EEF rates individualised instruction at “+4 months” of additional progress for very low cost — with evidence security rated “limited.”

    Two findings on that page cut against the usual pitch. Secondary does better than primary here, +4 months against +3 — the opposite of the small-group pattern. And on the technology itself: “approaches using digital technology to individualise instruction show that they are as effective as those without technology.” The software is not the ingredient.

    There is a detail buried in that entry that describes station rotation without naming it. The EEF notes that many technology studies pair the software with small group tuition, “where teachers provide targeted instruction to the pupils that are not engaging with the technology.” That is the model, and the EEF attributes the result to the pairing rather than to the program. Its blunt guidance: individualised instruction “may be better used as a supplement to usual class teaching, rather than a replacement.”

    If you want named programs with rigorous K–12 findings behind them, the federal review above identifies four: Cognitive Tutor Algebra I, LeapTrack, READ 180 and Time To Know. The underlying studies were not read for this article, so no effect sizes are quoted for any of them. That list is also notable for how short it is.

    What does station rotation cost you in time?

    Three transitions in a period you did not previously spend, against a time budget that is already tighter in high school than in elementary school. That trade is the main practical argument against the model, and it gets stronger as students get older.

    Matthew Kraft and Sarah Novicoff’s analysis of one district’s instructional time found that “the average elementary school student in PPSD loses 16 percent of instructional time,” while “the typical middle school student loses 21 percent” and “high school students lose a total of 25 percent.”

    The same paper is the source of a figure that gets misquoted everywhere, so here it is in full: “estimates of off-task behavior, transitions, and wait-time suggest these activities occupy between 17 and 29 percent of instructional time.” That is a range assembled from four other studies, and it bundles off-task behaviour, transitions and wait time together. It is not a measurement of transitions, and anyone telling you transitions eat a quarter of your class has not read the sentence.

    What the figures do support is this: the move costs real minutes, and a 45- or 50-minute secondary period cannot absorb five stations. Keep the count low and the transitions boring.

    How many stations should you have, and how long should they be?

    Two or three stations, sixteen to thirty minutes each, is what teachers running the model actually do. That is prevailing practice reported by AIR, not an outcome study, and it should be read as what works logistically rather than what produces learning.

    AIR found teachers most often used two or three stations rather than four or five, that “about 55% of station rotation teachers reported 16 to 30 minutes at each station, and about 32% reported 10 to 15 minutes,” that most grouped students by similar learning needs, and that about a third regrouped weekly.

    Catlin Tucker, who has written more practical material on this model than anyone, recommends designing three or four distinct stations and running mirrored copies so each half of the room meets the same tasks, at roughly six students per station, with a rotation allowed to run across several days rather than cramming into one period. That is practitioner advice rather than evidence — but six per station is the same number the EEF arrives at from the research, which is a convergence worth taking seriously.

    StationWhat happens thereWhat the evidence saysThe number that governs it
    Teacher-led small groupDirect teaching to a handful of studentsThe only component of the model with a replicated track recordSix or seven students, maximum
    Independent or online practicePractice on content already taughtModest, on limited evidence, and digital is no better than paper+4 months, evidence security rated limited
    Collaborative taskStudents work a task together without youDepends on the task and the roles, not on the rotationNo station-rotation evidence exists
    The rotation itselfMoving students between stations on a timerA search for empirical research on it returned nothingThree transitions you did not previously spend
    What each part of a station rotation is actually buying you, and the number that should decide its design.

    How do you build a station rotation in a 50-minute period?

    Work backwards from the teacher table. Decide how many minutes you need with how many students, and let that decide everything else — the station count, the timing, and whether the rotation finishes today at all.

    1. Name the one thing you need to teach a small group. If you cannot say what you will do at that table that you cannot do from the front, you do not need stations. You need a better lesson.
    2. Divide the class so the teacher table holds six or seven, not ten. In a class of thirty that means four groups, which means the rotation runs over two days. Let it. A group of ten at the teacher table is past the size where the evidence says small-group teaching works.
    3. Build two stations, not four. One teacher-led, one that runs without you. A third only if it genuinely runs without you too. Every station you add is a transition you pay for and a set of instructions you have to write.
    4. Make the independent station practice, not new instruction. The EEF is explicit that individualised instruction works better as a supplement than a replacement, and students teaching themselves new content on a screen while you are busy is the version of this model that fails quietly.
    5. Write the stuck procedure before the lesson. Students at the independent station will get stuck while you are unavailable, and “ask three before me” reads to a teenager as “do not ask.” Give them a written answer key, a worked example, or a named classmate — something that is not a closed door.
    6. Time the transition and make it dull. Same signal, same route, same thirty seconds. The only interesting thing in the room should be the work.
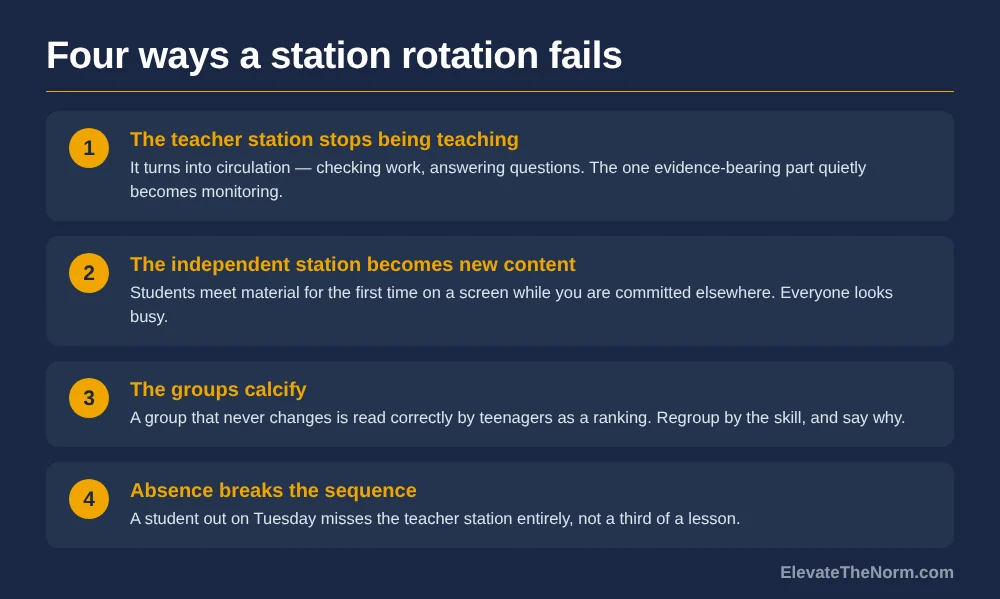
    Four numbered cards naming the teacher station turning into circulation, the independent station becoming new content, groups that never change, and absence removing the teacher station entirely.
    Three of the four are a teacher dropping a step rather than the model failing.

    A note on grouping, because it is the part students notice first. AIR found most teachers group by similar learning needs and only about a third regroup weekly. A group that never changes is read correctly by teenagers as a ranking, and a student who has been in the same group since September has been told something about themselves every week since. Group by the specific skill you are teaching that week, regroup when the skill changes, and say out loud why the groups look different today. Flexible grouping that actually changes is the version of this that does not become tracking inside one classroom.

    What about students without reliable internet or devices?

    Keep the online station inside the room and inside the period. A rotation that works in class and then sends unfinished digital work home turns a device gap into a grade gap, and the gap is well documented.

    In a 2018 Pew Research Center survey of 743 US teens aged 13 to 17, 17 percent said they are often or sometimes unable to complete homework assignments because they do not have reliable internet or a computer. Among teens in households earning under $30,000 a year it was 24 percent, against 9 percent in households above $75,000. A quarter of Black teens said they were at least sometimes unable to finish homework for that reason. Those figures are from 2018 and should be read as dated rather than current.

    The design implication is small and non-negotiable. Whatever happens at the online station finishes at the online station, there is a paper version for the day the network is down, and nothing at that station is the only route to the content. Staker and Horn’s own definition allows pencil-and-paper stations alongside the online one; the model does not require a device per child.

    What goes wrong with station rotation?

    Four things, and three of them are a teacher dropping a step rather than the model failing. The fourth is a question nobody has a good answer to.

    The teacher station stops being teaching. It becomes circulation — checking work, answering questions, putting out fires. The only evidence-bearing component of the structure quietly turns into monitoring, and the rotation keeps running as though nothing changed.

    The independent station becomes unsupervised new content. Students meet material for the first time on a screen while the teacher is committed elsewhere. That is the arrangement the EEF warns against, and it is invisible from the front of the room because everyone looks busy.

    The groups calcify. Covered above, and it is the failure students feel rather than the one that shows up on a test.

    Absence breaks the sequence. A student out on Tuesday misses the teacher station entirely, not a third of the lesson, and no published guidance addresses it. The workable answer is to make the teacher station the one piece you will re-run, in two minutes, one-to-one, rather than the one piece that cannot be repeated. Noise and grading sit in the same category: real problems, no research, and worth deciding before the first rotation rather than during it.

    Clay’s take: the rotation is the furniture, the small group is the instruction

    The structure’s entire job is to buy a teacher twenty minutes with six students. If a design does not deliver that, there is nothing left in it that any evidence supports.

    I am wary of how this model gets sold, because the part being sold is the part with no track record. The pitch leads with the software and the personalization, and the research leads with a teacher at a table with a handful of kids — a practice that predates every piece of technology in the room. A school that buys the platform and leaves the teacher station at ten students has bought the packaging.

    That said, a null result from one descriptive study is not a reason to walk away. Plenty of sensible teaching has less behind it than this, and “no evidence” means nobody has measured it rather than that it has failed. What the thin evidence should change is the claim, not the practice. Run it because you want twenty minutes with six students and cannot get them any other way. Do not run it because a slide said blended learning is worth +0.35, and do not let anyone tell a school board that it is.

    What to do next week

    Try one rotation in one class, with two stations, on content you have already taught. Not new material, not four stations, not a model class period for anyone to watch.

    Put six or seven students at your table and teach them the thing you have never had time to teach a whole class. Give everyone else practice they can genuinely do alone, with a written way out when they get stuck. Then ask yourself one question at the end: was the small group better than what you would have done from the front? That is the whole test, and it has nothing to do with technology.

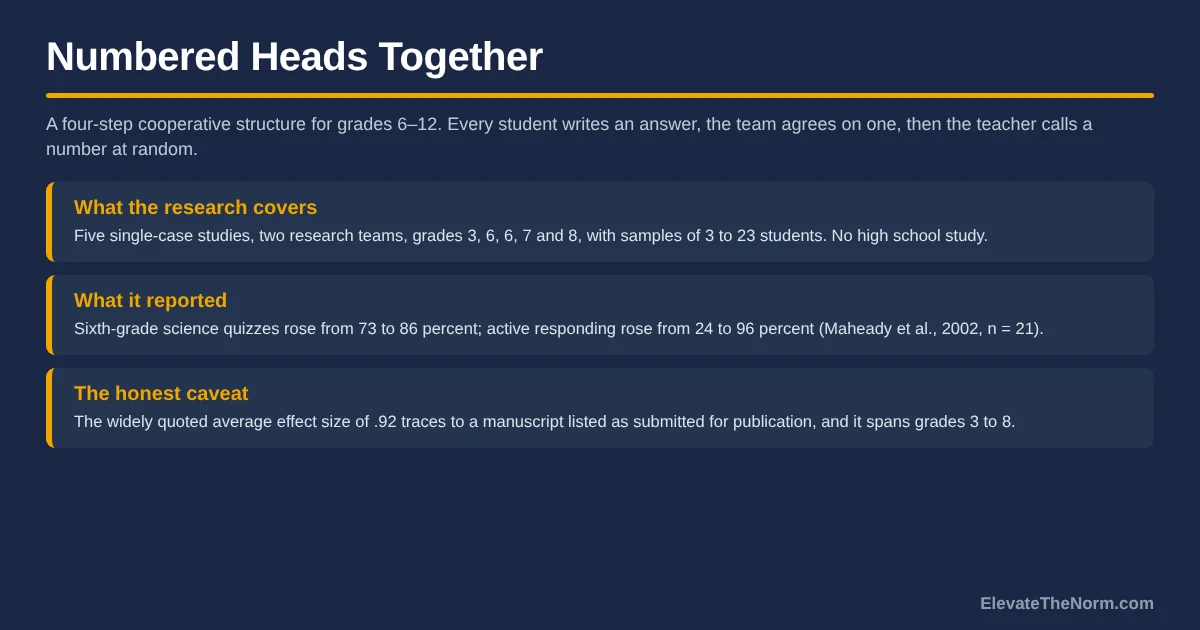
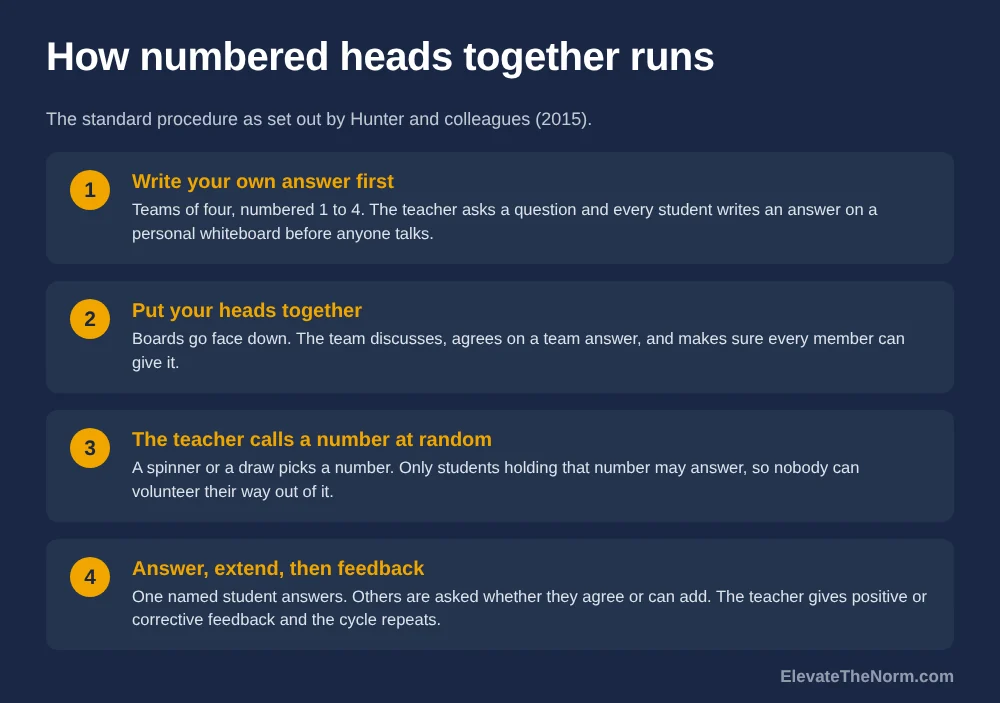
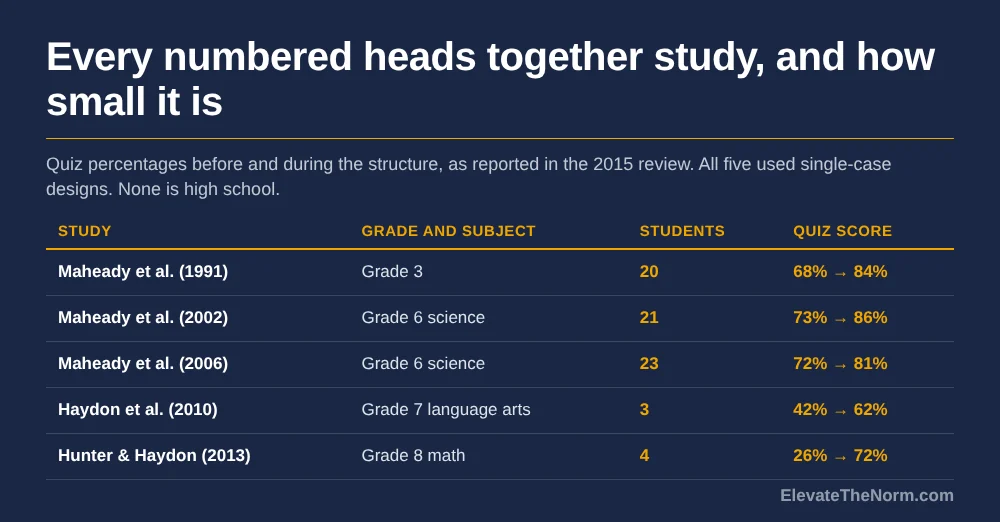
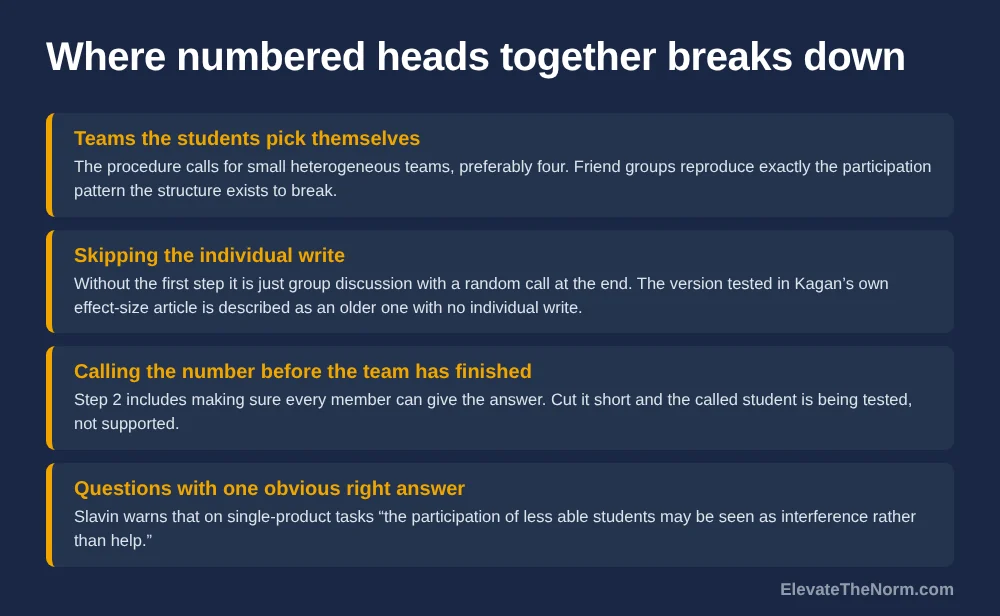
    If the answer is no, the fix is usually upstream. The flipped classroom buys class time a different way, group work roles cover what happens at the station you are not sitting at, numbered heads together is a smaller structure that needs no rotation at all, and activities for student centered learning covers what to put at a station once you have built one.

    Frequently Asked Questions

    What is the station rotation model?

    Station rotation is a blended-learning model in which students in one class rotate on a fixed schedule, or at the teacher’s discretion, among stations inside the same room, with at least one station online. Staker and Horn’s taxonomy distinguishes it from other rotation models by the fact that students rotate through all of the stations rather than only some.

    Does station rotation improve student achievement?

    There is no evidence that it does. A 2020 American Institutes for Research study reports that its literature search found no empirical research articles on station rotation, and its own descriptive study found the model was not associated with significantly higher achievement on standardized assessments. That is an absence of evidence rather than proof of failure, and the study covered grades 4 to 8.

    How many stations should a station rotation have?

    Two or three, with the teacher-led group kept to six or seven students. AIR found teachers most often run two or three stations, with about 55 percent spending 16 to 30 minutes at each. The limiting number comes from the EEF: above six or seven students in a group there is a noticeable reduction in the effectiveness of small-group teaching.

    What is the difference between station rotation and a flipped classroom?

    A flipped classroom moves first-exposure instruction out of the period, usually to video at home, so class time can be spent on practice. Station rotation keeps everything inside the period and moves the students instead, cycling them between a teacher-led group and work they do without you. One changes when instruction happens; the other changes where students are standing.

    Can you do station rotation in a 45-minute class period?

    Yes, with two stations rather than four, and often by letting one rotation run across two days. Three transitions cost real minutes in a period that is already losing time, and secondary students lose more instructional time than elementary students do. Keep the station count low, keep transitions dull and identical, and do not try to finish everything in one sitting.

    Does station rotation require a device for every student?

    No. The model’s own definition requires at least one online station, not one device per child, and it explicitly allows pencil-and-paper stations alongside it. Keeping the online work inside the room and inside the period also avoids pushing it home, which matters because 17 percent of US teens told Pew in 2018 they sometimes cannot finish homework for lack of reliable internet or a computer.

    Is my child only getting a third of the teacher’s attention?

    Less teacher time overall, but more of it directed at them. In a whole-class lesson a student may not be spoken to at all; at a teacher-led station of six, being spoken to is unavoidable. The trade only pays if the small group is genuine teaching rather than the teacher circulating and checking work, which is the most common way this model goes wrong.

    What happens when a student is absent during a station rotation?

    They miss the teacher station entirely, not a third of a lesson, and no published guidance addresses this. The practical fix is to treat the teacher-led portion as the piece you will re-run in two minutes one-to-one, rather than the piece that cannot be repeated. Decide that before the first rotation, not after a student has missed one.

    Sources

    • Staker, H., & Horn, M. B. Classifying K–12 Blended Learning. Innosight Institute (now the Clayton Christensen Institute), May 2012. Full text. Source of the Station-Rotation definition quoted here, the rotation-through-all-stations distinction, the stated purpose of creating a shared language, the statement that the taxonomy leaves out appraisals of quality, and the kindergarten illustration of the model.
    • Fulbeck, E., Atchison, D., Giffin, J., Seidel, D., & Eccleston, M. Personalizing Student Learning With Station Rotation: A Descriptive Study. American Institutes for Research, commissioned by the Overdeck Family Foundation, July 2020. Full text. Source of the finding that the literature search yielded no empirical research articles on station rotation, the thin description of the research base, the null achievement and attendance associations, the authors’ statement that the design does not allow strong causal inference, the two-to-three station and 16-to-30-minute practice figures, the grouping and regrouping findings, and the grade 4–8 scope.
    • Means, B., Toyama, Y., Murphy, R., Bakia, M., & Jones, K. Evaluation of Evidence-Based Practices in Online Learning: A Meta-Analysis and Review of Online Learning Studies. U.S. Department of Education, Office of Planning, Evaluation and Policy Development, revised September 2010. Full text. Source of the +0.35 blended-versus-face-to-face effect, the +0.05 purely-online result, the authors’ statement that most effect sizes are for undergraduate and older students, the caution about generalizing to K–12, and the warning that the effects should not be attributed to the media per se. The copy read for this article was the Boston University mirror.
    • Brodersen, R. M., & Melluzzo, D. Summary of research on online and blended learning programs that offer differentiated learning options (REL 2017–228). Institute of Education Sciences, National Center for Education Evaluation, REL Central, February 2017. Full text. Source of the five-of-176 figure, the seven-of-17 rigorous-design count, the statement that no conclusions can be drawn about effectiveness as a whole, and the four named programs with rigorous positive findings.
    • Fazal, M., & Bryant, M. “Blended Learning in Middle School Math: The Question of Effectiveness.” Journal of Online Learning Research, 5(1), 49–64 (2019). Full text. Source of the 413 sixth-grade sample, the station-rotation framing, the MAP result (d = 0.30) and the opposing STAAR result (d = −0.28), and the authors’ statement that students were not randomly assigned. The study’s reported means were not reproduced here because the published tables and narrative disagree.
    • Nickow, A., Oreopoulos, P., & Quan, V. The Impressive Effects of Tutoring on PreK-12 Learning: A Systematic Review and Meta-Analysis of the Experimental Evidence. NBER Working Paper No. 27476, July 2020. Full text. Source of the 0.37 SD pooled effect, the finding that effects are strongest in earlier grades with a reverse trend in mathematics, the comparison of teacher and paraprofessional tutors against volunteers and parents, and the authors’ description of their moderator analyses as descriptive rather than causal.
    • Education Endowment Foundation. Small group tuition, Teaching and Learning Toolkit, accessed November 2026. Toolkit entry. Source of the four-months average, the primary (+4) against secondary (+2) split, the smaller-the-group rule of thumb, the six-or-seven threshold, the moderate evidence rating, and the note that a padlock was lost because many studies were not independently evaluated.
    • Education Endowment Foundation. Individualised instruction, Teaching and Learning Toolkit, accessed November 2026. Toolkit entry. Source of the +4 months figure and limited evidence security, the secondary (+4) against primary (+3) comparison, the finding that digital approaches are as effective as those without technology, the description of pairing software with small group tuition, and the supplement-rather-than-replacement guidance.
    • Kraft, M. A., & Novicoff, S. Time in School: A Conceptual Framework, Synthesis of the Causal Research, and Empirical Exploration. Annenberg EdWorkingPaper No. 22-653, February 2024. Full text. Source of the Providence figures of 16, 21 and 25 percent of instructional time lost by level, and of the 17-to-29 percent range, which is synthesised from four prior studies and covers off-task behaviour, transitions and wait time together rather than transitions alone.
    • Anderson, M., & Perrin, A. “Nearly one-in-five teens can’t always finish their homework because of the digital divide.” Pew Research Center, 26 October 2018. Report. Source of the 17 percent overall figure, the 24 percent and 9 percent income comparison, the figure for Black teens, and the sample of 743 teens aged 13 to 17 surveyed in spring 2018.
    • Tucker, C. “FAQ: Station Rotation Model” and “Addressing Station Rotation Challenges.” catlintucker.com, December 2022 and April 2018. FAQ post. Source of the mirrored-station design, the three-to-four station recommendation, roughly six students per station, and rotations running across several days. This is practitioner advice from a teacher and author, not research, and is labelled as such in the text.

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • The Think Aloud in Grades 6–12: How to Model Thinking Students Can’t See

    The Think Aloud in Grades 6–12: How to Model Thinking Students Can’t See

    By Clay Shumate

    A think aloud is a teacher narrating their own reasoning out loud while reading or solving, so students can hear the moves an expert normally makes in silence. Federal reviewers rate the evidence for explicit comprehension-strategy instruction with adolescents as strong, and thinking aloud is the method they name for delivering it.

    Key Takeaways

    • A think aloud is narration of your own thinking, not reading aloud well. Barak Rosenshine put the purpose plainly: thinking aloud gives novices “a way to observe ‘expert thinking’ that is usually hidden”. If a student could have got the same thing from a recording of the text, it was not a think aloud.
    • There is no effect size for a think aloud, and anyone quoting one is quoting something else. The numbers belong to comprehension-strategy instruction as a package. The What Works Clearinghouse rates that package strong for adolescent readers; the think aloud is the delivery mechanism inside it.
    • The one head-to-head test came back empty. When researchers pitted a narrated model against a silent written worked example with 13- and 14-year-olds, the format made no difference to learning — and the authors flag near-ceiling scores that weaken even that.
    • The teachers best equipped to do it find it hardest, and the federal panel says so itself. Its roadblocks section warns that teachers “will need to become conscious of many of the reading processes that are automatic for them.” Expertise is what makes the moves worth hearing and what makes them hard to narrate.
    • Name the population before borrowing the result. The federal guides behind this evidence counted fourth and fifth graders as adolescents and, in the 2022 update, rested a strong rating on 34 studies of students with reading difficulties. That is not a general grades 6–12 claim.

    What is a think aloud?

    A think aloud is a teacher speaking their own reasoning out loud while working through a text or a problem in front of students. The point is not the content. The point is the decision-making — the pause, the re-read, the guess, the correction.

    Reading Rockets describes the strategy as “eavesdropping on someone’s thinking” and traces it to Beth Davey’s 1983 article in Journal of Reading. That paper is paywalled and was not read for this article, so it is credited as the origin point and nothing more.

    Rosenshine’s framing is the useful one. In Principles of Instruction, he lists thinking aloud twice: once under “provide models,” where he writes that “students need cognitive support to help them learn to solve problems”, and once under scaffolding, where he counts “thinking aloud by the teacher as he or she solves the problem” as a temporary support. A support, not a performance.

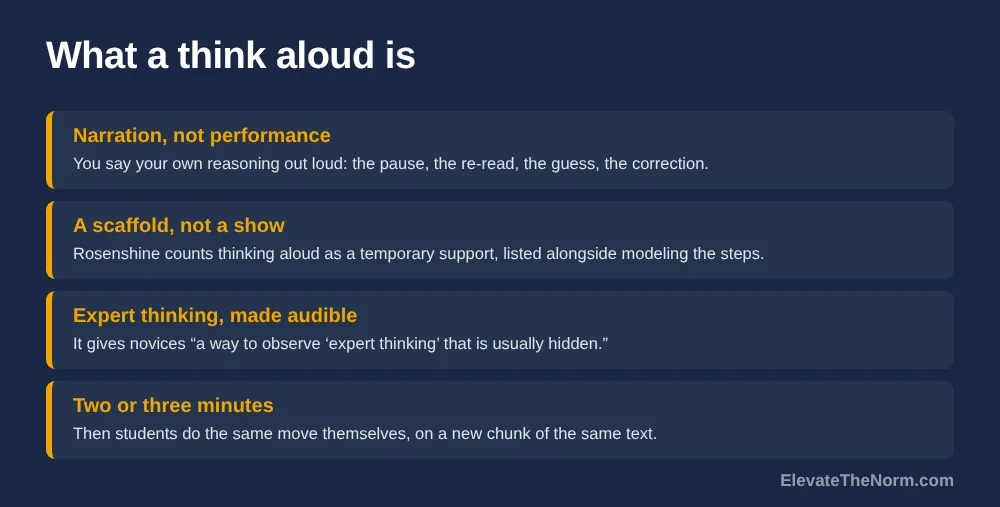
    Four stacked panels describing a think aloud as narration rather than performance, a scaffold rather than a show, expert thinking made audible, and two or three minutes long.
    The four things that distinguish a think aloud from reading a passage aloud.

    The thing most often called a think aloud is usually one of three near neighbours. The difference is what the student actually hears.

    MoveWhat the student hearsWhat it teachesEvidence it rests on
    Think aloudYour reasoning, including the uncertainty and the correctionThe decision an expert makes and whyNamed by the IES panel as how to deliver strategy instruction rated strong
    Reading aloudThe text, well performedFluency and phrasing, at bestShanahan calls it “poor modeling” if the goal was comprehension
    Worked exampleNothing — it is writtenThe steps that survivedNo worse than narration in the one head-to-head test
    Explaining a strategyA description of what good readers doThe label for the moveThe IES guide treats defining a strategy as the step before modeling it
    Four things that get called modeling. Only the first one shows a student a decision being made.

    Is the think aloud strategy research based?

    The instruction it delivers is strongly evidenced. In the IES practice guide Improving Adolescent Literacy, the panel states that for direct and explicit comprehension-strategy instruction, “the level of evidence supporting this recommendation to be strong.”

    That guide rates five recommendations. Explicit vocabulary instruction: strong. Explicit comprehension-strategy instruction: strong. Extended discussion of text meaning: moderate. Motivation and engagement: moderate. Intensive individualized intervention from trained specialists: strong.

    And the guide names the method. Teachers are told to “model how to use the strategies by thinking aloud with a text,” with explaining and modeling described as beginning with “defining each of the strategies for students.” The think aloud is not a nice extra inside that recommendation. It is how the recommendation gets carried out.

    The 2022 update, Providing Reading Interventions for Students in Grades 4–9, is more specific about what the rating rests on: “The WWC and the expert panel assigned a strong level of evidence to this recommendation based on 34 studies of interventions for improving reading comprehension in students with reading difficulties.” Twenty-three met WWC standards without reservations and eleven met them with reservations.

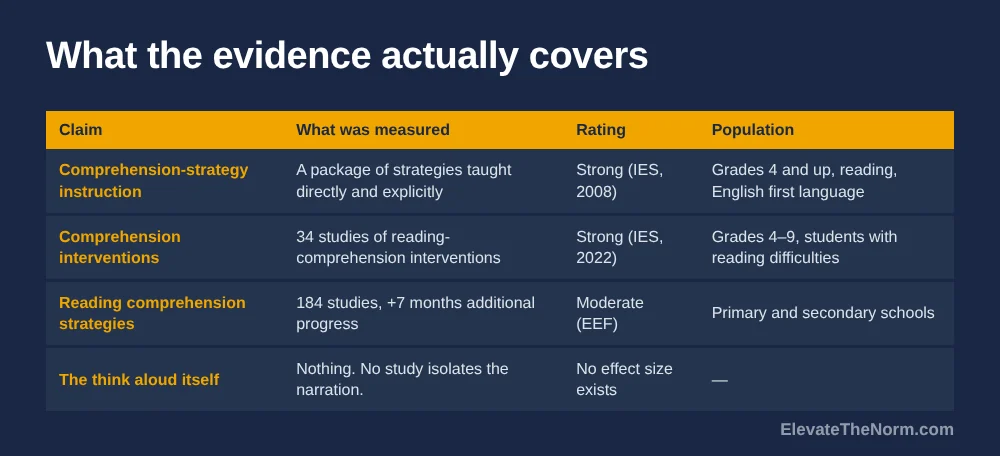
    What there is not, anywhere, is an effect size for a think aloud. Every available number measures a larger package that contains the narration — strategy instruction, or a comprehension intervention. Isolating narration from the strategy it teaches has not been done at scale.

    The best quantified figure sits with the Education Endowment Foundation, which puts reading comprehension strategies at “+7 months” additional progress across 184 studies, summarised as “high impact for very low cost based on moderate evidence.” The EEF also says the approach “is effective across both primary and secondary schools,” which is the line that makes any of this relevant to a grades 6–12 room.

    Read the caveats the EEF publishes alongside it, because they are the reason to trust the rest. “The topic lost a padlock because a large percentage of the studies were not independently evaluated.” “Another padlock was lost because there is a large amount of unexplained variation between the results.” And the sentence every teacher should staple to every toolkit figure: “All reviews contain some variation in results, which is why it is important to look behind the average.”

    Table of four claims with what was measured, the evidence rating and the population, ending with the row stating that no effect size exists for the think aloud itself.
    Every rating belongs to the package the think aloud sits inside, not to the narration itself.

    Note what that +7 months is attached to. The EEF page does not use the phrase “think-aloud” either. It says modelling, and “teachers often use metacognitive talk to model strategies.” So the honest sentence is this: comprehension-strategy instruction has a strong, quantified evidence base, and thinking aloud is how it is delivered. There is no think-aloud effect size, and a page that gives you one has made it up or mislabelled something else.

    Does narrating out loud beat a silent worked example?

    On the one direct test available, no. Vincent Hoogerheide, Sofie Loyens and Tamara van Gog compared a narrated model against a written worked example with Dutch secondary students and found no difference in learning. Nobody has shown narration wins, and nobody has shown it loses.

    The design: three conditions on a probability task — a written worked example with pictures of each problem state, a modeling example with a visible person narrating and demonstrating, and the same narration with pictures instead of a visible model. In the first experiment, 78 students averaging 14.3 years old in the highest Dutch secondary track, cut to 62 after removing students who already knew the content. On total test score there was no main effect of condition, F < 1, and no interaction with test moment, p = .268. Mental effort did not differ. A second experiment with 134 students replicated it.

    The authors’ own caution belongs in the same breath: performance was near ceiling on the posttests, so the comparison is weaker than a clean null. Their published summary says only that “the format of examples does not affect learning outcomes for this task.” One task, one country, one academic track.

    So the case for thinking aloud is not that talking is magic. Rosenshine lists worked examples as a separate, equally legitimate form of modeling. The case is narrower and sturdier than the usual pitch: somebody has to make the invisible move visible, and in most classrooms nobody else can.

    Why is thinking aloud harder for experienced teachers?

    Because the moves worth narrating have gone automatic. The IES panel puts this in its own roadblocks section: teachers “may find it particularly challenging to model their own thinking,” and “will need to become conscious of many of the reading processes that are automatic for them.”

    There is a research name for the wider problem. Mitchell Nathan, Kenneth Koedinger and Martha Alibali call it the expert blind spot: because of advanced content knowledge, teachers make assumptions about student learning that “turn out to be in conflict with students’ actual performance.”

    Their numbers are uncomfortable. Asked to rank algebra problems by difficulty, the 39 high school teachers in their sample ranked story problems hardest. Students did the opposite: two samples of ninth graders who had finished a year of algebra solved equations correctly less than 30 percent of the time and verbal problems more than 50 percent, a gap significant at p < .01. The high school teachers’ rankings bore no relationship at all to student performance — a rank correlation of zero. The 30 middle school teachers in the same study were accurate.

    Be precise about what that shows. It is mathematics problem-difficulty judgment, not reading, and it is not a study of think alouds. What it establishes is that subject expertise does not automatically produce an accurate model of student thinking — which is exactly the thing a think aloud is supposed to supply. The guide’s own fixes are unglamorous: coaching, professional development, and practising the think aloud on your own text before you teach it.

    What do you actually say during a think aloud?

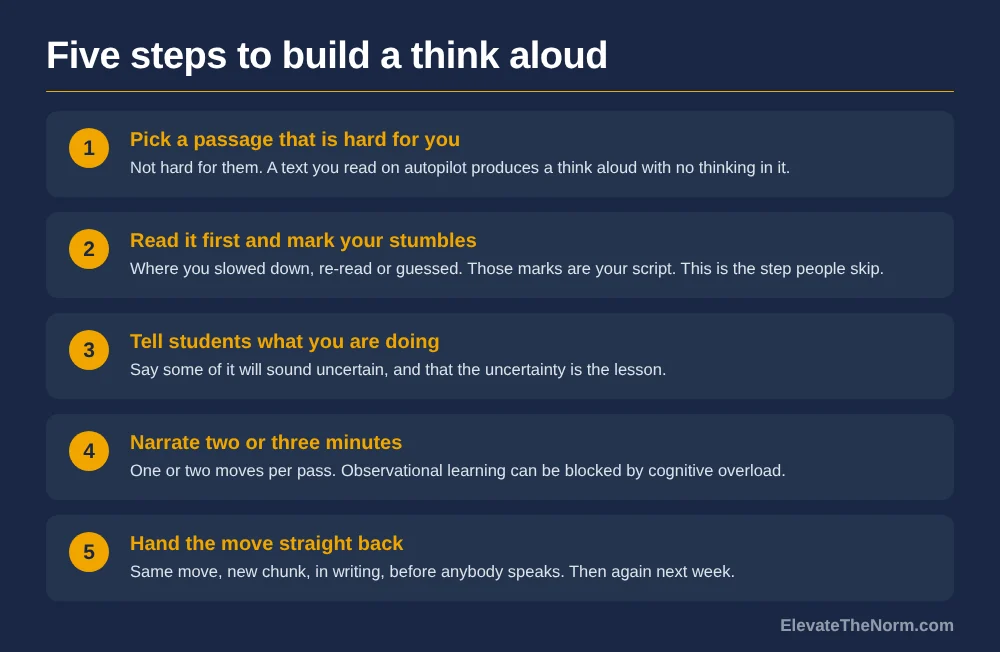
    You say the part you would normally only think: naming confusion out loud, stating a guess before you know it is right, correcting yourself in front of the class. Five steps cover the routine, and the preparation matters more than the delivery.

    1. Pick a passage or problem that is genuinely hard for you. Not hard for them — hard for you. A text you can read on autopilot will produce a think aloud with no thinking in it, which is the roadblock the federal panel names.
    2. Read it in advance and mark your own stumbles. Where did you slow down, re-read, look something up, or guess? Those marks are your script. This is the step most people skip, and skipping it is why most classroom modeling is a recap rather than a demonstration.
    3. Tell students what you are about to do and why. Say that you are going to talk through your own reading, that some of it will sound uncertain, and that the uncertainty is the lesson. Teenagers read an adult thinking out loud as either honesty or incompetence, and which one depends on whether you framed it.
    4. Narrate two or three minutes, not ten. Keep it to one or two moves per pass. Observational learning, as Timothy Shanahan puts it, “can be blocked by cognitive overload”; a long narration is a lecture about reading.
    5. Hand the same move to them immediately, on a new chunk of the same text. One move, one chunk, in writing, before anybody speaks. Then do it again next week on different material, because, as Shanahan notes, “even when teachers do model for their students, it is often a one-time affair.”
    Five numbered cards: pick a passage that is hard for you, read it first and mark your stumbles, tell students what you are doing, narrate two or three minutes, and hand the move straight back.
    The preparation matters more than the delivery.

    One refinement worth testing: Shanahan reports research suggesting that contrasting an expert model with a flawed one beats expert models alone, citing Rohbanfard and Proteau (2011). That study was not read for this article, so treat it as his reading rather than a settled finding. In practice it means thinking aloud badly on purpose, then well, and asking students what changed.

    Does the think aloud work outside English class?

    Yes, and the strongest secondary content-area evidence is in history. Rosenshine states that modeling and worked examples “have been used successfully in mathematics, science, writing, and reading comprehension,” and he describes teachers asking students to think aloud during mathematical problem solving as a way of checking understanding.

    The cleanest study is Susan De La Paz and colleagues’ 18-day historical reading and writing curriculum, built on cognitive apprenticeship — the modeling, coaching and fading sequence Rosenshine names in his scaffolding principle. Taught across a school year with culturally and academically diverse adolescents, it produced positive and significant results on every writing outcome. For students described as basic readers, the effect sizes against control were 0.45 for historical writing, 0.32 for overall writing quality and 0.60 for essay length. The record states no sample size, so none is claimed here.

    What that study does not do is isolate the think aloud. It tests a whole curriculum in which modeling is one component, which is the same limitation as every number on this page. Treat it as evidence that teaching disciplinary thinking explicitly pays in a content classroom, not as a measured return on narration.

    If you teach a content subject, the moves worth narrating are yours, not an English teacher’s. How you decide whether a source is trustworthy. How you read a graph before its caption. How you notice that an equation and a word problem are the same question. Those are not generic reading strategies, and nobody else is going to model them.

    Can students do think alouds themselves?

    They can, in pairs, with training and a familiar task — and the evidence is thin and mostly not about teenagers. The one controlled study found real gains that did not survive the removal of prompting.

    Michael Pate, George Wardlow and Donald Johnson randomly assigned 30 undergraduates in a power technology course to think-aloud pair problem solving or to a control, then had them diagnose faults in small engines. On the electrical task, 16 of 18 in the experimental group succeeded against 5 of 12 controls, χ²(1) = 5.56, p ≤ .02. On the fuel and intake task, 10 of 12 against 8 of 18, χ²(1) = 4.54, p ≤ .03. Completion times did not differ.

    Two limits, and the second matters most. These were 30 undergraduates in one hands-on course at one institution, published in a student research journal. And the authors noted the skills did not appear to transfer once the external prompting was taken away. A structure that only works while you are running it is a scaffold, not a skill.

    If you do try it, the structure matters more than the prompt. Everyone writes their reasoning before anyone speaks, students narrate in pairs rather than to the room, and the student who reads worst does not go first. Saying “I don’t understand this” out loud in front of people you sit with all year costs something real, and a teenager who declines is making a rational trade, not refusing to work.

    Jennifer Branch’s work with junior high and grade 9 students is the useful warning. She found think alouds “work well with students who are already familiar with the task being assigned”, that some students were “not experienced in problem-solving aloud” and found the method “strange and awkward,” and that in one case the adult present became “a mental crutch.” She was using think alouds as a research method rather than as instruction, but the lesson transfers: do not ask a class to think aloud cold. If you want students reasoning out loud inside a structure that has been studied as instruction, reciprocal teaching is the better-evidenced route, and it gives every student a named job instead of a turn.

    How do you know whether the think aloud worked?

    By what students produce on the next chunk of text, not by how the narration felt. The check is whether the specific move you narrated shows up in their work within the same period.

    Make it small and written. If you modeled using surrounding sentences to work out an unfamiliar word, give them one unfamiliar word in the next paragraph and ask for the clue they used, not just the meaning. If you modeled deciding whether a source is reliable, give them one source and ask for the sentence that made them trust it or not. You are marking the move, not the answer.

    Rosenshine points at the symmetric check: “Teachers also can study their students’ thought processes by asking them to think aloud during problem solving.” Have one student narrate while you listen. Two minutes of that tells you more than an exit ticket, and it usually tells you the step you considered obvious is the one that never landed — the expert blind spot, arriving in person.

    Do not grade the narration itself. A student assessed on how articulate their thinking sounds will perform confidence instead of reporting confusion, and the confusion is the whole content of a think aloud. Grade what they do with the move afterwards.

    Where does the evidence run out?

    Sooner than the strategy’s popularity suggests. The evidence base behind thinking aloud is overwhelmingly about reading comprehension, drawn largely from upper-elementary and middle grades, and in its strongest modern form from students with reading difficulties rather than a general population.

    The 2008 federal guide says so in its own front matter: “The panel purposefully included students in 4th and 5th grades within the realm of adolescents.” Its search “focused only on studies of reading programs conducted within a school or clinical setting,” and covered students “whose first language was English.” The 2022 guide covers grades 4–9, and its strong rating rests on interventions for struggling readers.

    And the practice is close to absent from real lessons. Timothy Shanahan, a reading researcher, judges modeling “used so rarely and so poorly” in classrooms — practitioner commentary rather than a trial, but it has company in the research. Avishag Reisman’s study of document-based history instruction across five San Francisco high schools reports that “only nine whole-class text-based discussions were identified in over 100 videotaped classroom lessons.” That is about discussion rather than modeling, and her intervention was not a think-aloud trial. But the shape of the finding is the point: the talk we recommend most confidently is the talk that happens least.

    What does not exist: a think-aloud effect size, a grades 9–12 trial of teacher narration, and any evidence that narrating beats demonstrating silently. If a professional development slide gives you one of those, ask where it came from.

    Clay’s take: it is the cheapest thing on the list and the most avoided

    A think aloud costs nothing, needs no materials, and fits in three minutes. It is also the one instructional move that requires you to be visibly uncertain in front of thirty teenagers, which is why it does not happen.

    The honest argument for it is not the evidence base, because the evidence base belongs to the package it sits inside. The argument is structural. Every subject has moves experts make without noticing, students are graded on those moves, and nobody has ever said one of them out loud. A worked example on the board shows the steps that survived. It does not show the three you abandoned, and the abandoning is the skill.

    What I would push back on is how this gets taught to teachers. “Model your thinking” shows up on observation rubrics as though it were a thing you either do or do not do. The federal panel’s own roadblocks section is more honest than most training: it says you will have to make your automatic processes conscious first, and it recommends coaching to get there. A teacher who tries it cold and produces a lifeless recap has not failed at teaching — they have run into the thing the research predicted. I would rather see one prepared three-minute think aloud a week, on a text the teacher genuinely found hard, than a rubric line satisfied by reading aloud with feeling.

    What to do next week

    Pick one text you teach that you have never found easy. Read it with a pen and mark every place you hesitated. Those marks are a script you did not have to write.

    Then do three minutes of it out loud, once, naming one move. Hand that move straight back to students on the next paragraph and make them write the clue they used. If what comes back is blank, the step you thought was obvious is the one to narrate next time — and you have just found your own blind spot for the price of one paragraph.

    If you want the surrounding structure, scaffolding strategies covers building a support and taking it away again, annotation strategies covers what students do in the margin once they know the move, productive struggle covers how long to wait before you narrate anything at all, and dual coding covers what to put on the screen while you talk.

    Frequently Asked Questions

    What is a think aloud in teaching?

    A think aloud is a teacher narrating their own reasoning out loud while reading a text or solving a problem, so students can hear the decisions an expert normally makes in silence. The content is not the point; the pause, the re-read, the guess and the correction are. If a recording of the text would have given students the same thing, it was not a think aloud.

    What is the difference between a think aloud and reading aloud to the class?

    Reading aloud performs the text. A think aloud narrates the thinking around the text. Timothy Shanahan is blunt about the confusion: reading a passage aloud without narrating any thought is, in his words, “poor modeling” if the goal was comprehension. The test is simple. Did students hear a decision being made, or only hear the words?

    How long should a think aloud be?

    Two or three minutes, then student work. The limit is working memory, not attention span: a student listening to extended narration has nothing left over to notice the move being made. Shanahan’s advice is to keep demonstrations “brief and to the point” so they do not overwhelm the rest of the lesson. Narrate one or two moves per pass, not everything you notice.

    Is the think aloud strategy research based?

    The instruction it delivers is. The IES practice guide on adolescent literacy rates direct and explicit comprehension-strategy instruction as strong evidence, and tells teachers to model the strategies by thinking aloud with a text. The 2022 update assigned a strong rating based on 34 studies of comprehension interventions for students with reading difficulties. There is no separate effect size for the narration itself.

    Does a think aloud work in math, science or history?

    Yes, and the moves worth narrating are subject-specific. Rosenshine reports that modeling and worked examples “have been used successfully in mathematics, science, writing, and reading comprehension,” and the strongest secondary content-area study is a history writing curriculum built on cognitive apprenticeship, which produced significant gains on every writing outcome. How you judge a source or read a graph is nobody else’s job to model.

    How do I model my thinking when the task feels automatic to me?

    Pick material that is genuinely hard for you, then read it in advance with a pen and mark every place you hesitated. Those marks are your script. The federal guide names this exact problem in its roadblocks section: teachers “will need to become conscious of many of the reading processes that are automatic for them,” and it recommends coaching rather than willpower.

    My child says the teacher just talks through the reading. Is that teaching?

    If the teacher is narrating how they decide what a passage means, yes, and it is one of the better-evidenced things a teacher can do. Reading tests ask students to make those decisions, and most students have never seen an adult make one out loud. The check is what happens next: a good think aloud is short and is followed by students doing the same move themselves.

    Can students do think alouds themselves?

    They can, in pairs, with training and a familiar task. The one controlled study found real gains for think-aloud pair problem solving, but with 30 undergraduates, and the authors noted the skills did not transfer once prompting stopped. With teenagers, have everyone write their reasoning before anyone speaks, keep it to pairs, and never start with the student who reads worst.

    Sources

    • Kamil, M. L., Borman, G. D., Dole, J., Kral, C. C., Salinger, T., & Torgesen, J. Improving Adolescent Literacy: Effective Classroom and Intervention Practices (NCEE 2008-4027). Institute of Education Sciences, National Center for Education Evaluation, What Works Clearinghouse practice guide, August 2008. Full text. Source of the strong level of evidence for direct and explicit comprehension-strategy instruction, the five recommendation ratings, the instruction to model strategies by thinking aloud with a text, the roadblock about processes that are automatic for teachers, and the population limits quoted here.
    • Vaughn, S., Kieffer, M. J., McKeown, M., Reed, D. K., Sanchez, M., St. Martin, K., & Wexler, J. Providing Reading Interventions for Students in Grades 4–9 (WWC 2022007). Institute of Education Sciences, National Center for Education Evaluation, March 2022. Full text. Source of the strong evidence rating based on 34 studies of students with reading difficulties, the 23-and-11 standards split, and the scripted teacher modeling example quoted here. Only the first third of the guide was read for this article.
    • Rosenshine, B. “Principles of Instruction: Research-Based Strategies That All Teachers Should Know.” American Educator, Spring 2012, p. 12. American Federation of Teachers. Full issue. Source of the expert-thinking-that-is-usually-hidden line, thinking aloud as a cognitive support and as a scaffold, worked examples as a separate form of modeling, the list of subjects in which modeling has been used successfully, and asking students to think aloud as a check for understanding. Rosenshine reports no effect size for modeling.
    • Education Endowment Foundation. Reading comprehension strategies, Teaching and Learning Toolkit, last updated October 2025. Toolkit entry. Source of the +7 months figure, the high-impact-for-very-low-cost-based-on-moderate-evidence summary, the 184 studies, the statement that the approach is effective across primary and secondary schools, the two reasons padlocks were lost, and the guidance on programme duration.
    • Hoogerheide, V. Effects of Observing and Creating Video Modeling Examples on Cognitive and Motivational Aspects of Learning. Doctoral dissertation, Erasmus Universiteit Rotterdam, 2016; chapter 2 published as Hoogerheide, Loyens & van Gog, Computers in Human Behavior, 41, 80–91 (2014). Full text. Source of the three example formats, the Dutch secondary samples and ages, the null effect of condition, the non-significant interaction, the replication in experiment 2, and the authors’ near-ceiling caution.
    • Nathan, M. J., Koedinger, K. R., & Alibali, M. W. “Expert Blind Spot: When Content Knowledge Eclipses Pedagogical Content Knowledge.” Proceedings of the Third International Conference on Cognitive Science, USTC Press, 2001. Full text. Source of the expert blind spot description, the ninth-grade equation-versus-verbal-problem performance gap, and the finding that the 39 high school teachers’ difficulty rankings were unrelated to student performance while the 30 middle school teachers’ were accurate. This is mathematics problem-difficulty judgment, not reading, and not a study of think alouds.
    • Shanahan, T. “Does ‘Modeling’ Have a Place in High Quality Literacy Teaching?” Shanahan on Literacy, 4 January 2020. Post and comments. Source of the used-so-rarely-and-so-poorly judgment, the cognitive-overload caution, the one-time-affair observation, the poor-modeling line about reading aloud for fluency, the preference for demonstration over model, and his report of Rohbanfard and Proteau on flawed versus expert models. This is practitioner commentary by a reading researcher, not a trial, and the studies he cites were not read for this article.
    • De La Paz, S., Monte-Sano, C., Felton, M., Croninger, R., Jackson, C., & Worland Piantedosi, K. “A Historical Writing Apprenticeship for Adolescents: Integrating Disciplinary Learning With Cognitive Strategies.” Reading Research Quarterly, 52(1), 31–52 (2017). Repository record with abstract. Source of the 18-day cognitive-apprenticeship history curriculum, the positive and significant results on all writing outcomes, and the basic-reader effect sizes of 0.45, 0.32 and 0.60. The record states no sample size, so none is given here; the full text would not render and only the record was read.
    • Pate, M. L., Wardlow, G. W., & Johnson, D. M. “Effects of thinking-aloud pair problem solving on the troubleshooting performance of undergraduate students in a power technology course.” Discovery (Dale Bumpers College, University of Arkansas), Vol. 5, Art. 14, 59–64, Fall 2004. Full text. Source of the 30-undergraduate random assignment, both success-rate comparisons with their chi-square statistics, the non-significant completion times, and the authors’ observation that the skills did not appear to transfer without prompting.
    • Branch, J. L. “Using Think Alouds, Think Afters, and Think Togethers to Research Adolescents’ Inquiry Experiences.” Alberta Journal of Educational Research, 52(3), 148–159, Fall 2006. Full text. Source of the finding that think alouds work well with familiar tasks, the difficulty of balancing familiarity and automaticity with junior-high-aged adolescents, students finding the method strange and awkward, and the mental-crutch observation. Branch studies think alouds as a research method rather than as instruction.
    • Reisman, A. Reading Like a Historian: A Document-Based History Curriculum Intervention in Urban High Schools. Doctoral dissertation, Stanford University School of Education, 2011. Record with abstract. Source of the nine whole-class text-based discussions in over 100 videotaped lessons, and of the significant main effects on all four outcomes across five San Francisco high schools. The record reports no effect sizes and does not mention teacher modeling; only the record and abstract were read.
    • Reading Rockets (WETA). Think-Alouds, classroom strategy page, and Meier, J., “How much is too much strategy instruction?”, Sound It Out blog, 3 May 2012. Strategy page. Source of the eavesdropping description, the Davey (1983) citation, the Willingham collateral-damage objection as relayed by Reading Rockets, and the statement that strategies are learned quickly and can provide a short-term boost. The eavesdropping phrase is unattributed on that page; Davey (1983) is paywalled and was not read.

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • Numbered Heads Together: How the Structure Works and What the Evidence Really Says

    Numbered Heads Together: How the Structure Works and What the Evidence Really Says

    By Clay Shumate

    Numbered heads together is a cooperative structure where students in numbered teams of four each write an answer, agree on a team answer, then wait for the teacher to call one number at random. Reported quiz gains run from 9 to 46 percentage points — across five small single-case studies, none of them in high school.

    Key Takeaways

    • The random call is the whole point. Nobody knows who will answer until after the team has agreed, so there is no way to volunteer out of it and no way to sit back and let the strongest student carry it.
    • The evidence is real, consistent and very small. Five single-case studies covering grades 3, 6, 6, 7 and 8, with samples of 3 to 23 students. Every one found gains. None was a randomised trial and none was in high school.
    • It was produced almost entirely by two research teams. The authors of the 2015 review say so plainly: “To date, empirical evidence has been collected primarily by two research teams” — and several of those authors wrote the studies the review summarises.
    • The effect size everyone quotes has a weak chain of custody. The figure of .92 comes from Kagan’s own magazine, averages seven comparisons across grades 3 to 8, and is cited in the research literature to a manuscript listed as submitted for publication.
    • The cooperative-learning research it leans on is about something slightly different. Slavin’s syntheses found that group goals plus individual accountability are what make group work raise achievement — but his individual accountability means a team reward based on each member’s own quiz score, which is not what a random call does.

    What is numbered heads together?

    Numbered heads together is a cooperative learning structure in which small mixed teams of four are numbered off, answer a question individually in writing, agree on one team answer, then find out which number the teacher has drawn at random to give it.

    It is a questioning routine with a built-in reason for every student to be ready.

    Numbered graphic of the four steps of numbered heads together: write your own answer first, put your heads together, the teacher calls a number at random, then answer, extend and give feedback.
    The four steps of numbered heads together, following the standard procedure described by Hunter and colleagues in 2015.

    It belongs to the same family as the other structures on this site — think pair share, the jigsaw method, and peer tutoring — all of which sit under cooperative learning as the umbrella. What distinguishes this one is the delay. Students commit to an answer, then help each other, then discover who is accountable for saying it out loud. The order matters, and most classroom versions get it wrong.

    How do you run numbered heads together, step by step?

    The procedure set out by Hunter and colleagues runs in a repeating cycle of four moves. A full round on one question takes two or three minutes once students know the routine.

    1. Form small heterogeneous teams and number off. The review specifies teams “preferably with four members,” numbered 1 to 4. Heterogeneous means you build them, not the students.
    2. Give every student something to write on. The studies used a personal dry-erase board, a marker and a cloth. Paper works; the point is that each student produces an answer with their own hand.
    3. Ask the question, then make everyone answer it alone. Students write their own answer and turn the board face up in front of them before any discussion happens.
    4. Heads together. Boards go face down. The team discusses, settles on a team answer, and — this is the step that gets cut — makes sure every member can give it.
    5. Draw a number. A spinner, a deck of cards, a dice. Students holding that number stand or raise a hand, and the teacher picks one of them.
    6. Answer, then extend. The named student answers. The teacher then asks others whether they agree or have something to add, which keeps the rest of the room in the question.
    7. Feedback, recognition, reset. Positive or corrective feedback, recognition for the team’s effort, boards wiped, next question.

    The review publishes a 15-item observer checklist for watching the routine run over at least twenty minutes, which is a useful signal in itself: these are not loose suggestions, they are the conditions the studies tested.

    Does numbered heads together actually work?

    In every published study, yes — and the published studies are five in number, all small, all single-case designs, and all below grade 9. Quiz scores rose in all five and on-task behaviour rose in the four that measured it.

    Table of the five numbered heads together studies showing author and year, grade and subject, number of students from 3 to 23, and quiz percentages before and during the structure.
    Every numbered heads together study in the 2015 review, with its grade level, sample size and reported quiz change.
    StudyGrade and subjectStudentsQuiz scoreOn-task behaviour
    Maheady et al. (1991)Grade 3 social studies2068% → 84%39% → 71%
    Maheady et al. (2002)Grade 6 science2173% → 86%Active responding 24% → 96%
    Maheady et al. (2006)Grade 6 science2372% → 81%, and 89% with incentivesNot reported in the review’s table
    Haydon et al. (2010)Grade 7 language arts342% → 62%63% → 96%
    Hunter & Haydon (2013)Grade 8 mathematics426% → 72%48% → 86%

    The sixth-grade science results are the ones closest to a general secondary classroom. In the 2002 study, 21 students went from a 73 percent average under whole-group question and answer to 86 percent under the structure, and the proportion of students actively responding went from 24 percent to 96 percent. That second number is the more interesting one. It is not a claim about learning; it is a measurement of how many students in the room were doing anything at all.

    The two studies with the largest gains have the smallest samples. Haydon, Maheady and Hunter (2010), published in the Journal of Behavioral Education, ran with three students with disabilities in seventh-grade language arts. Hunter and Haydon (2013) ran with four students in a self-contained class for students with emotional and behavioural disorders. Those are real findings about real students and they are not estimates of what will happen in a class of 28.

    Why is the evidence base thinner than it looks?

    Because five single-case studies from two research teams, with no high school data and no randomised trial, is a thin base to carry a strategy that appears in every cooperative learning handbook. The authors of the review say this themselves.

    Their stated limitations are worth quoting in order. They write that “there is need for additional replications across geographic locations, age/grade levels” and settings; that “to date, empirical evidence has been collected primarily by two research teams”; and that longer durations and measures of generalisation and maintenance are needed. The review also lists Maheady and Hunter among its own authors, which does not make the findings wrong but does mean the field has not yet been checked by anyone outside it.

    Two of the five studies used the same sixth-grade science teacher in the same small urban district, a teacher with 27 to 28 years of experience. That is a strong implementation under the best possible conditions. It is not evidence about a second-year teacher with five preps.

    Then there is the number everyone repeats. Kagan’s own article reports “the average positive effect size for Kagan Structures was .92” and says the experiments examined grades 3 through 8. The 2015 review cites the same .92 figure and attributes it to a source its reference list describes as a manuscript submitted for publication. So the most quoted figure in this literature comes from a vendor’s magazine, averages seven comparisons drawn from four papers, spans elementary through middle school, and traces to something unpublished. It may well be about right. It is not a number to put in a slide deck without saying where it came from.

    Do you need an incentive or reward package?

    No. The review says the structure worked “with and without” behavioural incentives, and reports no clear difference between the two versions in the 2010 study. Incentives may add something, but the evidence does not make them a requirement.

    The one study that compared them directly, Maheady et al. (2006) with 23 sixth graders in science, reported quiz averages of 72 percent under existing practice, 81 percent under the plain structure, and 89 percent with a package of team points and certificates added. That looks like a real additional bump. The review’s own verdict is more cautious: future work should “tease out the relative contributions and costs and benefits of a behavioral incentive package.” If you are weighing it up, the costs side of that sentence is the part worth sitting with — points and certificates are a system you then have to maintain, and they change what the activity is about.

    How is it different from cold calling or think pair share?

    All three distribute participation; they differ in when the student finds out they are on the hook. Cold calling puts a student on the spot before they have rehearsed. Think pair share gives rehearsal without accountability. Numbered heads together gives rehearsal first, then accountability.

    RoutineWhen the student knows they might answerWhat they have before they speakMain weakness
    Cold callingThe moment their name is saidWhatever they had in their head alreadyCan feel like a trap if the class culture is not right
    Think pair shareUsually never — sharing is often volunteeredA rehearsed answer and a partner’s viewThe same students volunteer; the rest coast
    Numbered heads togetherAfter the team has agreed, never beforeTheir own written answer plus the team’sTakes longer per question and needs built teams
    JigsawThey always present; the role is assigned up frontExpertise on one piece onlyDepends on every expert group doing its job

    Put plainly: numbered heads together is what you use when you want the honest answer to “does this class understand it?” rather than “does anyone in this class understand it?” That is a different question from the one a show of hands answers, and it is the same question behind every decent check for understanding.

    What does cooperative-learning research say about why it should work?

    The standard justification is Robert Slavin’s: group work raises achievement when it combines a group goal with individual accountability, and mostly does not when it lacks either.

    His 1991 synthesis of more than 70 studies is blunt about it — “two elements must be present if cooperative learning is to be effective: group goals and individual accountability.”

    The numbers behind that sentence are stark. Slavin reports that 37 of 44 studies (84 percent) using both elements found significant positive achievement effects, against only 4 of 23 studies (17 percent) lacking them. His wider review of 99 studies of at least four weeks puts the median effect size at +.32 for methods with group rewards based on the sum of individual learning, against +.07 for methods using a single group product or no group reward at all.

    Here is where honesty costs the argument something. Slavin’s “individual accountability” is specific: a team reward calculated from each member’s own quiz score. He writes that the effect holds “if and only if the group rewards are based on the individual learning of all group members.” Numbered heads together does not do that. One student’s answer, drawn at random, stands in for the team. Slavin does mention structures in which “group members might be chosen at random to represent the group” — but in his version that student’s performance determines the reward, which is a harder and rarer arrangement than a teacher drawing a number to pick who speaks.

    So the Slavin research is supporting evidence by analogy, not direct support. He does also write that “carefully structuring the interactions among students in cooperative groups can also be effective, even in the absence of group rewards,” which is the closest thing in his work to a defence of structures like this one. Anyone who cites Slavin as proof that numbered heads together works has not read him carefully.

    Where does numbered heads together go wrong in grades 6–12?

    Four places, and three of them are the teacher quietly dropping a step. The structure is doing a specific job, and each shortcut removes the part that does it.

    Four panels listing common failure points: letting students pick their own teams, skipping the individual write, calling the number too early, and using questions with one obvious answer.
    Four ways numbered heads together stops working in a grades 6–12 classroom.
    • Students pick their own teams. The procedure calls for small heterogeneous teams you build. Friend groups reproduce exactly the participation pattern the structure exists to break, and they put the quiet student with the other quiet students.
    • The individual write gets skipped. Without it the routine is group discussion with a random call bolted on, and the student who was not thinking has nothing of their own to fall back on. Notably, the version tested in Kagan’s own effect-size article is described there as an older one without an individual write.
    • The number is drawn before the team has finished. Step four includes making sure every member can give the answer. Cut that short and the called student is being tested rather than supported, which is the thing this structure was designed not to do.
    • The questions have one obvious right answer. Slavin warns that on single-product tasks “the participation of less able students may be seen as interference rather than help.” If the answer is a date or a definition, the fastest student says it and the team nods. Questions with reasoning in them are the ones worth the three minutes.
    • It becomes the whole lesson. The studies ran it in sessions of 30 to 42 minutes as the questioning portion of a lesson, not as a replacement for teaching. There is nothing in this research that says a period of whiteboard rounds is a good period.

    What about the student who freezes when the number comes up?

    Plan for them before you start, not in the moment. The structure is built so nobody is caught unprepared, but preparation is not the same thing as being willing to speak in front of 28 people.

    The sensible accommodations do not break anything. A student can read their board rather than speak from memory. A student can be allowed to hold up the team’s board instead of narrating the answer. The teacher can pick a different student from among those holding the drawn number, which the standard procedure already allows — everyone with that number raises a hand and the teacher chooses one of them. And where a student has a plan in place for oral participation, that plan governs; a classroom routine is not a reason to override it. None of that removes the accountability, because the student still had to have an answer ready.

    What does break the structure is quietly never drawing the number of the student you are worried about. Students work that out in about two rounds, and the moment they do, the routine has told them they are not expected to be able to answer. That is a much heavier message than being asked a question.

    Clay’s take: a good structure with an overstated research record

    Two things are true at once here, and the training materials only ever tell you the first one. The structure itself is well designed, and it solves a problem every secondary teacher actually has: a show of hands tells you nothing.

    It solves it without ambushing anybody, too. Writing your own answer, then helping your team, then finding out you are the one who has to say it — that sequence respects students. It gives them a fair shot before it holds them responsible, which is the right order.

    The second thing is that the evidence behind it is five small studies from two research teams, topping out at eighth grade, with a headline effect size traced to an unpublished manuscript. That is not a reason to avoid it. Plenty of sensible classroom practice has less behind it than that. It is a reason to stop calling it research-proven, and it is a reason to watch what happens in your own room rather than assuming the 86 percent transfers.

    What I would want to know before committing a unit to it: do the questions actually need four people, or am I running an elaborate routine to get a one-word answer? That is the question that decides whether this is good teaching or theatre, and no study is going to answer it for you.

    What to do next week

    Pick one lesson with three or four questions in it that genuinely need reasoning, not recall. Build the teams yourself, four to a team, mixed. Run the full four steps on those questions only, and draw the number with something visibly random.

    Keep the individual write and the check that everyone on the team can give the answer. Those are the two steps that get dropped first and they are the two doing the work.

    Then measure the thing the studies measured that is easiest to see: how many students in the room were doing something during the question. If the honest answer is a lot more than usual, it is worth keeping. If students are waiting for the number and then switching off, one of the four steps has gone missing, and it is almost always the write.

    Frequently Asked Questions

    What is numbered heads together?

    It is a cooperative learning structure in which students sit in numbered teams of about four, answer a question individually in writing, agree on a team answer, make sure every member can give it, and then wait for the teacher to draw a number at random to decide who answers. The random call is what makes every student prepare.

    How long does one round take?

    Two to three minutes per question once students know the routine. The published studies ran it in sessions of 30 to 42 minutes as the questioning part of a lesson, covering several questions, rather than as a whole-period activity. Budget more for the first few rounds while students learn the sequence.

    Does numbered heads together work in high school?

    Nobody has published a high school study. The five studies in the 2015 review cover grades 3, 6, 6, 7 and 8, with samples of 3 to 23 students. The sixth-grade science results are the closest thing to a general secondary classroom. Treat high school use as reasonable and untested rather than evidence-based.

    Do you need team points or rewards for it to work?

    No. The review reports the structure worked with and without behavioural incentives and found no clear difference between the two versions in one study. One sixth-grade study did report 81 percent under the plain structure against 89 percent with team points and certificates added, so incentives may help, but they are not a requirement.

    How is it different from think pair share?

    Think pair share gives students rehearsal but usually lets them volunteer, so the same students answer. Numbered heads together gives the same rehearsal and then removes the choice by drawing a number. The accountability arrives after the preparation, not instead of it.

    Is there strong research evidence for numbered heads together?

    There is consistent evidence and very little of it. Five single-case studies, all finding gains, produced primarily by two research teams, none in high school and none randomised. The widely quoted .92 average effect size comes from the publisher’s own magazine and is traced in the literature to a manuscript submitted for publication.

    What do you do about a student who will not speak in front of the class?

    Decide in advance, not mid-round. Let them read from their board, hold up the team’s answer, or be one of several students holding the drawn number from whom the teacher picks. Where a student has a plan covering oral participation, follow it. What does not work is silently never drawing their number, because students notice and read it as low expectations.

    What kind of questions suit it best?

    Questions with reasoning in them, where four students have something to work out together. Recall questions waste the structure, because the fastest student supplies the answer and the team simply agrees. Slavin notes that on single-answer tasks weaker students’ contributions can be treated as interference rather than help.

    Sources

    • Hunter, W. C., Maheady, L., Jasper, A. D., Williamson, R. L., Murley, R. C., & Stratton, E. Numbered Heads Together as a Tier 1 Instructional Strategy in Multitiered Systems of Support. Education and Treatment of Children, 38(3), 345–362 (2015). Full text (PDF). Source of the step-by-step procedure, the 15-item fidelity checklist, every study in the comparison table with its grade level and sample size, the statement that evidence has been collected primarily by two research teams, the call for replications across age and grade levels, and the note that the relative contribution of a behavioural incentive package is still to be determined.
    • Haydon, T., Maheady, L., & Hunter, W. Effects of Numbered Heads Together on the Daily Quiz Scores and On-Task Behavior of Students with Disabilities. Journal of Behavioral Education, 19(3), 222–238 (2010). doi:10.1007/s10864-010-9108-3. ERIC record with abstract. Source of the three-student seventh-grade language arts study and the finding that both versions of the structure raised on-task behaviour and daily quiz scores. The numerical results quoted here are as reported in the 2015 review; the ERIC record itself carries no figures.
    • Slavin, R. E. Synthesis of Research on Cooperative Learning. Educational Leadership, February 1991. Article (PDF). Source of the statement that two elements must be present — group goals and individual accountability — the counts of 37 of 44 and 4 of 23 studies, the finding that effects appear at all grade levels 2–12 while research has more often taken place in grades 3–9 than 10–12, and the warning about single-product tasks.
    • Slavin, R. E. Research on Cooperative Learning and Achievement: What We Know, What We Need to Know. Center for Research on the Education of Students Placed at Risk, Johns Hopkins University. Working-paper version (PDF). Source of the median effect sizes of +.32 and +.07, the review of 99 studies of at least four weeks, the “if and only if” condition on group rewards, and the statement that structuring interactions can be effective even without group rewards. Note that the copy read for this article is a Johns Hopkins working-paper version dated October 1995 and adapted from Slavin (1992); the figures also appear in the published 1996 review, which was not accessible.
    • Kagan, S. Effect Size Reveals the Impact of Kagan Structures and Cooperative Learning. Kagan Online Magazine, Winter 2014. Article. Source of the .92 average effect size for Kagan Structures, the statement that the experiments examined grades 3 through 8, and the description of the tested version as an older one without an individual write. This is the publisher’s own site and it sells the training and materials described, which is why the figure is reported here with its provenance attached.

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • Dual Coding in Grades 6–12: Why Words Plus Pictures Work, and Where It Goes Wrong

    Dual Coding in Grades 6–12: Why Words Plus Pictures Work, and Where It Goes Wrong

    By Clay Shumate

    Dual coding means pairing words with a visual that carries information the words do not. Across 13 experimental comparisons, Richard Mayer found a median effect size of 1.35 for words plus graphics over words alone. Dual coding is not the same thing as teaching to a visual learner, and that distinction does most of the work.

    Key Takeaways

    • Dual coding is a claim about the material, not about the student. It says a well-matched picture and a set of words build two connected representations instead of one. It does not say some students learn through their eyes and others through their ears.
    • The headline number is strong and the setting is narrow. Mayer reports 13 experimental comparisons with a median effect size of d = 1.35 for words plus graphics over words alone — and says in the same chapter that “most of the supporting research involves short-term laboratory studies.”
    • The “visual learner” version of this idea was tested and failed. Pashler, McDaniel, Rohrer and Bjork found “virtually no evidence” for the pattern that matching instruction to a learning style would have to produce, and concluded there is “no adequate evidence base to justify incorporating learning-styles assessments.”
    • Two of Mayer’s own principles tell you when a picture is a waste. Putting the same words on the screen and in your mouth produced a median effect of 0.10 in his redundancy tests, and adding a picture of the person talking produced 0.19. He treats anything under 0.40 as not educationally important.
    • Nobody has run the grades 6–12 study. The main practitioner review of this research names no secondary-grade dual coding study, and its authors say the definition of dual coding itself still needs to be formalised.

    What is dual coding?

    Dual coding is the idea that we process words and images in two separate but connected systems, so material arriving as both leaves more to hold on to than words alone. It is a claim about the material, not about the student.

    James Clark and Allan Paivio set out the educational version in 1991, describing a theory that “explains psychological phenomena by the collective action of nonverbal and verbal mental systems” specialised for imagery and for language.

    Four stacked panels describing the verbal system, the nonverbal imagery system, referential connections between them, and associative connections within one system.
    The two systems dual coding describes, as set out by Clark and Paivio in 1991.

    The detail that matters for teaching sits in the plumbing. Clark and Paivio describe verbal representations as “arbitrary symbols” processed “in a serial or sequential manner,” and images as “analogous or perceptually similar to the events that they denote,” able to encode “in parallel or simultaneously.” The two systems are joined by what they call referential connections. Those connections are the whole mechanism. A picture that does not connect to anything in the words is not dual coding. It is a picture.

    That is a narrower claim than it usually gets reported as, and it sits next to rather than inside cognitive load theory. Cognitive load theory is mostly about not overloading working memory. Dual coding is about what you gain by adding a second, different kind of representation. They overlap, and the places they overlap are where most of the practical advice lives.

    Does dual coding actually work?

    Yes, under test conditions, and by a wide margin. In Mayer’s own words, across 13 experimental comparisons students “perform much better on a transfer test when they learn from words and graphics than from words alone,” with a median effect size of d = 1.35.

    For scale, Mayer treats “any effect size greater than d = 0.40 to be educationally important,” following Hattie. So 1.35 is not a borderline finding. It is one of the largest numbers in instructional design research, and it is the number every training deck quotes.

    Here is the part the training decks leave out. Mayer says in the same chapter that “most of the supporting research involves short-term laboratory studies.” The chapter does not state the age or background of the participants in those 13 comparisons at all. One school-based study he does name, a medical school lecture trial, found d = 0.76 on an immediate transfer test and 1.17 on a delayed one — which is encouraging, and is also medical students. Teachers of thirteen-year-olds are reading across a gap there, and ought to know it.

    Is dual coding the same as learning styles?

    No. Dual coding says a picture and words together beat words alone for everybody. Learning-styles theory says particular students learn better when instruction matches their preferred mode. Those are different claims, and only one survived testing.

    Pashler, McDaniel, Rohrer and Bjork call the learning-styles claim the meshing hypothesis — that “instruction is best provided in a format that matches the preferences of the learner.” To test it, they say, students have to be grouped by learning style, randomly assigned to instructional methods, given the same final test, and then shown to produce a specific style-by-method interaction. Their verdict: “very few studies have even used an experimental methodology capable of testing the validity,” they “found virtually no evidence for the interaction pattern,” and “several found results that flatly contradict the popular meshing hypothesis.”

    Dual codingLearning styles
    What the claim is aboutThe material in front of the classThe individual student
    What it predictsWords plus a relevant visual beat words alone, for everyoneEach student does better when teaching matches their preferred mode
    What you would do on MondayAdd a diagram that carries information the words do notSort students by style and teach them differently
    How it has been testedControlled comparisons of the same lesson with and without graphicsNeeds a style-by-method interaction; almost nobody has run that design
    Where it standsSupported in Mayer’s comparisons, mostly in short-term lab studies“No adequate evidence base,” and several results contradict it

    Yana Weinstein, Christopher Madan and Megan Sumeracki make the same separation in their review of six learning strategies, describing dual coding as resting on “additional, complementary forms of information” rather than on tailoring instruction to individual preferences. If you remember one sentence from this article, make it that one. Adding a diagram to a lesson is supported. Deciding that one student is a visual learner and another is an auditory one is not.

    That distinction matters beyond accuracy, because the labelling version has a cost the diagram version does not. A student who has been told since fourth grade that they are a visual learner has been handed a reason to disengage from reading, and a teenager will use it. Telling a sixteen-year-old they cannot learn from text is not a kindness, and the research never said it. Plenty of families have been told this in good faith by people who believed it. The honest correction is that every student in the room benefits from a good diagram, and no student is excused from the words.

    Which visuals help, and which ones do nothing?

    Mayer’s research programme is useful here precisely because it does not stop at “use pictures.” It tests particular design decisions one at a time and reports how many tests each survived. The spread between the best and worst is enormous.

    Table of eight multimedia design principles with the number of experimental tests supporting each and its median effect size, ranging from 1.35 for the multimedia principle down to 0.10 for redundancy.
    Median effect sizes for eight of Richard Mayer’s multimedia design principles.

    Temporal contiguity — saying the words while the image is on screen rather than before or after — held in 8 of 8 tests at a median of 1.31. Modality, narrating a diagram instead of captioning it in print, held in 18 of 19 at 1.00. Coherence, cutting the decorative image and the entertaining aside, held in 18 of 19 at 0.86. Spatial contiguity, labels on the diagram rather than in a key below it, held in 9 of 9 at 0.82. Signaling, pointing at the part that matters right now, held in 26 of 28 at 0.70.

    Then the bottom of the table. Putting a picture of the speaker on the slide: 4 of 7 tests, median 0.19. Printing the narration on screen as well as saying it: 8 of 12 tests, median 0.10. Read those two again. The two things teachers most often do when they are told to dual code — add a picture, and put the words on the slide so students can follow — are the two with almost no effect. Mayer reports the redundancy result as 8 of 12 tests “yielding a median effect size of 0.10 favoring no onscreen text.” Favouring no text. The slide with your script on it is the thing to delete.

    When does adding a picture make learning worse?

    When the picture competes for attention instead of adding information. Three of Mayer’s principles describe that directly: coherence says cut material that is not needed, redundancy says do not duplicate your narration in print, and the image principle says a face on the slide buys almost nothing.

    Numbered checklist of four questions to ask before adding a visual: does it carry information the words do not, are labels on the image, am I reading the slide aloud, and do students already know this.
    Four checks to run before adding a visual to a grades 6–12 lesson.

    David Didau, writing about how the idea has travelled, puts the classroom version bluntly: “In classroom life, ‘dual coding’ has been simplified into ‘add pictures to your teaching’”, and of the icon sets that result, “None of these abstract symbols adds information.” He is describing a training culture, not a study, and he is right about the training culture. A magnifying glass beside the word analyse is not a second representation of anything.

    Prior knowledge changes the arithmetic too. Mayer reports that several of these effects are strongest for low-knowledge learners, that signaling “may apply most strongly when the learner might otherwise be overwhelmed,” and that pre-training “may not apply to high prior knowledge learners.” He also notes the redundancy effect “can be diminished or even reversed when the lesson is slow-paced or under learner control” — so a handout a student reads at their own speed is not the same artefact as a slide you are narrating over. Same words, different job.

    How do you dual code a grades 6–12 lesson?

    Start with the material, not the strategy. The highest-value moves are small, free and easy to check, and none of them requires drawing ability.

    1. Pick the content that has parts or a sequence. A process, a structure, a comparison, a causal chain. Three branches of government, the stages of a bill, the chambers of the heart, the steps in a titration. Dual coding has nothing to offer a list of dates.
    2. Draw the relationship, not the object. A picture of a courthouse adds nothing to the word judiciary. A diagram showing which branch can stop which other branch adds the thing the sentence cannot show at a glance.
    3. Put the labels on the image. Spatial contiguity held in 9 of 9 tests at a median of 0.82, and this is the cheapest fix on the list. Project the diagram and write the labels onto it, or hand out a copy with the key already on the picture.
    4. Say something the slide does not say. If the text is on screen, narrate the reasoning instead of reading it. If you want students listening rather than reading, strip the slide to the image and a heading — and if students are supposed to be capturing it, say so, because note-taking while reading a slide aloud is the redundancy effect with extra steps.
    5. Point at what matters, when it matters. Signaling survived 26 of 28 tests. On a dense diagram, the difference between useful and overwhelming is often just a finger and a sentence.
    6. Take one thing out. Coherence held in 18 of 19 tests. Before you add a visual, find the decorative one already on the page and delete it.
    7. Ask who is in front of you. Students who already know the material do not need the scaffold, and for them the extra representation can be noise. This is the same judgement call that shows up in deciding when to remove a scaffold.

    Should students make the visuals themselves?

    Probably, for content with parts — but the evidence for student-generated visuals is thinner than the evidence for well-designed teacher-provided ones.

    Weinstein and colleagues illustrate dual coding with students drawing two neurons and explaining how one communicates with the other across the synaptic gap, and say explicitly that students “could draw a similar visual representation themselves.”

    That is a reasonable classroom recommendation from a careful review, and it is not the same as a measured effect in a secondary classroom. The practical test is the one in step two above: did the student draw a relationship, or did they draw a nice picture of the noun? A labelled diagram of how a feedback loop runs is dual coding. A coloured-in cell with the parts copied off the board is colouring in, and it eats a period. If you want students building their own representations of a concept, a structure like the Frayer model at least forces them to produce something with parts.

    What the evidence does not say

    It does not say every lesson needs a diagram, it does not say visuals reduce cognitive load, and it does not support any fixed percentage of improvement. It also does not reach as far into secondary classrooms as the confidence of the training decks implies.

    • Clark and Paivio caveat their own theory. They write that effects of imagery on comprehension “are not universal,” that the qualifications “often involve interactions with individual differences,” and that “much additional research needs to be done.” That is 1991, and the people who built the theory said it.
    • The practitioner review calls for the definition to be tightened. Weinstein, Madan and Sumeracki conclude that dual coding needs to be better formalised and that more research is needed on how it is actually implemented in classrooms.
    • No secondary-grade dual coding study is named in that review. Its other strategies are supported by work with middle- and high-school students — the interleaving evidence includes a seventh-grade study on graph and slope problems. The dual coding section does not have that.
    • Swapping words for pictures is not dual coding at all. Replacing text with an icon removes a representation rather than adding one, and that version of the practice has not been tested.

    Clay’s take: the cheap half is the good half

    The moves with the best numbers behind them are the ones that cost nothing and can be checked in ten seconds. Move the labels onto the diagram. Delete the decorative image. Stop reading the slide out loud.

    None of that needs a training day, a template, or a drawing tablet, and the effect sizes behind those three decisions are better than most of what gets handed down as best practice.

    The part I would be slowest to spend a period on is students drawing. Not because it cannot work — the review recommends it — but because the gap between a labelled diagram of a relationship and a nicely shaded picture of a noun is wide, it is invisible from the front of the room, and the second one takes longer. If you are going to spend the time, spend it on content with parts, and make the labels the graded thing.

    And be careful what you call this. The moment “dual coding” becomes the reason a worksheet has clip art on it, the term has stopped meaning anything and the practice has stopped helping. It is not a box to tick on a lesson plan. It is a question about whether the picture is carrying its own weight.

    What to do next week

    Pick one lesson you already teach that has a diagram in it, and do three things to it. Move every label from the key onto the image itself. Delete the one picture that is there only to look nice.

    Then write down what you are going to say while the diagram is up, and make sure none of it is already printed on the screen.

    That is the entire intervention, it takes about fifteen minutes, and it is backed by three principles with 53 supporting experimental tests between them. Everything else in this article is a reason to be careful. Those three things are just better.

    Frequently Asked Questions

    What is dual coding in simple terms?

    It is pairing words with a visual that carries information the words do not. The theory says verbal and visual information are handled by two separate but connected systems, so well-matched words and pictures together leave more to recall than words alone. The picture has to connect to the words to count. A decorative image is not dual coding.

    Is dual coding the same as learning styles?

    No. Dual coding says words plus a relevant picture beat words alone for all learners. Learning-styles theory says individual students learn better when teaching is matched to their preferred mode. Pashler and colleagues found virtually no evidence for the interaction pattern that claim requires, and concluded there is no adequate evidence base for learning-styles assessments.

    How big is the effect of adding pictures to words?

    Richard Mayer reports 13 experimental comparisons in which learners did better on transfer tests from words plus graphics than from words alone, with a median effect size of 1.35. He treats anything above 0.40 as educationally important. He also notes that most of the supporting research consists of short-term laboratory studies.

    Does dual coding work in middle and high school?

    The principles are plausible there, but the direct evidence is thin. The main practitioner review of learning strategies names no secondary-grade dual coding study, and Mayer’s chapter does not report the ages of participants in the multimedia comparisons. Treat the design principles as well supported in general and the grade-specific claim as untested.

    When do visuals make learning worse?

    When they duplicate or compete rather than add. Mayer’s redundancy tests favoured removing on-screen text that repeats the narration, with a median effect of 0.10. His coherence principle, supported in 18 of 19 tests at a median of 0.86, says cut material that is interesting but unnecessary. Students who already know the content gain least.

    Should I put the words on the slide so students can follow along?

    Not if you are narrating the same words. That is the redundancy effect, and 8 of 12 of Mayer’s tests favoured no on-screen text. The exception he names is a slow-paced lesson under the learner’s own control, such as a handout they read themselves. A slide you talk over is a different artefact from a page they read.

    My child was told they are a visual learner. Is that wrong?

    The label is not supported by the research, and it can do harm if a student concludes they cannot learn from reading. What is supported is that a clear, relevant diagram helps everyone, including your child. A teacher saying that is on solid ground. A teacher sorting a class into visual and auditory learners and teaching them differently is not.

    Is asking students to draw a diagram a good use of class time?

    It can be, for content with parts or steps, and the Weinstein review recommends students producing their own visual representations. The test is whether the drawing shows a relationship rather than an object. A labelled diagram of how a process runs is worth the time. Colouring in a picture copied from the board is not.

    Sources

    • Clark, J. M., & Paivio, A. Dual Coding Theory and Education. Educational Psychology Review, Vol. 3, No. 3 (1991). Full text (PDF). Source of the definition of dual coding theory, the description of verbal representations as arbitrary symbols processed serially and images as perceptually analogous and processed in parallel, the referential and associative connections, and the authors’ own cautions that such effects are not universal and that much additional research needs to be done.
    • Mayer, R. E. Research-Based Principles for Designing Multimedia Instruction. In C. E. Overson, C. M. Hakala, L. L. Kordonowy & V. A. Benassi (Eds.), In Their Own Words: What Scholars and Teachers Want You to Know About Why and How to Apply the Science of Learning in Your Academic Setting, pp. 143–157. Division 2, American Psychological Association, 2023. Chapter (PDF). Source of every effect size and test count in this article, the d = 0.40 threshold following Hattie, the statement that most of the supporting research involves short-term laboratory studies, the Issa et al. medical school figures, and the boundary conditions on coherence, signaling, redundancy, pre-training and modality.
    • Pashler, H., McDaniel, M., Rohrer, D., & Bjork, R. Learning Styles: Concepts and Evidence. Psychological Science in the Public Interest, Vol. 9, Issue 3, pp. 105–119 (2008). Repository record with abstract. Source of the meshing hypothesis definition, the experimental design the authors say is required, and the conclusions that very few studies have used a methodology capable of testing the claim, that virtually no evidence was found for the interaction pattern, and that there is no adequate evidence base to justify incorporating learning-styles assessments.
    • Weinstein, Y., Madan, C. R., & Sumeracki, M. A. Teaching the science of learning. Cognitive Research: Principles and Implications, 3:2 (2018). doi:10.1186/s41235-017-0087-y. Full text. Source of dual coding as one of six strategies described as combining words with visuals, the neuron-drawing classroom example and the statement that students could draw a similar visual representation themselves, the separation of dual coding from learning styles, the seventh-grade interleaving study, and the conclusion that the definition of dual coding needs to be better formalised.
    • Didau, D. The Dual Coding Delusion. The Learning Spy, 2025. Article. Source of the observations that dual coding has been simplified in schools into adding pictures to teaching and that abstract decorative symbols add no information. This is a practitioner commentary rather than a study, and the systematic review it refers to sits behind a paywall and was not read for this article.

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

Teacher Emergency Toolkit — practical resources, real classroom support. Shop on TPT.Teacher Emergency Toolkit — practical resources, real classroom support. Shop on TPT.