The Elevate Blog banner: Real Classrooms. Practical Ideas. Higher Expectations. Three students climb a rocky ridge at sunrise, each pulling the next one up, toward a teacher reaching down to help.

Author: Clay Shumate

  • Peer Tutoring in Grades 6–12: What the Evidence Actually Shows

    Peer Tutoring in Grades 6–12: What the Evidence Actually Shows

    By Clay Shumate

    Peer tutoring is a structured arrangement in which one student teaches another specific content, with assigned roles, a script and a set schedule. Across 145 studies it averages six months of additional progress, and secondary scores better than primary. The best-designed secondary trial found nothing for the students being tutored — while their tutors gained.

    Key Takeaways

    • The headline average is good and the best secondary trial is not. The Education Endowment Foundation rates peer tutoring at +6 months from 145 studies on high-security evidence, with secondary at +7 months. Its own randomised secondary trial of 2,736 pupils found −1 month and no effect on reading.
    • The tutor is the one who reliably learns. In a randomised secondary study, the older tutors gained 0.24 of a standard deviation while the younger students they tutored lost 0.07, and the difference between the two groups was statistically significant.
    • At secondary, pair within the grade. The only review restricted to grades 7–12 found same-age pairs at d = 0.61 against cross-age at d = 0.21, a significant gap — and its authors flag that this contradicts earlier reviews.
    • Most of the famous numbers are elementary. The effect size usually quoted as “the” peer tutoring figure comes from a meta-analysis of elementary students, and the largest modern cross-age synthesis is kindergarten and elementary, where mathematics came in at −0.02 and writing at 0.01.
    • It is cheap, which changes the calculation. Two randomised trials costed the approach at £10.50 and £8.25 per pupil. Adult one-to-one tutoring in the same country ran £167 to £180 per pupil for fifteen hours.

    What is peer tutoring?

    Peer tutoring is an arrangement where students work in pairs or small groups to give each other explicit teaching support. The defining feature is the asymmetry of role, not the closeness of the desks: one student is teaching, one is learning, and both know which they are doing right now.
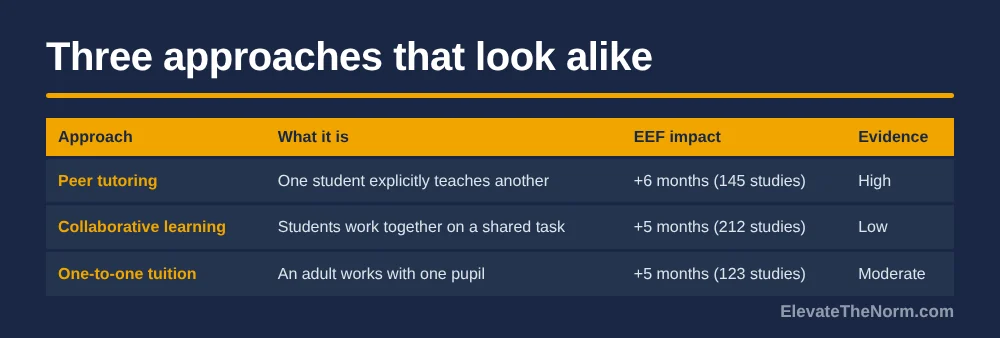
    Table comparing peer tutoring, collaborative learning and adult one-to-one tuition by what each is, the Education Endowment Foundation's months-progress figure, and the strength of the evidence behind each.

    One clarification before anything else, because the phrase is used two ways. This article is about instructional peer tutoring inside a class or a timetabled block. It is not about the volunteer tutoring club that students join for service hours. Those programmes can be worthwhile, but nothing in the research below was measured on them.

    The terminology is settled and worth using precisely. Same-age tutoring pairs students from the same grade. Cross-age tutoring puts an older student with a younger one. Reciprocal tutoring has the pair swap roles; fixed-role tutoring does not. Classwide peer tutoring runs the whole room in pairs at once, usually with points and short turns in each role.

    It is also not the same thing as cooperative learning and its five elements, which is peers working together on a shared task rather than one instructing the other. A secondary review of peer-mediated instruction draws that line cleanly: tutoring builds a tutoring relationship, cooperative work builds a cooperative one. The EEF reviews them separately too — collaborative learning sits at +5 months on low-security evidence from 212 studies, against peer tutoring’s +6 months on high-security evidence from 145.

    ApproachWhat it isEEF impactEvidence strengthCost
    Peer tutoringOne student explicitly teaches another, with roles and structure+6 months (145 studies)HighVery low
    Collaborative learningStudents work together on a shared task+5 months (212 studies)LowNot rated here
    One-to-one tuitionA teacher, assistant or other adult works with one pupil+5 months (123 studies)ModerateModerate

    Does peer tutoring actually work in grades 6–12?

    The averages say yes and the best secondary trial says no, and both are published by the same organisation. That tension is the honest answer. Any article that gives you the +6 months without the null trial, or the null trial without the +6 months, is not reporting the evidence.

    Start with the average. The EEF Toolkit puts peer tutoring at six months of additional progress over a year, rates the evidence high from 145 studies, rates the cost very low, and reports secondary at +7 months against primary at +5. Lower attainers gain more than higher attainers. That is a strong entry by Toolkit standards.

    Then read the trial. EEF’s Paired Reading evaluation put older secondary tutors with younger ones for reading across 10 secondary schools, randomising 2,736 pupils in 120 classes at a cost of £10.50 per pupil. The younger group came out at −0.02, confidence interval −0.15 to 0.11. The older group came out at −0.06, confidence interval −0.14 to 0.02. Both round to minus one month. There was no evidence of impact on overall reading ability, sentence completion or passage comprehension, and none for pupils eligible for free school meals.

    A companion trial in elementary mathematics landed in the same place: 82 schools, 6,472 pupils, effects of 0.01 and 0.02, at £8.25 per pupil for the year. EEF published both, called them robust given the design and the number of schools, and said the findings should not be dismissed. Its own candidate explanations — all explicitly unconfirmed — were that cross-age tutoring may work less well in these schools or age groups, that implementation may have been too thin, and that business as usual may already contain enough peer work to shrink what a new scheme adds.

    The genuinely secondary evidence supports something narrower than “it works.” A meta-analysis of 26 single-case studies with 938 participants found no significant difference between elementary and secondary results, with the secondary subset at a Tau-U of 0.74 across 10 studies and 368 participants. A review of 42 secondary mathematics studies found a mean of d = 0.38, with 5 negative.
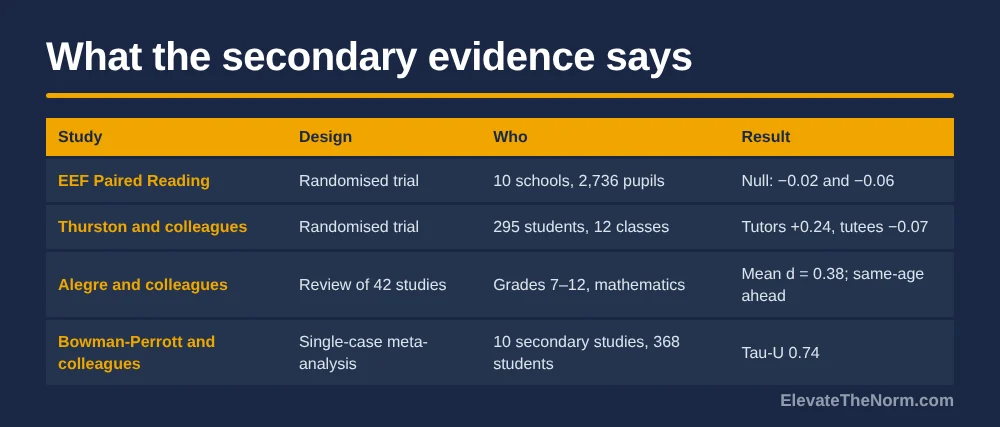
    Table of four studies that tested peer tutoring with secondary students, listing each design, the students involved and the measured result, including one null randomised trial and one in which only the tutors gained.

    One caution about effect sizes in this literature, from inside it. In that secondary mathematics review, studies using a pretest, a posttest and a control group averaged d = 0.31, while studies with weaker designs averaged d = 0.60. The authors recommend control-group designs precisely because the alternative overestimates. When you see a big number for a classroom practice, ask what it was compared against.

    Who gains more, the tutor or the student being tutored?

    The tutor, on the clearest secondary evidence available. In a randomised study across three secondary schools, the older students acting as tutors gained 0.24 of a standard deviation in reading comprehension while the younger students they tutored came in at −0.07, and the gap between the two groups was significant.

    That study ran 295 students in 12 classes, paired reading, twelve weeks at thirty minutes a week, measured on an age-standardised reading comprehension test. Its authors are straight about the limits: classes rather than individuals were randomised, the sample is small, and the paper reports its own overall effect inconsistently. The tutor-versus-tutee contrast is the part that holds.

    It does not stand alone. An updated meta-analysis of tutors’ own achievement across 16 articles reports a weighted mean of 0.43, and lists tutors drawn from secondary school among the conditions associated with stronger results. The classic 1982 synthesis of 65 tutoring evaluations reported that tutors gained better understanding of the subject and more positive attitudes toward it, similar to the students they tutored.

    While we are here, kill the other claim. That same 1982 synthesis found tutoring had little or no effect on the self-esteem of either tutors or tutees, and the elementary mathematics trial found no quantitative evidence of impact on attitudes toward school, reading or maths. Teachers in that trial perceived confidence gains, and the evaluators flagged that perception as needing study rather than reporting it as a result. If you are selling peer tutoring to a department on confidence, you are selling something nobody has measured.

    There is a reason the tutor result is the one I find persuasive, and it is not just the statistics. Explaining something to a person who is entitled to be confused is a harder intellectual task than answering a question on a worksheet. It is also the version of responsibility this site keeps arguing for: giving a teenager a real role with real consequences teaches the teenager. The evidence says that part works even in the trials where the tutee gains did not show up.

    Should you pair students same-age or across grades?

    At secondary, pair within the grade. The one review restricted to grades 7–12 found same-age pairs at d = 0.61 and cross-age pairs at d = 0.21, a significant difference, and its authors suggest same-age pairs benefit from trust that already exists between classmates.

    Those authors also do the right thing and flag that their finding conflicts with earlier reviews, which generally treated the two configurations as equally effective. One older British paper in the set argues the opposite outright and favours cross-age. So this is a lean, not a law.

    What makes the lean worth following is where the cross-age evidence comes from. The strongest cross-age results are elementary: a district-wide randomised trial across 129 elementary schools reported effects of about 0.2, and a modern meta-analysis of cross-age tutoring in kindergarten and elementary settings found composite reading at g = 0.18 from 16 cohorts and 8,251 students — with mathematics at −0.02, writing at 0.01 and fluency at 0.11, none of them significant. The one large cross-age trial run in secondary schools is the null above.

    If you do go across grades, the Toolkit guidance is specific: keep the age gap under about three years, do not match pairs by attainment, and pitch the work so it stretches the younger student while staying comfortable for the older one.

    Should students swap roles or keep fixed tutor and tutee roles?

    Either is defensible, and nobody has shown a difference at secondary. The grades 7–12 review put fixed roles at d = 0.33 and reciprocal roles at d = 0.50, but at p = 0.30 that is not a finding. A second mathematics meta-analysis also reported roles as a non-significant moderator.

    So choose on other grounds. Reciprocal roles mean everybody tutors, which removes the labelling problem that fixed roles create and keeps the tutor benefit available to the whole class rather than to the stronger half. Fixed roles are simpler to run and easier to script when the content is genuinely beyond the weaker student.

    The one thing not to do is let the configuration encode a verdict on who is good at school. A room where the same students are permanently the tutors is a room where you have published a ranking. If fixed roles are right for the content, rotate the content so the roles move — the way the jigsaw method makes every student the expert on something.

    How long should a peer tutoring block run, and how often?

    Shorter than you would guess, and the sources disagree. EEF recommends sessions four to five times a week in blocks of four to ten weeks. The secondary mathematics review found the opposite: programmes of eight weeks or less beat longer ones, and so did sessions of thirty minutes or less.

    That review also found weekly frequency trending downward — one session a week averaged d = 0.48, five averaged d = 0.13 — though not significantly, so it is a hint rather than a result. The single-case meta-analysis found dosage did not moderate outcomes at all, above and below its median of 480 total minutes.

    What the actual trials delivered is the most useful guide. The null secondary trial ran thirty-minute periods with twenty minutes of reading over sixteen weeks. The elementary maths null ran twenty minutes a week in sixteen-week blocks. The positive secondary tutor result came from thirty minutes a week for twelve weeks. On that evidence a short, tight block is the sensible bet, and a programme that runs all year because nobody stopped it is the least supported option on the board.

    One more piece of Toolkit guidance that matters more than the timetable: peer tutoring works best for reviewing and consolidating learning, not for introducing new material. Use it the week after you taught something, not the week you teach it.

    How much training do student tutors need?

    Enough that they have a script and know what to do when their partner is stuck. EEF calls training for staff and tutors essential. One meta-analysis lists shorter, less frequent training among the conditions tied to stronger results, so the sources conflict on dose while agreeing it cannot be zero.

    The training detail from the null trial is the part worth staring at. Teachers got about a day and a half. Pupil training varied badly across the schools: some used only the first lesson, some trained only the older pupils, and one school did no advance pupil training at all. That is not a trial of a well-implemented programme, which is exactly why EEF listed implementation among its explanations rather than declaring the approach dead.

    What the training should contain is better specified. EEF points at questioning frames, modelling, handling misconceptions, giving feedback and evaluating progress. An older review adds the blunt reason it matters: untrained tutors may resort to threats and put-downs, and younger tutors need more structure and closer supervision than older ones. If a department or a district is going to adopt this, that training is the budget line — not the materials, and certainly not the pairing spreadsheet.

    From a student’s side, the training is also where the dignity is. Being handed a partner and told to help them is an instruction to improvise in public; being handed three questions to ask and a sentence to say when neither of you knows is a job you can actually do. Script the hard moment, not the easy one.

    What if the tutor teaches it wrong?

    Nobody has measured it, and that gap should be stated rather than papered over. None of the studies here tracked tutor accuracy or error spread as an outcome. What the literature offers instead is a structural answer: keep peer tutoring on review material, which is the Toolkit’s own advice.

    Two related findings are the closest thing to a warning. In the elementary maths trial, teachers reported that pupils with additional language needs, special educational needs or lower prior attainment struggled with the programme and that the teachers felt ill-equipped to support them — the evaluators concluded it may need tailoring before being tested again. And the secondary mathematics review found a larger effect for students without learning disabilities, 0.62 against 0.23, which cuts against the Toolkit’s own expectation that lower attainers and pupils with special educational needs gain most. Two credible sources, opposite directions. Say so and plan for both.

    Practically, the mitigations are cheap. Tutor on content you have already taught and marked. Give the tutor the answer key for the set they are working through. Circulate and listen to explanations rather than checking that pairs are on task, because an on-task pair confidently teaching a wrong method looks exactly like success from the front of the room.

    How do you set up a peer tutoring block?

    Six steps, and the unusual one is the last. Keep it to review content, keep the block short, pair inside the grade, script the hard moment, and tell students plainly what the arrangement is and why they are in the seat they are in.

    1. Pick review content, not new content. A unit you have already taught and assessed. The tutor needs to have met the material before, not be meeting it a page ahead of their partner.
    2. Set the block before you start it. Four to eight weeks, one or two sessions a week, thirty minutes or less. Write the end date on the board so it ends on purpose rather than drifting.
    3. Pair inside the grade, and not by rank order. Same-age pairing has the better secondary evidence. Avoid the arrangement where the pairing publishes a league table of who is good at school.
    4. Give both students the same one-page script. Three questions the tutor asks, the sentence to say when both are stuck, and the rule that the tutor explains rather than does it for them.
    5. Train the hard moment and hand over the key. Spend one session on what to do when the partner is wrong or silent, and give the tutor the answers for the set they are working through.
    6. Tell students the evidence, including the awkward part. Say that the research is clearest on the tutor learning from teaching, that being tutored is not a verdict on anyone, and that the roles will move. Teenagers can handle the real reason; they cannot handle being managed.
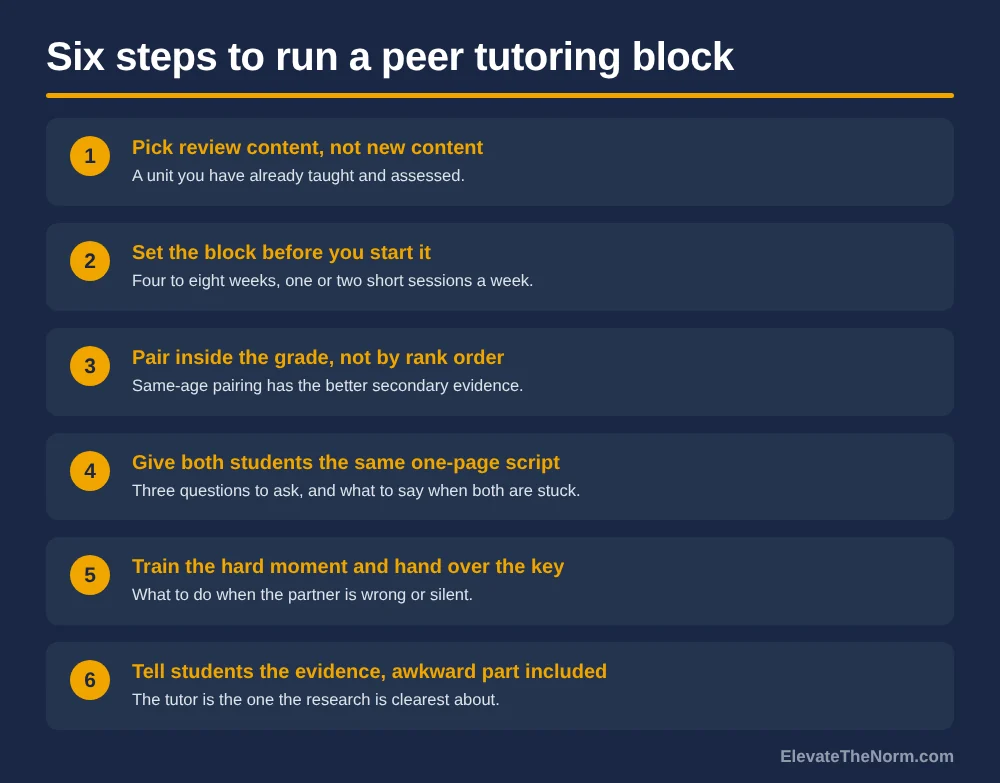
    Numbered list of six steps for running a peer tutoring block: pick review content, set the block length in advance, pair inside the grade, give both students one script, train the hard moment and hand over the answer key, and tell students the evidence.

    One addition to step four that comes from thinking about the seat rather than the plan: let the student being tutored pick the set they want help with. Being assigned a tutor is easy to read as a public verdict on your ability, and the fastest way to stop that is to put the tutee in charge of the agenda. They choose which three problems or which paragraph; the tutor runs the script on those. Same structure, completely different meaning from the chair.

    Families will ask, and they are entitled to a straight answer: no, their child is not being taught by another student instead of by you. Peer tutoring sits on content you have already taught, for a fixed block, with the teacher in the room and the answer key in the tutor’s hand. The honest version of the pitch is that the child will also spend half the block doing the explaining, because that is the part the research is clearest about.

    Two notes on the cost of running it. The time goes into training and materials rather than into the sessions themselves, which is why EEF rates the cost very low; in the null trial, 20 of 52 classes found the time inside existing lessons rather than adding a slot. And if you want a record of what each student contributed without turning the block into a grading project, having students rate their own contribution to group work is less work than scoring pairs yourself.

    Is peer tutoring worth it in grades 6–12? Clay’s take

    Yes, with the claim narrowed to what the evidence supports. Run it so the tutor role rotates through everybody, because the tutor gain is the finding that keeps replicating at secondary. Treat gains for the student being tutored as a hope rather than a promise.

    That is a smaller claim than the Toolkit’s +6 months, and I think it is the defensible one. The strongest secondary results in this whole literature are the ones about the person doing the explaining, and the biggest, best-designed secondary trial failed to find anything for the person being explained to. If the practice were expensive, that pattern would be a reason to drop it. At eight to ten pounds a pupil, against sixteen times that for adult tutoring, it is a reason to be honest about which outcome you are buying.

    What also stands out is how often the structure is doing the work rather than the pairing. Every version of this that produced something had a script, a role, a short block and somebody checking. The versions that produced nothing had pupil training that varied from one lesson to none at all. “Help each other” is not an intervention, and a 90-second pair routine run properly will beat a term of unstructured helping.

    What should you do next?

    Pick one unit you have already taught and run a four-week block on it. Same-grade pairs, one thirty-minute session a week, a one-page script, and the tutor role swapping halfway through so every student does the explaining at least once.

    Measure the thing the evidence says you will get. Give a short quiz on the review content before and after, and look at the scores of the students who did the explaining. That is the outcome with the best secondary support behind it, and it is the one most likely to be worth your four weeks.

    Frequently Asked Questions

    What is peer tutoring?

    Peer tutoring is a structured arrangement in which students work in pairs or small groups to give each other explicit teaching support, with one student teaching and one learning at any moment. It differs from group work in that the roles are asymmetric and assigned. Same-age pairing uses students in the same grade, cross-age pairing puts an older student with a younger one.

    Is peer tutoring effective for high school students?

    The averages are good and the best secondary trial is not. The Education Endowment Foundation rates peer tutoring at six months of additional progress from 145 studies, with secondary ahead of primary. Its own randomised trial of 2,736 secondary pupils found no effect on reading. A meta-analysis of single-case studies found secondary results no weaker than elementary ones.

    Do tutors learn more than the students they tutor?

    At secondary, that is what the clearest evidence shows. In a randomised study of 295 students, the older tutors gained 0.24 of a standard deviation in reading comprehension while the younger students they tutored came in at minus 0.07, and the difference was significant. A meta-analysis of tutors’ own achievement across 16 articles reports a weighted mean of 0.43.

    Should you pair students same-age or across grades?

    At secondary, pair within the grade. The only review restricted to grades 7 to 12 found same-age pairs at d = 0.61 against cross-age at d = 0.21, a significant gap, though the authors note this conflicts with earlier reviews. The strongest cross-age evidence comes from elementary schools, and the one large secondary cross-age trial found nothing.

    How long should a peer tutoring programme run?

    Keep it short. The Toolkit suggests blocks of four to ten weeks with frequent sessions, while the secondary mathematics review found programmes of eight weeks or less outperformed longer ones and sessions of thirty minutes or less outperformed longer ones. The one positive secondary tutor result came from thirty minutes a week across twelve weeks.

    How much training do student tutors need?

    More than none, and the sources disagree about how much more. EEF calls training for staff and tutors essential and points at questioning frames, modelling, handling misconceptions and giving feedback. In the null secondary trial, pupil training ranged from a single lesson to none at all in one school, which is part of why the evaluators flagged implementation.

    Is peer tutoring the same as tutoring?

    No. Adult one-to-one tuition is a separate approach with its own evidence base, rated by EEF at five months from 123 studies with moderate cost. A review of 96 randomised evaluations of adult tutoring found pooled effects of 0.37 standard deviations, with teacher-delivered tutoring at 0.50 and volunteer-delivered at 0.21. Peer tutoring costs a fraction as much.

    Does peer tutoring improve confidence or self-esteem?

    There is no good evidence that it does. The classic synthesis of 65 tutoring evaluations found little or no effect on the self-esteem of tutors or tutees, and a randomised elementary mathematics trial found no quantitative evidence of impact on attitudes toward school, reading or maths. Teachers in that trial perceived confidence gains, which the evaluators flagged as needing further study.

    Sources

    • Education Endowment Foundation. Peer tutoring. Teaching and Learning Toolkit. Toolkit entry. Source of the +6 months average, the high evidence rating, the 145 studies, the very low cost rating, the secondary +7 against primary +5 split, the pairing and age-gap guidance, the training guidance, the review-not-new-material point, and EEF’s own warning that evaluations by organisations connected to an approach tend to report larger impacts.
    • NatCen Social Research for the Education Endowment Foundation. Paired Reading: Evaluation report and executive summary. Evaluation report (PDF). Source of the secondary null: 10 schools, 2,736 pupils randomised in 120 classes, −0.02 for the younger group (CI −0.15 to 0.11) and −0.06 for the older (CI −0.14 to 0.02), minus one month each, no effect for pupils eligible for free school meals, £10.50 per pupil, about a day and a half of teacher training, and the variation in pupil training between schools.
    • Education Endowment Foundation. Durham Shared Maths Project: Evaluation report and executive summary. Evaluation report (PDF). Source of the elementary mathematics null: 82 schools, 6,472 pupils, effects of 0.01 and 0.02, £8.25 per pupil per year, no quantitative evidence of impact on attitudes, and the finding that teachers felt ill-equipped to support pupils with additional language needs, special educational needs or lower prior attainment.
    • Coleman, R., & Henderson, P. Peer tutoring — interpreting new evidence. Education Endowment Foundation. Blog post. Source of EEF’s assessment that both trials appear robust and should not be dismissed, and of its three unconfirmed explanations for the null results.
    • Thurston, A., Cockerill, M., & Chiang, T.-H. Assessing the Differential Effects of Peer Tutoring for Tutors and Tutees. Education Sciences, 11(3). Full article. Source of the tutor gain of 0.24 against the tutee −0.07, the significant difference between the two groups, and the design: 295 students in 12 classes across three secondary schools, twelve weeks at thirty minutes a week. The paper reports its overall effect inconsistently, so only the group figures are quoted here.
    • Alegre, F., Moliner, L., Maroto, A., & Lorenzo-Valentin, G. Peer tutoring and mathematics in secondary education: literature review, effect sizes, moderators, and implications for practice. Heliyon, 5. Full article (PDF). Source of the grades 7–12 figures: 42 studies, mean d = 0.38 with 5 negative, same-age 0.61 against cross-age 0.21, fixed 0.33 against reciprocal 0.50 at p = 0.30, the eight-week and thirty-minute findings, the weekly-frequency trend, the 0.62 against 0.23 learning-disability split, and the control-group design caveat of 0.31 against 0.60.
    • Bowman-Perrott, L., Davis, H., Vannest, K., Williams, L., Greenwood, C., & Parker, R. Academic Benefits of Peer Tutoring: A Meta-Analytic Review of Single-Case Research. School Psychology Review, 42(1). Full article (PDF). Source of the overall Tau-U of 0.75 across 26 single-case studies and 938 participants in grades 1–12, the secondary subset of 10 studies and 368 participants at 0.74 against elementary 0.69 with no significant difference, and the finding that dosage did not moderate outcomes. Tau-U is a non-overlap index and is not comparable to a Cohen’s d.
    • Leung, K. C. C. An updated meta-analysis on the effect of peer tutoring on tutors’ achievement. School Psychology International, 40(2). Abstract record. Source of the weighted mean of 0.43 across 16 articles for tutors’ achievement, and of the listed conditions including tutors from secondary school, structured tutoring, same-age non-reciprocal pairing, and shorter and less frequent tutor training. No confidence interval is reported, and only the abstract was readable.
    • Shenderovich, Y., Thurston, A., & Miller, S. Cross-age tutoring in kindergarten and elementary school settings: a systematic review and meta-analysis. Accepted manuscript (PDF). Source of the cross-age figures — composite reading g = 0.18 from 16 cohorts and 8,251 students, mathematics −0.02, writing 0.01, fluency 0.11 — and of the Cohen, Kulik and Kulik effect sizes quoted through this paper rather than from the 1982 original.
    • Cohen, P. A., Kulik, J. A., & Kulik, C.-L. C. Educational Outcomes of Tutoring: A Meta-Analysis of Findings. American Educational Research Journal, 19(2). Bibliographic record with abstract. Source of the findings that tutors gained better subject understanding and more positive attitudes similar to tutees, and that tutoring had little or no effect on the self-esteem of either group, across 65 evaluations. The record carries no effect sizes; those are quoted above through Shenderovich and colleagues.
    • Tymms, P., Merrell, C., Thurston, A., Andor, J., Topping, K., & Miller, D. Improving attainment across a whole district: school reform through peer tutoring in a randomized controlled trial. School Effectiveness and School Improvement, 22(3). Repository record with abstract. Source of the district-wide elementary trial across 129 schools reporting cross-age effect sizes of about 0.2.
    • Mahoney, M. W. M. Peer-mediated instruction and intervention to support the academic achievement of secondary students with autism spectrum disorder: a systematic review of the literature. The Journal of Special Education Apprenticeship, 12(1). Full article (PDF). Source of the distinction between a tutoring relationship and a cooperative one, the description of classwide peer tutoring with short turns in each role, and the observation that most of the available studies sit in elementary schools rather than secondary ones.
    • Gaustad, J. Peer and Cross-Age Tutoring. ERIC Digest No. 79, ERIC Clearinghouse on Educational Management. ED354608. Digest (PDF). Source of the same-age and cross-age terminology, the warning that untrained tutors may resort to threats and put-downs, and the point that younger tutors need more structure and closer supervision.
    • Education Endowment Foundation. Collaborative learning approaches and One to one tuition. Collaborative learning entry. Source of the +5 months from 212 studies on low-security evidence for collaborative learning, the +5 months from 123 studies on moderate evidence for adult one-to-one tuition, and the £167 to £180 per pupil figure for fifteen-hour tutoring blocks under the National Tutoring Programme.
    • Nickow, A. J., Oreopoulos, P., & Quan, V. The Transformative Potential of Tutoring for PreK–12 Learning Outcomes: Lessons from Randomized Evaluations. Abdul Latif Jameel Poverty Action Lab. Evidence review (PDF). Source of the adult-tutoring contrast: pooled 0.37 standard deviations across 96 randomized evaluations, with teacher-delivered tutoring at 0.50, paraprofessional at 0.40 and volunteer at 0.21. This is adult tutoring, used here only as the comparison case.
    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • Responsibility Scenarios for Middle School Students: 15 Real Situations to Discuss

    Responsibility Scenarios for Middle School Students: 15 Real Situations to Discuss

    By Clay Shumate

    Responsibility scenarios for middle school students are short, realistic situations, like a missed deadline, a group member not pulling weight, or a borrowed item broken, that students talk through before deciding what to do. Good scenarios have no obvious right answer, name who is affected, and end with a plan to fix the problem.

    Key Takeaways

    • Scenarios teach the decision, not the rule. Students practice weighing options and consequences before the real moment arrives.
    • Use four questions every time. What happened, who is affected, what are the options, and what will you do and how will you fix it.
    • Pick situations with a real cost on both sides. If the answer is obvious, students give the answer they think you want and learn nothing.
    • Discussion quality matters more than the scenario. A study of secondary moral-discussion programs found change in some classrooms but not others, tied to how many discussions there were and how well the teacher drew out reasoning.
    • End with repair, not punishment. Every scenario below asks students how they would fix the damage, because that is what responsibility looks like after a mistake.

    What are responsibility scenarios?

    Responsibility scenarios are short, true-to-life situations that ask a student what they would do, why, and how they would make things right. They give middle schoolers a low-stakes rehearsal for choices they will face in class, online and at home.

    The idea lines up with what CASEL, the organization behind the most widely used social-emotional learning framework, calls responsible decision-making: the ability to make caring and constructive choices about your own behavior and how you treat other people across different situations. A scenario is simply a safe place to practice that before it counts.

    What a scenario is not: a worksheet with one correct answer, or a story with a moral pasted on the end. Twelve- and thirteen-year-olds can smell a lecture coming. The scenarios that work are the ones where a reasonable kid could argue either side.

    Why use scenarios instead of just teaching the rules?

    Rules tell students what not to do. Scenarios make them think through what to do when the rule does not settle it, which is most of real life. They also let students practice owning a mistake before they are standing in one.

    There is old but useful research behind the discussion part. Colby, Kohlberg and colleagues ran moral discussion programs in secondary schools, taught by regular social studies teachers, and measured students’ moral reasoning before and after. Some classrooms showed substantial change and some did not. The difference was tied to the number of discussions, the range of reasoning already in the room, and the teacher’s skill at drawing out students’ reasoning.

    Two honest caveats. That study measured how students reason about right and wrong, not how they behave, and it is from the 1970s. So treat it as support for one thing only: the conversation is the active ingredient. A scenario read aloud and answered in one word does little. A scenario argued over for ten minutes does more.

    How do you run a responsibility scenario in class?

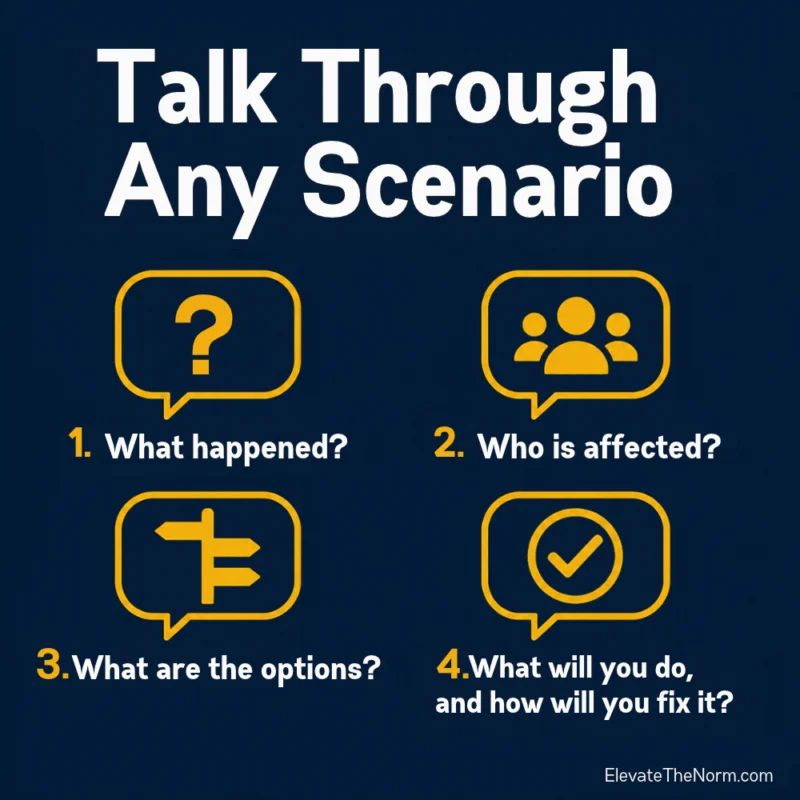
    Read the scenario, give students a minute to decide alone, then talk it through with four questions: what happened, who is affected, what are the options, and what will you do and how will you fix it. Ten minutes is enough.

    Four discussion questions for any responsibility scenario: what happened, who is affected, what are the options, and what will you do and how will you fix it
    The same four questions work for every scenario in this article.
    1. Read it once, out loud. Project it too, so students who read slowly are not left behind.
    2. One quiet minute. Everyone writes or decides their answer before anyone speaks, so the first loud voice does not decide for the room.
    3. Pairs, then the room. Two minutes with a partner, then hear a few answers that disagree.
    4. Push on the reasoning. Ask “why?” and “who else does that affect?” more than you ask “is that right?”
    5. Close with the repair. End on what the person would actually do to fix it, not on who was wrong.

    Keep it about the characters, never about a real student in the room. If a scenario hits too close to something that just happened in your class, swap it out. The point is rehearsal, not a public trial. If you want longer, hands-on options to pair with these, see our activities for teaching responsibility.

    Responsibility scenarios for schoolwork and deadlines

    These scenarios cover the responsibility middle schoolers deal with most: deadlines, effort, honesty about work and asking for help. Each one has a real cost on both sides, which is what makes students argue about it.

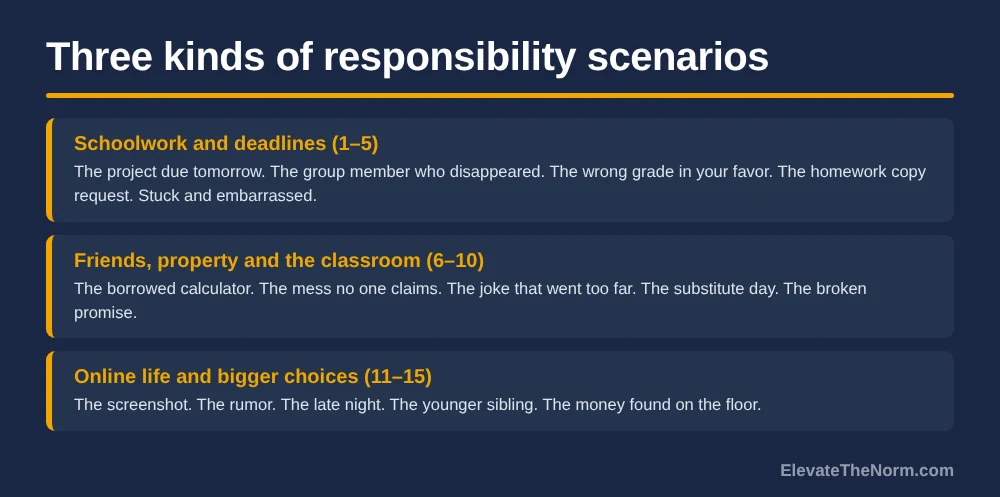
    The fifteen responsibility scenarios grouped into three categories: schoolwork and deadlines, friends and property and the classroom, and online life and bigger choices
    The fifteen scenarios in this article, grouped three ways.

    1. The project due tomorrow

    Jordan has known about a project for two weeks and has barely started. It is due tomorrow. Jordan’s friend offers to send a finished version from last year.

    • Discuss: What are Jordan’s real options tonight, and what does each one cost?
    • What a responsible answer includes: Turning in honest, unfinished work or asking the teacher for help before the deadline, and a plan to start the next project earlier.

    2. The group member who disappeared

    In a four-person group project, Sam has done almost nothing. The presentation is Friday. The rest of the group is angry and wants to leave Sam’s name off.

    • Discuss: What is fair to the group, and what is fair to Sam?
    • What a responsible answer includes: Talking to Sam directly first, then to the teacher if nothing changes, and splitting the remaining work so the group is not punished for one person.

    3. The wrong grade in your favor

    Maya notices the teacher entered a 92 on a quiz where she actually earned a 72. Nobody else would ever know.

    • Discuss: Does it matter if nobody finds out?
    • What a responsible answer includes: Telling the teacher, because a grade is supposed to say what you can do, and keeping it would mean the next lesson starts from the wrong place.

    4. The homework copy request

    A classmate asks to copy Diego’s homework every morning before first period. Diego does not want to be the bad guy.

    • Discuss: Is letting someone copy helping them?
    • What a responsible answer includes: Offering to explain the work instead, and saying no to copying without making it a big public scene.

    5. Stuck and embarrassed

    Aaliyah has been lost in math for a week. Everyone else seems to get it, and she does not want to look slow.

    • Discuss: What happens if she keeps waiting?
    • What a responsible answer includes: Asking for help early, privately if that feels safer, because the gap only grows.

    Responsibility scenarios for friends, property and the classroom

    These scenarios are about other people’s stuff, shared spaces and the small choices that decide whether a classroom works. They are useful early in the year, when a class is still deciding what kind of room it will be.

    6. The borrowed calculator

    Chris borrowed a classmate’s calculator and dropped it. The screen cracked. The owner has not noticed yet.

    • Discuss: Who should speak first, and when?
    • What a responsible answer includes: Telling the owner right away and offering a real way to make it right, even if that is only part of the cost.

    7. The mess no one claims

    At the end of a lab, the table is a mess. Nobody at the table made all of it, and everyone is waiting for someone else to clean up.

    • Discuss: Whose job is a shared mess?
    • What a responsible answer includes: Pitching in without arguing about who did what, because the next class has to use that table.

    8. The joke that went too far

    A group laughs when Tyler makes a joke about a classmate’s clothes. Tyler meant it as harmless. The classmate goes quiet for the rest of the period.

    • Discuss: Does it matter what Tyler meant?
    • What a responsible answer includes: Recognizing the impact, apologizing directly without excuses, and not repeating it.

    9. The substitute day

    There is a substitute. Half the class decides to switch seats and give fake names. Lena thinks it is funny but also knows the sub will have a hard day.

    • Discuss: What does Lena owe the substitute, if anything?
    • What a responsible answer includes: Not joining in, and being honest if asked, because respecting an adult you will never see again says more than respecting one who grades you.

    10. The broken promise

    Marcus promised to bring supplies for his group’s presentation. He forgot. The group has nothing to show.

    • Discuss: What does Marcus do in the next five minutes?
    • What a responsible answer includes: Owning it immediately, offering what he can do right now, and fixing the problem for next time rather than making excuses.

    Responsibility scenarios for online life and bigger choices

    These scenarios reach past the classroom into phones, group chats and decisions with real consequences. They tend to produce the best discussions with seventh and eighth graders, because this is where students already make most of their own choices.

    11. The screenshot

    Someone in a group chat posts an embarrassing photo of a classmate and asks everyone to share it. Priya is in the chat.

    • Discuss: Is staying quiet a choice?
    • What a responsible answer includes: Not sharing it, saying something or leaving the chat, and telling a trusted adult if the photo keeps spreading.

    12. The rumor

    Eli hears a rumor about a friend that is probably false. Everyone is already talking about it.

    • Discuss: What can one person actually do about a rumor?
    • What a responsible answer includes: Not repeating it, checking with the friend directly, and saying “I don’t think that’s true” when it comes up.

    13. The late night

    Sofia has a test tomorrow and has been gaming since dinner. It is 11 p.m. and she has not studied.

    • Discuss: What is the most responsible choice at 11 p.m., and what about next time?
    • What a responsible answer includes: Going to sleep rather than cramming all night, then telling herself the truth about why the test went the way it did and planning differently.

    14. The younger sibling

    Andre is supposed to walk his little brother home every day. Today his friends invite him somewhere after school.

    • Discuss: Who is affected if Andre goes?
    • What a responsible answer includes: Keeping the commitment or arranging a real replacement in advance, not just hoping it works out.

    15. The money found on the floor

    Grace finds a $20 bill on the floor of the cafeteria. No name, no one looking for it.

    • Discuss: Is it hers now?
    • What a responsible answer includes: Turning it in to the office, because someone in the building is probably missing their lunch money.

    What happens when responsibility is missing in a classroom?

    When responsibility is missing, the work and the cleanup fall on a few people, deadlines stop meaning anything, and trust drains out of the room. Students stop believing that their choices matter, and the teacher ends up enforcing every small thing personally.

    Students usually describe it better than adults do. The same four or five kids carry every group project. Shared supplies disappear. Nobody admits to anything, so everybody gets the consequence. That last one is the most corrosive: when one person’s choice becomes the whole class’s punishment, students learn that owning a mistake is pointless.

    Scenarios will not fix that on their own. What fixes it is a room where owning a mistake is followed by a fair, predictable consequence and a real chance to repair it, every time. If you want the bigger picture, our guide to teaching responsibility without treating teenagers like children covers the classroom systems, and natural consequences in the classroom covers the consequence side.

    How do you keep scenario discussions respectful?

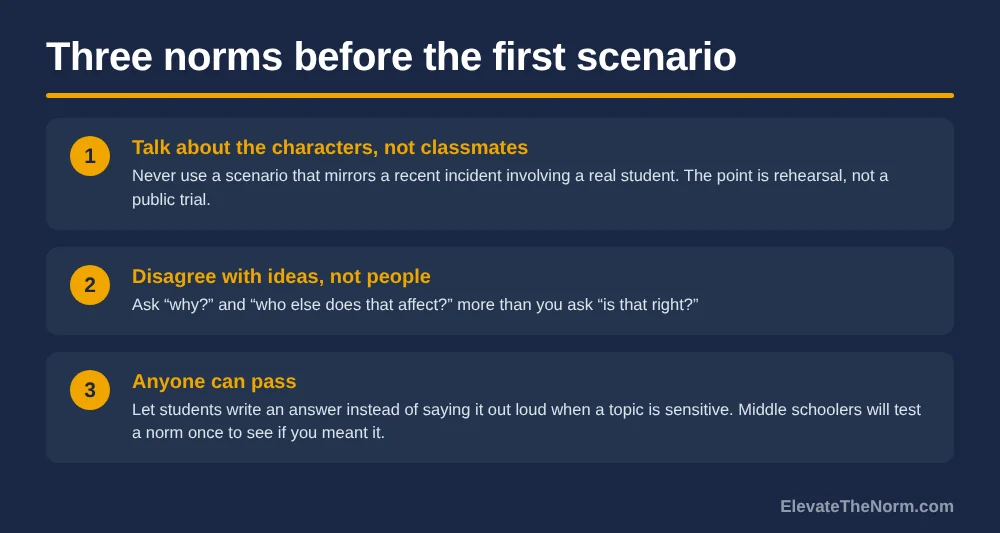
    Set three norms before the first scenario: talk about the characters, not classmates; disagree with ideas, not people; and anyone can pass. Then hold to them every time. Middle schoolers will test a norm once to see if you meant it.

    Three classroom norms to set before the first responsibility scenario: talk about the characters not classmates, disagree with ideas not people, and anyone can pass
    Set these three norms before the first scenario, then hold to them.

    A few more practical moves help. Never use a scenario that mirrors a recent incident involving a real student. Let students write an answer instead of saying it out loud when a topic is sensitive. And if a discussion surfaces something serious, such as a student describing real harm, stop the activity and follow your school’s reporting procedure. A classroom discussion is not the place to handle it.

    For families, these scenarios also work at the dinner table. A parent who asks “what would you do?” about a made-up situation often gets a more honest answer than one who asks “what happened at school today?”

    How do you know if responsibility scenarios are working?

    Look at behavior, not at the discussion. Scenarios are working when students start owning mistakes faster, asking for help before deadlines instead of after, and fixing problems without being told. A great debate with no change in the room means the talk has not transferred yet.

    A simple check: keep a short weekly note of how often students self-report a mistake versus how often you catch it. You do not need a formal tracker, though our student accountability sheet works if you want one. If self-reports climb over a few weeks, the scenarios are doing their job.

    And when a student does own something real, say so. Not a speech, just a plain “thanks for telling me” and a fair consequence delivered without anger. That moment teaches more about responsibility than every scenario on this page combined.

    Frequently Asked Questions

    What are responsibility scenarios for middle school students?

    They are short, realistic situations, such as a missed deadline, a broken borrowed item or an unfair group project, that students discuss before deciding what they would do. The goal is practice in weighing options and consequences and planning how to fix a mistake, before students face the same choice for real.

    How long should a responsibility scenario discussion take?

    About ten minutes works well. Read the scenario, give one quiet minute for students to decide alone, two minutes in pairs, and a few minutes as a whole class ending on how the person would repair the situation. That fits as a bell ringer or a closing routine without losing a lesson.

    What grade level are these scenarios for?

    They are written for grades 6 to 8, but most work in early high school with small changes. The online and bigger-choice scenarios tend to produce the strongest discussions with seventh and eighth graders, because that is where students already make many of their own decisions.

    What happens when students lack responsibility in the classroom?

    Work and cleanup fall on a few students, deadlines lose meaning, shared supplies disappear and trust drops. When nobody admits mistakes, whole classes get punished for one person, which teaches students that owning a mistake is pointless. Fair, predictable consequences with a chance to repair are what reverse that.

    Do scenario discussions actually change behavior?

    Not automatically. A study of secondary moral-discussion programs led by social studies teachers found reasoning changed in some classrooms but not others, depending on how often discussions happened and how well the teacher drew out reasoning. That research measured reasoning, not behavior, so watch for real changes such as students self-reporting mistakes.

    Should students ever discuss a real classroom incident as a scenario?

    No. Keep scenarios about fictional characters and swap out any scenario that mirrors something that just happened with a real student. Turning a recent incident into a class discussion puts that student on trial in front of peers. Handle real incidents privately and through your school's procedures.

    Can parents use these scenarios at home?

    Yes. Asking what would you do about a made-up situation often gets a more honest answer than asking about the school day directly. Families can use the same four questions: what happened, who is affected, what are the options, and what would you do and how would you fix it.

    Sources

    • CASEL. What Is the CASEL Framework? and The CASEL 5. casel.org. Source of the definition of responsible decision-making as the ability to make caring and constructive choices about personal behavior and social interactions across diverse situations.
    • Colby, A., Kohlberg, L., Fenton, E., Speicher-Dubin, B., & Lieberman, M. (1977). Secondary School Moral Discussion Programmes Led by Social Studies Teachers. Journal of Moral Education, 6(2), 90–111. Library record with abstract. Source of the finding that moral judgment change appeared in some but not all classrooms and was associated with the number of discussions, the range of pre-test reasoning in the class, and teachers’ skill at eliciting reasoning. The abstract, not the full article, was read; the study measured moral reasoning, not behavior.
    • All fifteen scenarios on this page are original, fictional situations written for classroom discussion. Any resemblance to real students is unintended.

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • What Grade Is a 3/4? Fraction to Letter Grade Chart for Any Score

    What Grade Is a 3/4? Fraction to Letter Grade Chart for Any Score

    By Clay Shumate

    A 3/4 is 75 percent, which is a C on the common 10-point grading scale. To convert any score, divide the points earned by the points possible, multiply by 100, and match the percent to your school’s scale. So 7/10 is 70 percent (a C), 6/10 is 60 percent (a D), and 14/25 is 56 percent (an F).

    Key Takeaways

    • Every fraction score becomes a grade in two steps. Divide earned by possible to get a percent, then look the percent up on your school’s grading scale.
    • The most-searched scores, on a 10-point scale: 3/4 = 75% (C), 7/10 = 70% (C), 6/10 = 60% (D), 14/25 = 56% (F), 1/4 = 25% (F), 4/8 = 50% (F).
    • The scale decides the letter, not the math. The percent never changes. Where the D/F line sits does: the College Board’s own sample chart puts it around 65, and the older seven-point scales put it at 70.
    • On a standards-based report card, “3/4” may not be a fraction at all. It can mean a 3 on a 1–4 proficiency scale, and converting that to 75% misreads it.
    • Short quizzes swing hard. On a four-question quiz, each question is worth 25 points, so one miss drops a student from an A to a C.

    What grade is a 3/4?

    A 3/4 is 75 percent. On the common 10-point scale, where a C runs from 70 to 79, that is a C. On a plus/minus scale it usually lands as a C, in the middle of the C band.

    The arithmetic is 3 ÷ 4 = 0.75, and 0.75 × 100 = 75. That part never changes. What changes from school to school is which letter 75 earns, so the rest of this page shows you both the math and where the lines usually sit.

    Quick score converter

    Letter uses the common 10-point scale (A 90+, B 80+, C 70+, D 60+, F below 60). Your school’s scale may differ.

    How do you turn any fraction score into a letter grade?

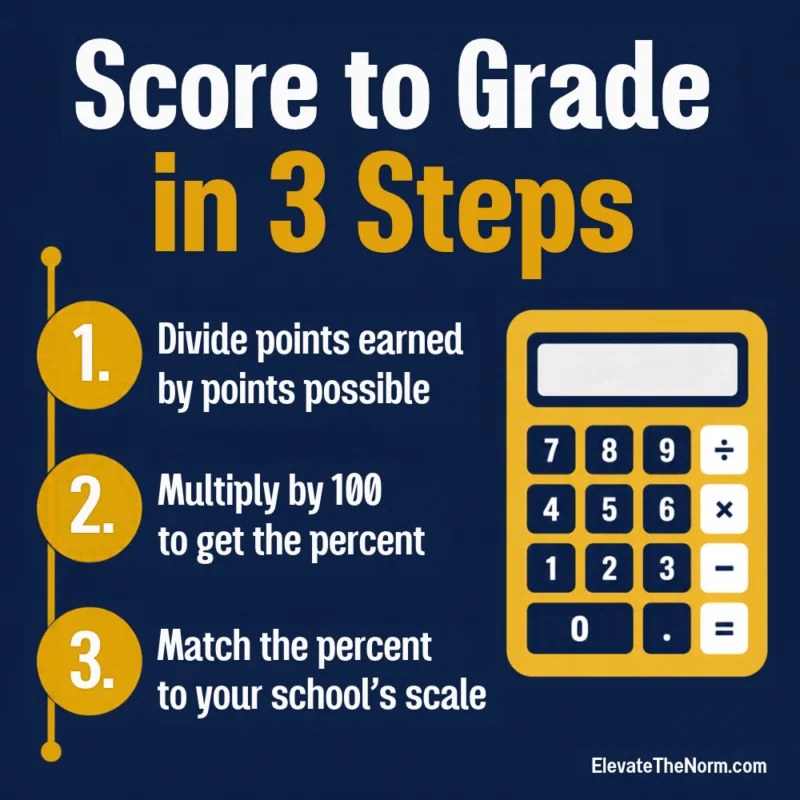
    Divide the points earned by the points possible, multiply by 100 to get a percent, then match that percent to the grading scale your school publishes. A 17 out of 20 is 17 ÷ 20 = 0.85, which is 85 percent, which is a B on a 10-point scale.

    Three steps to turn a score into a grade: divide points earned by points possible, multiply by 100 to get the percent, then match the percent to your school's grading scale
    The whole conversion is division, then a lookup on your school’s scale.
    1. Divide. Points earned ÷ points possible. A phone calculator is fine.
    2. Multiply by 100. That turns 0.56 into 56 percent.
    3. Look it up. Use your school’s published scale. If you do not have it, the 10-point scale below is the most common one in American high schools.
    4. Round only the way your school rounds. Some gradebooks round 89.5 to 90; some do not. That rule belongs in the syllabus, not in a hallway argument.

    One honest warning about step four: a teacher who rounds an 89.5 for one student and not for another has created a fairness problem that no chart can fix. Decide the rounding rule before the first grade posts, then apply it to everyone the same way.

    What are the most common fraction scores as letter grades?

    These are the scores people search for most often, converted on the common 10-point scale: A 90–100, B 80–89, C 70–79, D 60–69, F below 60. The percent column is exact; the letter column depends on that scale.

    ScorePercentLetter (10-point)Why people ask
    3/475%CFour-question quizzes and four-point tasks
    7/1070%CTen-question quizzes; sits right on the C line
    6/1060%DLowest passing score on a 10-point scale
    14/2556%FTwenty-five-point assignments
    1/425%FOne of four correct
    2/4 or 4/850%FHalf right
    14/2070%CTwenty-point quizzes
    7/887.5%BEight-question checks
    Fraction scores converted with the 10-point scale. Check your own school’s scale before you rely on a letter.

    Two of these deserve a second look. A 7/10 is exactly 70, so it is a C by the thinnest possible margin, and on the older seven-point scale it would have been a D. A 6/10 is exactly 60, the lowest passing score on a 10-point scale and an F on most older scales. If a student is sitting on one of those lines, the scale is doing more work than the score.

    Do grading scales disagree about the same percent?

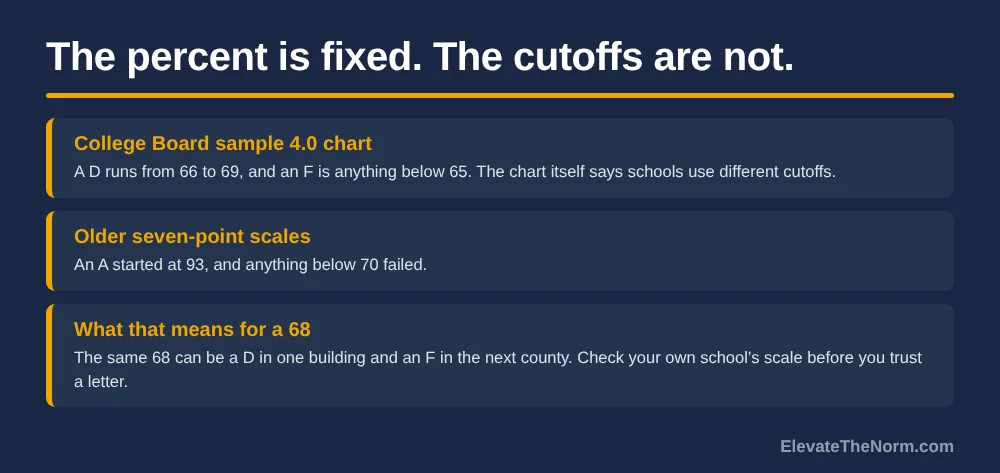
    Yes. The percent is fixed, but the cutoffs are not. The College Board’s own sample 4.0 chart shows a D from 66 to 69 and an F below 65, and says plainly that schools use different cutoffs. Older seven-point scales started an A at 93 and failed anything below 70.

    Comparison of grading scales showing the College Board sample chart with a D from 66 to 69 and an F below 65, older seven-point scales starting an A at 93, and the same 68 landing as a D in one school and an F in another
    The percent is fixed. The letter depends on your school’s cutoffs.

    That means the same 68 can be a D in one building and an F in the next county. The College Board’s GPA conversion page describes its chart as one commonly used system and tells students to check with their own school. That is the right advice, and it is why this page gives you the percent first.

    If you want the full comparison of the two most common scales, including the five averages where they give different letters, the 10 point grading scale chart and its 7 point comparison lays it out with a free printable.

    Is a 3/4 a fraction or a standards-based grade?

    It depends on the report card. On a points-based quiz, 3/4 means three of four points, which is 75 percent. On a standards-based report card, a “3 out of 4” usually means a proficiency level, and turning that into 75 percent misreads it.

    This is where a lot of family confusion starts. A parent sees a 3 on a 1–4 scale, does the division, and thinks their child is earning a C. On most standards-based scales a 3 is the target, the level that says the student has met the standard. The scale is a set of four descriptions, not a fraction of 100.

    If your school uses that kind of scale, the standards-based grading scale 1–4 conversion guide explains what each level means and the different ways schools turn levels into letters for a transcript. Ask the teacher which kind of score you are looking at before you convert anything.

    Why does one missed question hurt so much on a short quiz?

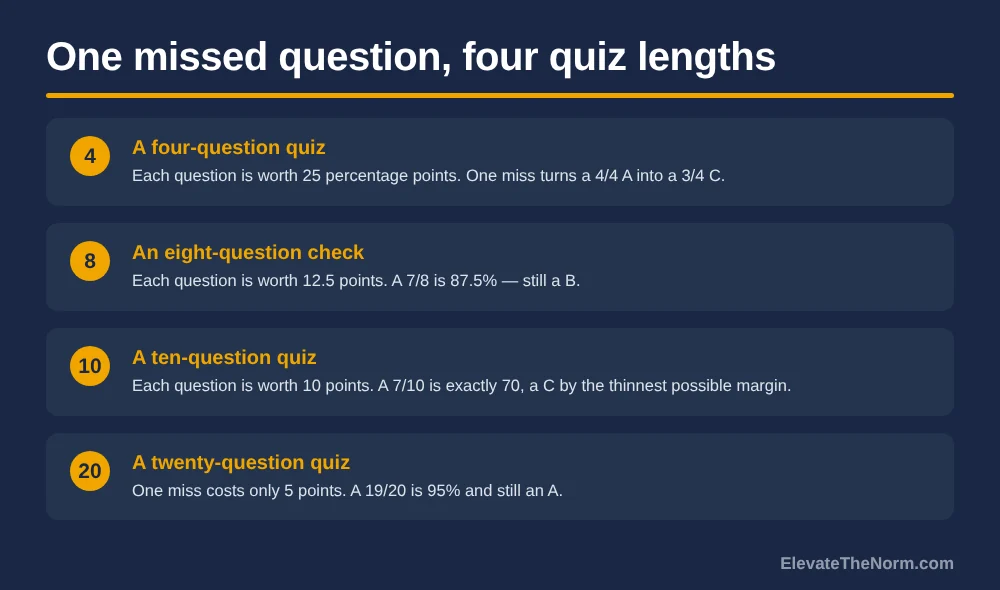
    Because every question on a short quiz carries a large share of the grade. On a four-question quiz each question is worth 25 percentage points, so one miss turns an A into a C. On a twenty-question quiz one miss costs only 5 points.

    Four quiz lengths showing the cost of one missed question: 25 percentage points on a four-question quiz, 12.5 on an eight-question check, 10 on a ten-question quiz and 5 on a twenty-question quiz
    The shorter the quiz, the more one question decides the letter.

    Here is the same idea across the quiz lengths teachers use most. Read across a row and you can see how far a single question moves a student.

    Scores out of 4

    Score out of 4PercentLetter (10-point scale)
    4/4100%A
    3/475%C
    2/450%F
    1/425%F
    0/40%F

    Scores out of 5

    Score out of 5PercentLetter (10-point scale)
    5/5100%A
    4/580%B
    3/560%D
    2/540%F
    1/520%F
    0/50%F

    Scores out of 8

    Score out of 8PercentLetter (10-point scale)
    8/8100%A
    7/887.5%B
    6/875%C
    5/862.5%D
    4/850%F
    3/837.5%F
    2/825%F
    1/812.5%F
    0/80%F

    Scores out of 10

    Score out of 10PercentLetter (10-point scale)
    10/10100%A
    9/1090%A
    8/1080%B
    7/1070%C
    6/1060%D
    5/1050%F
    4/1040%F
    3/1030%F
    2/1020%F
    1/1010%F
    0/100%F

    Scores out of 20

    Score out of 20PercentLetter (10-point scale)
    20/20100%A
    19/2095%A
    18/2090%A
    17/2085%B
    16/2080%B
    15/2075%C
    14/2070%C
    13/2065%D
    12/2060%D
    11/2055%F
    10/2050%F
    9/2045%F
    8/2040%F
    7/2035%F
    6/2030%F
    5/2025%F
    4/2020%F
    3/2015%F
    2/2010%F
    1/205%F
    0/200%F

    Scores out of 25

    Score out of 25PercentLetter (10-point scale)
    25/25100%A
    24/2596%A
    23/2592%A
    22/2588%B
    21/2584%B
    20/2580%B
    19/2576%C
    18/2572%C
    17/2568%D
    16/2564%D
    15/2560%D
    14/2556%F
    13/2552%F
    12/2548%F
    11/2544%F
    10/2540%F
    9/2536%F
    8/2532%F
    7/2528%F
    6/2524%F
    5/2520%F
    4/2516%F
    3/2512%F
    2/258%F
    1/254%F
    0/250%F

    For teachers, the practical lesson is simple: do not let a four-point quiz carry the same weight in the gradebook as a forty-point test. A short check is a good way to see what students know today. It is a poor way to decide a quarter grade, because the scale is too coarse to tell a student who nearly had it from one who had none of it.

    For students, the lesson is the opposite. If a short quiz went badly, ask whether there is a route back, such as test corrections that actually teach the missed skill or a reassessment. Plenty of teachers offer one; fewer students ask.

    What should a student do with a grade they think is wrong?

    Check the math first, then ask. Divide the points earned by the points possible yourself, confirm which scale your class uses, and if the letter still looks wrong, bring the paper and the numbers to the teacher at a calm moment, not during class.

    Most grade errors are entry errors: a score typed into the wrong column, a missing assignment that was turned in, a quiz entered out of 5 instead of 4. Those are easy to fix when you can show the paper. A student who walks up with the paper, the arithmetic and a polite question is treated like the young adult they are. That is a conversation worth having, and most teachers respect it.

    Families can do the same thing by email. Keep it to the facts: which assignment, the score on the paper, the score in the gradebook. If the question is bigger than one entry, such as how zeros affect an average or whether a retake is allowed, the school’s written policy is the place to start.

    Clay’s take: what this chart cannot tell you

    A conversion chart tells you what a score is worth on paper. It cannot tell you whether the score was fair, whether the quiz measured the right thing, or whether one bad day should carry that much weight. Those are judgment calls.

    What I would ask of any teacher is simple: publish the scale and the rounding rule before the first grade, keep short quizzes light in the gradebook, and give students a real way back from a bad score. When those three things are true, a chart like this one is just arithmetic. When they are not, no chart will make the grade feel fair to the kid holding the paper.

    Frequently Asked Questions

    What grade is a 3/4?

    A 3/4 is 75 percent. On the common 10-point grading scale, where a C covers 70 to 79, a 75 is a C. If your school uses a different scale, the percent stays the same at 75 but the letter can change, so check the scale printed in your syllabus or student handbook.

    What grade is a 7/10?

    A 7/10 is 70 percent, which is a C on a 10-point scale, right at the bottom of the C band. On the older seven-point scale, where a C started at 77, a 70 was a D. The percent is fixed at 70; your school's cutoffs decide the letter.

    What grade is a 6/10?

    A 6/10 is 60 percent. On a 10-point scale that is a D, the lowest passing grade. On scales that draw the failing line at 65 or 70, a 60 is an F. Because 60 sits exactly on a cutoff, it is one of the scores most worth checking against your school's own scale.

    What grade is a 14/25?

    A 14/25 is 56 percent, because 14 divided by 25 is 0.56. On the common 10-point scale anything below 60 is an F, so a 56 is an F. A 15/25 would be 60 percent, which is a D on that scale, so the line sits one point away.

    How do you convert a fraction score into a percent?

    Divide the points earned by the points possible, then multiply by 100. For example, 17 out of 20 is 17 divided by 20, which is 0.85, which is 85 percent. Then match the percent to your school's published grading scale to get the letter grade.

    Is a 3 out of 4 on a standards-based report card a C?

    Usually not. On a standards-based 1 to 4 scale, a 3 typically means the student has met the standard, which is the target level. Those levels are descriptions, not fractions of 100, so dividing 3 by 4 to get 75 percent misreads the score. Ask the teacher which kind of score it is before converting.

    Why do different schools give different letters for the same percent?

    Schools set their own cutoffs. The common 10-point scale puts the passing line at 60, the College Board's sample chart puts the D/F line around 65, and older seven-point scales failed anything below 70. The percent from your score never changes; only the letter attached to it does.

    Sources

    • College Board, BigFuture. How to Calculate Your GPA on a 4.0 Scale. bigfuture.collegeboard.org. Source of the sample chart (A 90–100, B 80–89, C 70–79, D 66–69, E/F below 65), its description as one commonly used system, and its statement that schools use different cutoffs.
    • Elevate the Norm. 10 Point Grading Scale: The Chart, the Cutoffs, and What It Actually Changes. elevatethenorm.com. Source of the 10-point bands used in the charts on this page and of the seven-point comparison, which that article cites to North Carolina’s state policy and contemporaneous reporting.
    • All percent conversions on this page were calculated directly (points earned ÷ points possible × 100, rounded to one decimal place). Letters use the 10-point scale stated above.

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • Progress Monitoring in Grades 6–12: How to Tell If an Intervention Is Working

    Progress Monitoring in Grades 6–12: How to Tell If an Intervention Is Working

    By Clay Shumate

    Progress monitoring is the repeated use of a short, standardized measure with a student already receiving an intervention, graphed against a goal, so you can see whether that intervention is working before the semester ends. It answers a different question from a daily check for understanding, and at secondary level the evidence is thinner than the paperwork suggests.

    Key Takeaways

    • Progress monitoring is not formative assessment. A check for understanding tells you whether today landed. A progress-monitoring probe is a standardized measure given on a schedule to a student in an intervention, and its job is to tell you whether the intervention is working at all.
    • The effects are real but modest, and they are not secondary findings. A meta-analysis of data-based decision making in reading interventions found g = 0.24, with a confidence interval of 0.01 to 0.46 across 15 studies of struggling readers in grades K–12. The lower bound almost touches zero.
    • Nobody agrees how much data is enough. Published guidance runs from six data points to twenty, and the national center that writes the standards says plainly that the number needed before a decision “is unclear.”
    • The one measure that fits a secondary caseload is the one with the weakest case. A review of 14 studies and 5,839 students in grades 6–12 concluded that maze reliability is “often below acceptable levels” for exactly the progress decisions teachers want to make.
    • The graph is a trigger, not a diagnosis. Curriculum-based measurement tells you when instruction needs to change and is much less useful for telling you what to change. That second question still needs a diagnostic look at the work.

    What is progress monitoring?

    Progress monitoring is the repeated measurement of a student’s performance over time, using a valid and reliable measure with a standardized administration, to see whether that student is responding to an intervention. The measure stays the same difficulty every time so the scores can be compared.

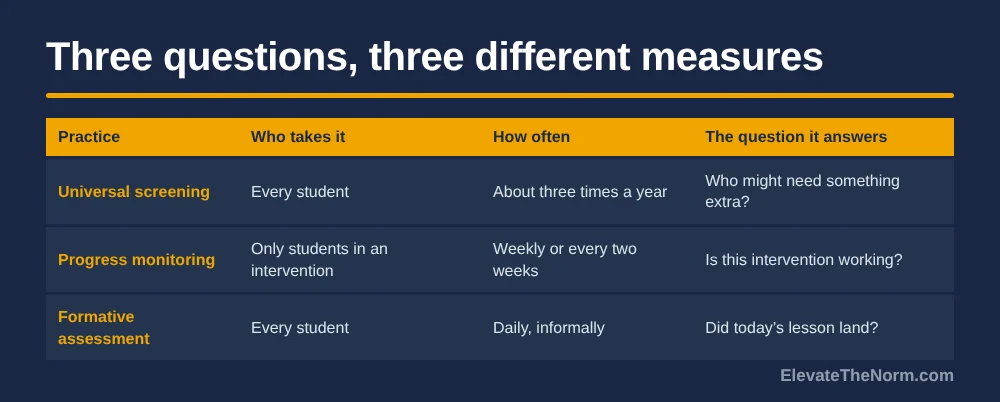
    Table comparing a universal screener, a progress-monitoring probe and a classroom check for understanding by who takes it, how often it is given and which question it answers.

    That last sentence is the whole mechanism. If Tuesday’s task is easier than last Tuesday’s, a rising line means nothing. The measures built for this — the curriculum-based measurement family — are deliberately short, boring and interchangeable. You are not finding out what the student learned this week. You are getting a number that can sit next to twelve other numbers on one axis.

    The practitioner manuals describe it as a system of ongoing data collection on an academic skill, with measures given anywhere from twice a week to once a month. The reading probes are one minute long. A maze passage, where students pick the right word from three choices as they read, runs two and a half minutes in the elementary manual that specifies it.

    One more boundary, and it matters more than any of the technical detail. Progress monitoring is for students who are already receiving an intervention. If every student in your room is taking the probe every week, you are not progress monitoring. You are testing.

    How is progress monitoring different from formative assessment and screening?

    Three practices, three different questions. A universal screener asks which students might need help. A progress-monitoring probe asks whether an intervention is working for one student. A check for understanding asks whether today’s lesson landed. Only the middle one needs a standardized measure on a fixed schedule.

    PracticeWho takes itHow oftenThe question it answers
    Universal screeningEvery studentAbout three times a yearWho might need something extra?
    Progress monitoringOnly students in an interventionWeekly or every two weeksIs this intervention working for this student?
    Formative assessmentEvery studentDaily, informallyDid today’s lesson land?
    Benchmark or unit testEvery studentEach unit, quarter or semesterWhat has been learned so far?

    The people who build these systems draw the line at standardization: ordinary classroom monitoring means informal check-ins, while progress monitoring means a measure with established reliability and validity given the same way every time. Both are useful, they are not substitutes, and a school that runs one while reporting the other is fooling itself.

    If what you actually want is the daily version, that is a different article: the formative and summative labels do less work than people think, and writing checks that fit inside one period will serve you better than a probe will. Progress monitoring earns its cost only when a student is in an intervention and somebody has to decide whether to keep going.

    Does progress monitoring actually improve achievement?

    Modestly, in reading, mostly in elementary samples, and only as part of a decision process. The strongest synthesis for struggling readers reports g = 0.24 with a confidence interval of 0.01 to 0.46, and its authors say experimental studies are needed before data-based decision making can be called an evidence-based practice.

    That synthesis covered 15 studies of struggling readers in grades K–12. In the six studies that compared the same intervention with and without a data-based decision process, the effect was g = 0.27, confidence interval 0.07 to 0.47. Those two numbers are the honest answer to the question, and they are smaller than the enthusiasm around progress monitoring would lead you to expect.

    A second meta-analysis, summarized in the Council for Exceptional Children’s practice alert on data-based individualization, puts data-based individualization against business as usual at g = 0.37 across 14 studies, and at g = 0.38 in six studies that added other data sources. Effects did not differ across reading, math and spelling. Larger effects showed up where teachers built their own measures and where they got more frequent support, such as consultation. That last detail is the best argument going for keeping an instructional coach in the loop: the part of this that moves results is the conversation about what to do next, not the collecting.

    Now the caveats, because they are load-bearing. That same alert rates data-based individualization “Use Caution,” since few experimental studies test the whole process. Of the 15 studies in the reading synthesis, only three used standardized progress-monitoring measures, and most interventions were code-focused work on word reading and fluency — a beginning-reader profile, not a tenth grader’s. Neither meta-analysis says much about what teachers actually changed, so the literature cannot separate the measuring from the teaching.

    And the broadest federal guidance on using student data to drive instruction rates all five of its recommendations at a low level of evidence, with the panel stating that it cannot point to rigorous research proving the practices improve achievement. That guide covers interim and benchmark data rather than curriculum-based measurement, so it is not a verdict on probes — but it is a fair picture of how unsettled this field is.

    How often should you progress monitor?

    The national standard is at least every two weeks for a tier 2 intervention and at least weekly for tier 3. High-school guidance repeats the same two numbers. Older practitioner manuals allow monthly for general-education students and recommend twice weekly for students with disabilities or significant risk.

    This is the one number nobody fights about, which is worth noticing: the frequency guidance is stable across the national center, the state networks and the manuals. Everything downstream of it — how many points you need, what slope counts as good, which measure to use at grade 10 — is contested.

    Pick the frequency from the intensity of the support, not from how worried you are. A student in a thirty-minute daily reading intervention is a weekly case. A student who got moved to the front and given a graphic organizer has not been given an intervention in this sense at all, and monitoring them fortnightly will produce a noisy line and a false sense of rigor.

    How many data points do you need before you change an intervention?

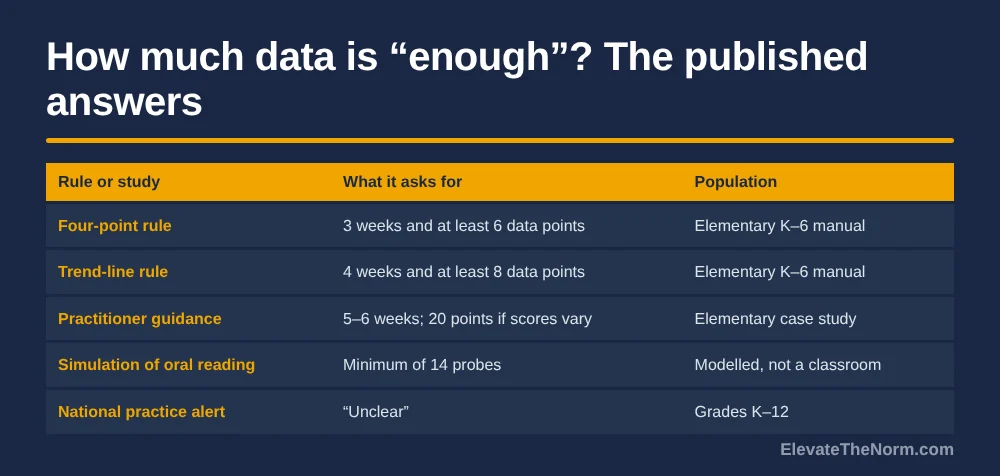
    More than most schools collect, and there is no single answer. Published guidance runs from six data points to twenty, and the national center’s own practice alert says the number needed “is unclear.” A federal research summary notes that most decision-making practices in this area rest on expert opinion.

    Table of five published answers to how much progress-monitoring data is enough, listing what each rule asks for and the population it came from, ending with the national center's statement that the number is unclear.

    Here is the spread, and I think seeing it side by side is more useful than being handed one rule. The four-point rule asks for at least three weeks of instruction and at least six data points before you act on the last four. The trend-line rule asks for at least four weeks and at least eight points. A widely used practitioner article says instructional decisions are possible with five to six weeks of data, then notes that some researchers want at least twenty total points for students whose performance bounces around. A simulation study of oral reading fluency found that a trustworthy growth estimate needed a minimum of fourteen probes, ordinary least-squares regression, and a very clean dataset.

    Those are not small differences. Six points at one a week is a month and a half; twenty points is most of a semester. And the simulation’s fourteen is not a classroom finding — it is a modelled result for one reading measure under synthetic error conditions.

    One other finding is worth carrying around: a dissertation on the accuracy of these interpretations concluded that educators improve their odds of a correct decision by looking at the graph rather than only the rule, and by collecting data for longer than six weeks. The honest practical answer for a secondary teacher is that a slope-based decision wants most of a grading period, and anything faster is a judgment call wearing a number.

    There is a reason this bothers me. A student who sits in a failing intervention for ten weeks because the rule said wait has lost ten weeks. A student pulled out of a working one after three noisy points has lost the thing that was working. The published rules cannot tell you which error you are making. Look at the work, not only the line.

    What can you actually measure in grades 6–12?

    Less than the elementary catalog offers. Reading at secondary usually means a maze passage, writing means a timed sample scored for correct word sequences, and math means an algebra-specific measure. The best review of maze at these grades concluded its reliability is often below acceptable levels for progress-monitoring decisions.

    That review, a University of Maryland dissertation, covered 14 studies and 5,839 students in grades 6 through 12. Maze predicted later reading ability reasonably well — six studies ranged from 0.44 to 0.81, median 0.62 — and correlated with other reading measures at a median of 0.63 across nine studies. Alternate-form reliability looked decent at 0.79 to 0.96, median 0.86, but that figure comes from a single grade 8 sample. The author’s conclusion was that maze shows promise as a screening tool for secondary students and has much less support for progress-monitoring decisions, and that only two studies had examined its technical adequacy with high schoolers at all.

    Math is thinner still. A paper on curriculum-based measurement for secondary mathematics opens by noting that only one study existed on using it in secondary-level math courses. The field has moved since, but nothing I could open replaces that with a strong secondary base.

    What districts actually do at high school is instructive. A state network conversation starter on high-school progress monitoring lists grades, attendance, daily behavior ratings, unit assessments and student contracts alongside the academic probes. For tier 3 reading it points at a maze passage pitched to eighth-grade national norms. For writing it suggests five-minute samples scored by correct minus incorrect word sequences. For math it names an algebra assessment project and a commercial product.

    Notice the ceiling problem in that list. Monitoring a sixteen-year-old on eighth-grade material is defensible when that is genuinely where the skill sits, and it is also how a student ends up with a beautiful upward line and no change in what they can read in your class. If you are monitoring a content-area skill rather than a basic one, you are off the end of the evidence — say so, and treat the number as local rather than validated.

    How do you run progress monitoring with 150 students?

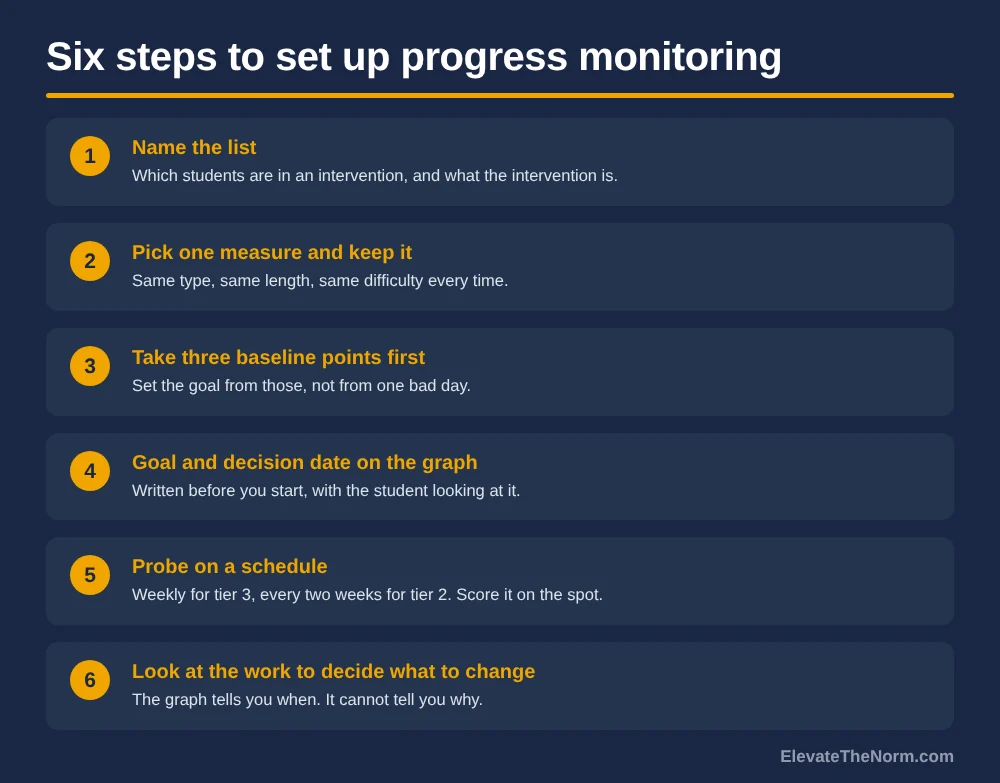
    You do not run it on 150 students. You run it on the handful who are in an intervention, with a group-administrable measure, on a fixed day, with a goal set before the first probe. Six steps, and the first one is the only one that saves you.

    1. Name the list. Write down exactly which students are in an intervention and what the intervention is. If you cannot name the intervention in one sentence, there is nothing to monitor yet.
    2. Pick one measure and keep it. Same type, same length, same difficulty, every time. Switching measures mid-stream destroys the comparison you are collecting.
    3. Take three baseline points before you set the goal. The practitioner guidance is three, and the median of three is a far better starting point than one score on a bad day.
    4. Write the goal and the decision date on the graph, with the student looking at it. Decide in advance what you will do if the line stays flat, and when you will look. A rule written afterward is not a rule.
    5. Probe on a schedule, not when you remember. Weekly for tier 3, every two weeks for tier 2. Same day, same slot, scored on the spot — the last five minutes of a Friday works as well as anything, and a stack of unscored probes is the same as no data.
    6. When the line says change something, look at the work to decide what. The graph tells you the intervention is not working. It cannot tell you why, and that gap is where the actual teaching decision lives.
    Numbered list of six steps to set up progress monitoring: name the students in an intervention, pick one measure, take three baseline points, write the goal and decision date, probe on a schedule, and look at the work before changing anything.

    Step four is the one schools skip, and I would argue hardest for it. A teenager pulled for the same short timed task every Friday, on work deliberately easier than the class, who never sees what it is for, is being measured rather than taught. Show them the graph, the goal line and the date you will look. Say out loud that the task stays the same difficulty on purpose, because the point is comparison and not challenge. A student who knows the decision date can have an opinion about the decision. And the graph is theirs and yours, not a chart on the wall with names on it.

    Families need the same honesty in a different register. If you are monitoring on eighth-grade material, a rising line means that skill is improving — not that the class work is fixed, and saying so early prevents a hard conversation in the spring. Two more fairness points: a probe score is not a grade and should never reach the gradebook, and where a student has a special-education goal written in progress-monitoring language, the limits in this article belong in that team’s conversation rather than hidden from it.

    On the arithmetic, which is mine rather than anybody’s research: a one-minute individual reading probe is fine for four students and impossible for forty, while a maze is a written task a whole group takes at once. That is why the secondary options collapse toward maze and timed writing samples — and it is the uncomfortable part, because that is the measure whose reliability the best secondary review questions.

    Two practical notes. Scoring is quick; building the materials is not — maze construction guidance asks for passages of at least 200 words and at least eighteen of them for a school year, with distractors that cannot make contextual sense and cannot rhyme. And a student who cannot start the work is a different problem from one who cannot do it: if the intervention is about getting going at all, the strategies for students who cannot get started beat a probe.

    What does progress monitoring cost, and is anything free?

    Some of it is genuinely free, with a grade ceiling you need to know about. easyCBM offers a free tier for an individual teacher covering up to 200 students, including progress-monitoring assessments and individual progress graphs. Its reading forms stop at grade 8.

    That ceiling is the whole story for a high-school teacher. On the vendor’s own pricing page, the free tier lists six reading forms for grades 6 and 7 and three for grade 8, with a K–8 math set; the paid tier runs $69.99 for a year and adds benchmark assessments and reporting. There is nothing in the free tier for grades 9 through 12, which is one more reason high schools end up monitoring on eighth-grade material.

    For choosing a tool, the national center publishes a review chart whose committee rates each submitted tool against published criteria without comparing tools to each other. That distinction matters: it is a registry of what vendors submitted and how it scored, not a ranking and not an endorsement. Read it as a consumer guide, which is exactly how its authors describe it.

    If this is a district decision rather than a classroom one, the cost is not the licence. It is the measure, the training, and somebody’s time to give and score probes on a schedule across a building. A mandate that funds the spreadsheet and none of those three produces compliance data — the version of this practice the research does not support.

    Is progress monitoring worth it in grades 6–12? Clay’s take

    It is worth it for students who are genuinely in an intervention, and worth almost nothing as a compliance exercise. The measuring only pays when somebody acts on it, and the secondary tools are weaker than the forms imply. Both facts should change how you use it.

    What convinced me is the structural finding rather than any effect size: curriculum-based measurement is good at telling you when to change instruction and much less useful for telling you what to change. The graph is a smoke alarm, not a diagnosis, and a school that treats a flat line as a finished analysis has bought the alarm and thrown away the extinguisher.

    The honest secondary picture is three things at once. The frequency standards are stable and sensible. The decision rules largely rest on expert opinion, by the admission of the federal summary of that research. And the measure most of us can give to a whole class has reliability its own best review calls often below acceptable levels for this purpose. You can run a defensible system inside those limits, but not one that pretends they are not there.

    So my line is this: monitor few students, monitor them properly, write the decision rule before you start, and keep looking at their work. A short list you take seriously beats a spreadsheet nobody reads, and it beats a graph you were always going to interpret in the direction you already wanted.

    What should you do next?

    Make the list. Write down every student in your classes who is receiving an intervention right now, and what it is. Most teachers find the list is shorter than they expected and that one or two entries are not really interventions. That is the useful part.

    Then pick one student from it and set the graph up properly: one measure, three baseline points, a written goal, a decision date, and a note of what you will change if the line stays flat. Run it for a grading period before judging the method. For the harder question of whether the task itself is pitched right, start with how hard the thinking in a task actually is.

    Frequently Asked Questions

    What is progress monitoring in simple terms?

    It is giving a student the same kind of short, standardized measure over and over on a schedule, plotting the scores against a goal, and using the line to decide whether the intervention they are receiving is working. The measure never gets easier or harder, which is what makes the scores comparable. It is only used with students who are already getting extra support.

    Is progress monitoring the same as formative assessment?

    No. Formative assessment is the informal, unstandardized checking you do daily to find out whether a lesson landed. Progress monitoring uses a measure with established reliability and validity, administered the same way each time, to judge a student’s response to an intervention over weeks. Both are worth doing. Reporting one as the other is how schools end up with paperwork instead of information.

    How often should you progress monitor a student?

    The national standard is at least once every two weeks for a tier 2 intervention and at least once a week for tier 3, and state high-school guidance repeats those figures. Older practitioner manuals allow monthly monitoring for general-education students and recommend twice weekly for students with disabilities or significant risk. Match the frequency to the intensity of the support.

    How many data points do you need before changing an intervention?

    There is no agreed number. The four-point rule asks for six points and three weeks, the trend-line rule for eight points and four weeks, one widely used article suggests twenty points for students whose scores bounce around, and a simulation of oral reading fluency found fourteen probes were the minimum for a trustworthy growth estimate. The national center says the number is unclear.

    Does progress monitoring work in high school?

    The evidence is much thinner than at elementary level. A review of 14 studies and 5,839 students in grades 6 to 12 found maze works reasonably as a screening measure but concluded its reliability is often below acceptable levels for progress-monitoring decisions, and that only two studies had examined high schoolers specifically. Secondary mathematics has even less behind it.

    What can you use for progress monitoring in a content-area class?

    Nothing validated. State high-school guidance suggests maze passages for reading, five-minute writing samples scored for correct word sequences, algebra-specific measures for math, and non-academic indicators such as grades, attendance and daily behavior ratings. Vocabulary-matching probes get named as an option for content areas. Treat anything you build for a history or science skill as a local measure, not a validated one.

    Is there a free progress monitoring tool?

    easyCBM has a free tier for an individual teacher covering up to 200 students, with progress-monitoring assessments, item-level reports and individual progress graphs. Its reading forms stop at grade 8, with six forms for grades 6 and 7 and three for grade 8, so there is nothing in the free tier for grades 9 to 12. The paid tier is $69.99 for a year.

    Does progress monitoring raise achievement on its own?

    No, and nobody has shown that it does. The research is about what teachers do with the data: a synthesis of data-based decision making in reading interventions reports g = 0.24 with a confidence interval of 0.01 to 0.46, and its authors say experimental studies are still needed. The national practice alert rates the full process Use Caution.

    Sources

    • Filderman, M. J., Toste, J. R., Didion, L. A., Peng, P., & Clemens, N. H. Data-Based Decision Making in Reading Interventions: A Synthesis and Meta-Analysis of the Effects for Struggling Readers. The Journal of Special Education, 52(3). Repository record with full abstract. Source of g = 0.24 (CI 0.01 to 0.46) across 15 studies of struggling readers in grades K–12, the six-study subset at g = 0.27 (CI 0.07 to 0.47), and the authors’ statement that experimental studies are needed. The article itself was not reachable; the abstract was read in full on this record.
    • Toste, J., Filderman, M., & Clemens, N. Data-Based Individualization. Current Practice Alert 30, Division for Learning Disabilities and Division for Research, Council for Exceptional Children. Practice alert (PDF). Source of the Jung and colleagues figures (g = 0.37 across 14 studies; g = 0.38 across six), the “Use Caution” rating, the statement that the number of data points needed is unclear, and the note that only three of the 15 reading studies used standardized progress-monitoring measures.
    • Filderman, M. J., & Toste, J. R. Decisions, Decisions, Decisions: Using Data to Make Instructional Decisions for Struggling Readers. TEACHING Exceptional Children, 50(3). Full article (PDF). Source of the three baseline points, the five-to-six-week minimum, the twenty-point suggestion for variable performers, the statement that research varies in these recommendations, and the finding that curriculum-based measurement shows when instruction needs to change but is less useful for deciding what to change. Population: a case study of a fifth grader reading at a second-grade instructional level.
    • Stecker, P. M., & Lembke, E. S. Advanced Applications of CBM in Reading (K–6): Instructional Decision-Making Strategies Manual. ERIC ED519250. Manual (PDF). Source of the one-minute reading probe, the two-and-a-half-minute maze, the four-point and trend-line rules, and the monitoring-frequency ranges. Population: an elementary manual, K–6.
    • Christ, T. J., Zopluoglu, C., Long, J. D., & Monaghen, B. D. Curriculum-Based Measurement of Oral Reading: Quality of Progress Monitoring Outcomes. Exceptional Children, 78(3). Repository record with abstract. Source of the minimum of fourteen probes for a trustworthy growth estimate. This is a simulation of oral reading fluency across modelled durations of 6 to 20 weeks, not a classroom sample, and the abstract rather than the article was read.
    • Van Norman, E. R. An Evaluation of the Accuracy of Time Series Interpretations of CBM-R Progress Monitoring Data. University of Minnesota. Repository record with abstract. Source of the finding that inaccurate interpretations undermine the use of these measures and that educators improve their decisions by analyzing the graph and collecting data for longer than six weeks.
    • Regional Educational Laboratory Southeast, Institute of Education Sciences. Ask A REL Response: policy surrounding data-based progress monitoring. Response page. Source of the characterization of Ardoin and colleagues’ systematic review of decision rules, including the statement that most decision-making practices are based on expert opinion and that more research is required. Ardoin and colleagues’ article was not opened; this federal summary of it was.
    • Mitchell, M. A. Investigating the Use of Maze-CBM for High School Students. University of Maryland. Dissertation record. Source of the 14-study, 5,839-student review of maze in grades 6–12, the predictive and concurrent validity medians of 0.62 and 0.63, the 0.79-to-0.96 alternate-form reliability from a single grade 8 sample, and the conclusion that reliability is often below acceptable levels for progress-monitoring decisions while maze shows promise for screening.
    • Calhoon, M. B. Curriculum-Based Measurement for Mathematics at the High School Level: What We Do Not Know . . . What We Need to Know. Assessment for Effective Intervention, 33(4). Repository record with abstract. Source of the statement that only one study existed on curriculum-based measurement as an assessment tool in secondary-level mathematics courses at the time of writing.
    • Illinois MTSS Network, Northern Illinois University. MTSS Conversation Starter: Defining Progress Monitoring at the High School Level. Conversation starter (PDF). Source of the high-school measure list, the maze pitched to eighth-grade national norms, the five-minute writing sample scored by correct minus incorrect word sequences, and the tier 2 and tier 3 frequency restatement.
    • National Center on Intensive Intervention / American Institutes for Research. Progress Monitoring and What Is Progress Monitoring? Features one-pager (PDF). Source of the definition as repeated measurement using tools with strong reliability and validity, and of the at-least-biweekly tier 2 and at-least-weekly tier 3 standard.
    • PROGRESS Center, American Institutes for Research. Using Academic Progress Monitoring for Individualized Instructional Planning (session transcript). Transcript (PDF). Source of the standardization distinction between progress monitoring and informal classroom check-ins, and of the point that screening covers all students while progress monitoring is reserved for students receiving an intervention.
    • Hamilton, L., Halverson, R., Jackson, S., Mandinach, E., Supovitz, J., & Wayman, J. Using Student Achievement Data to Support Instructional Decision Making. NCEE 2009-4067, Institute of Education Sciences. Practice guide (PDF). Source of the low evidence rating on all five recommendations and the panel’s statement that it cannot point to rigorous research proving the practices improve achievement. Note that this guide addresses interim and benchmark data and does not cover curriculum-based progress monitoring.
    • National Center on Intensive Intervention. Academic Progress Monitoring Tools Chart. Resource page. Source of the statement that the technical review committee rated each submitted tool against its criteria without comparing tools to one another.
    • easyCBM (Riverside Insights). Pricing. Vendor pricing page. Source of the free tier for an individual teacher up to 200 students, the reading form counts for grades 6 to 8, the absence of grades 9 to 12 coverage in the free tier, and the $69.99 annual paid tier.
    • University of Minnesota, College of Education and Human Development. Creating Maze Reading Passages. Guidance page. Source of the maze construction requirements: passages of at least 200 words, at least eighteen passages for a school year, and distractors that cannot make contextual sense and cannot rhyme.

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • Reciprocal Teaching in Grades 6–12: The Four Strategies, and What the Evidence Shows

    Reciprocal Teaching in Grades 6–12: The Four Strategies, and What the Evidence Shows

    By Clay Shumate

    Reciprocal teaching is a structured dialogue in which students take turns leading a small group through predicting, questioning, clarifying and summarizing a text. It works, but the size of the effect depends on who wrote the test — reviews report about .87 on researcher-made comprehension tests and .32 on standardized reading tests.

    Key Takeaways

    • The measure decides the number. Rosenshine and Meister’s review of 19 studies found es = .87 on experimenter-developed tests and es = .32 on standardized tests. A meta-analysis 25 years later found the same split: d = .431 against d = .186.
    • The original evidence is two small studies. Palincsar and Brown (1984) taught reciprocal teaching to six students in the first study and 21 in the second, all of them weak comprehenders in grade 7 or 8.
    • Whole-class delivery is where the effect goes missing. A year-long randomized trial with 369 students in grade 7 found no significant difference between the treatment and control classes.
    • The federal verdict is “mixed effects,” not “proven.” The What Works Clearinghouse reviewed six qualifying studies, found one with a statistically significant positive effect, and put the comprehension domain average at 0.16.
    • What predicted results was the quality of the instruction, not the structure. In the whole-class trial, strategy-instruction quality explained an additional 37 percent of the variation between classes.

    What is reciprocal teaching?

    Reciprocal teaching is a reading routine where a small group works through a text together using four strategies — predicting, questioning, clarifying and summarizing — and students take turns running the discussion instead of the teacher running all of it.

    It was developed by Annemarie Palincsar and Ann Brown in the early 1980s for students who could decode fine and still understood almost nothing they read. The teacher models each strategy, then hands the role over a bit at a time, until a student is leading the segment and the teacher is coaching from inside the group rather than from the front.

    The dialogue is not decoration. Palincsar’s own later article for teachers says only the version that incorporated dialogic instruction was effective, and that the strategies must not be taught “as an end in themselves.” A worksheet with four boxes on it is not reciprocal teaching.

    It belongs to the same family as structured group work with assigned responsibilities, and its closest relative on this site is the jigsaw, where each student owns a different piece of the material. The difference is that in reciprocal teaching every student does every job, in turn, on the same text. Before students can run the clarifying step themselves, they usually need to hear it done out loud first, which is what a teacher think-aloud is for.

    Numbered panels describing the four reciprocal teaching strategies - predicting, questioning, clarifying and summarizing - and what a student does in each role.

    What are the four reciprocal teaching strategies?

    Predicting, questioning, clarifying and summarizing. In the original study they are described as summarizing, questioning, clarifying and predicting, and the order matters less than the fact that all four run on the same passage, out loud, with students taking the lead.

    • Predicting. Say what the next section will cover and why — from the heading, the first sentence, and what the text has already established.
    • Questioning. Write a question a teacher could ask about this passage and ask it. This is the role that does the most work and the one most likely to collapse into asking for a date or a name.
    • Clarifying. Name the word, sentence or reference that did not make sense, and say what you did about it.
    • Summarizing. State what the passage said in a sentence or two, in your own words, with the examples left out.

    Whether all four are strictly necessary is not settled. Palincsar reports that teaching only questioning or only summarizing was less effective than the full version, which is not the same as proving each one is load-bearing. Of the four, summarizing is the one with its own separate literature, and why that literature scores it at both .82 and .44 is worth knowing before you weight it. A dissertation that ran a two-strategy version alongside the full one found all of its groups improved.

    Is reciprocal teaching evidence based?

    Yes, with a caveat that changes what you should expect from it. Four decades of studies find gains on comprehension, and the gains shrink as the studies get larger, more controlled and less researcher-led.

    The anchor review is Rosenshine and Meister (1993), covering 19 experimental studies from ages 7 to adult. On experimenter-developed comprehension tests, es = .87. On standardized reading tests, es = .32. The published 1994 version of that review, which I could not open directly, is quoted in a later critical review as reporting median effect sizes of .88 and .32 for the same split.

    The federal picture is cooler. The What Works Clearinghouse intervention report found six studies that met its standards, one with a statistically significant positive effect, a comprehension domain average of 0.16, and one study that came out negative at −0.48. Its rating is “mixed effects.” And the largest trial ever run on it, the Education Endowment Foundation’s 295-school effectiveness trial published in 2026, found an effect size of 0.06 and one additional month’s progress, which did not reach significance.

    Table comparing reciprocal teaching results across five studies, showing the outcome measure, the reported effect and the population for each, including .87 on experimenter-made tests and .32 on standardized tests.

    Why do the effect sizes disagree so much?

    Because the outcome measure is doing most of the work. Studies that test comprehension with an instrument the researchers built report effects two to three times larger than studies using a standardized reading test, and this pattern has held for thirty years.

    Rosenshine and Meister found .87 against .32 in 1993. Okkinga and colleagues (2018), pooling 52 studies of whole-class reading-strategy instruction, found d = .431 on researcher-developed tests against d = .186 on standardized ones. The 2026 trial above reported gains on sentence-level accuracy and comprehension but not on passage comprehension, which was the programme’s own main target.

    There is a charitable reading and an unkind one, and both are probably true. The charitable one is that a standardized reading test is a blunt instrument that will not detect twelve weeks of anything. The unkind one, which Park’s review makes, is that researcher-made tests are easier and tend to be used with the stronger decoders. For a teacher the practical consequence is the same: expect students to get better at talking about a text well before you see it in a reading score.

    What did the original studies actually find?

    Large gains, on very few students, taught by the researcher. It is worth knowing the size of the base the whole field rests on before quoting it in a meeting.

    In the first study, 37 students in grade 7 were screened as adequate decoders whose comprehension sat about two years below grade level. Six of them received reciprocal teaching, working in pairs with the first author herself. Four of the six reached a stable 80 percent correct, classroom comprehension scores moved from roughly 20 percent to 60 percent, and the average gain on a standardized measure across all six was 15 months.

    The second study handed the routine to volunteer classroom and resource teachers after three training sessions. Twenty-one students in grades 6 to 8 went from about 40 percent to about 80 percent correct, most reaching criterion within 15 days. The eight-week follow-up showed a five-point decline. Twenty-seven students in total, all white, rural central Illinois, and no effect size reported anywhere in the paper.

    Does reciprocal teaching work with a whole class?

    The best evidence says not on its own. The structure was built for small groups with an adult inside each one, and the attempts to scale it to whole classes have produced much smaller effects or none at all.

    The strongest test is Okkinga’s randomized trial: 369 students in grade 7 in lower-track classes, 10 treatment classes against 10 control classes, weekly lessons across a school year, teachers given three hours of training plus six coaching visits. No significant difference on the comprehension post-test, and a two-year follow-up found no differential growth either. Her meta-analysis found effects larger when the trainer was a researcher rather than a teacher.

    One honest complication: Rosenshine and Meister found the opposite pattern on group size. They report significant results with groups of 18 and 19, and note that if there is any pattern it is for non-significant results to come from smaller groups. They also detected no difference between teacher-led and experimenter-led lessons. The later, larger evidence points the other way, but the literature does genuinely disagree here and anyone telling you it is settled has read one half of it.

    Cost is worth naming while you are deciding. The packaged programme in the 2026 trial ran about £2,759 per school across three years, roughly £77 per pupil per year. The structure itself is free. If a department is going to be told to run this, the training is the budget line, not the role cards — every study where it failed had thin training behind it.

    What did predict outcomes in the whole-class trial was the quality of the strategy instruction, which explained an additional 37 percent of the variation between classes. That is the finding a secondary teacher should take away. The structure is a container. What goes into it is the intervention.

    What about the 0.74 effect size everyone quotes?

    Leave it alone. Reciprocal teaching appears in the Visible Learning ranking at d = 0.74, 27th of 252 influences, and the published ranking does not disclose how many meta-analyses, studies or effects that figure aggregates.

    That is not a claim that the number is wrong. It is a claim that you cannot check it, which matters when the same table is quoted in staff meetings as though it were a measurement. The method behind those rankings has a published statistical critique in the McGill Journal of Education, which argues the averages pool incompatible dimensions — a critique of the aggregation method generally, not of this row specifically.

    Rosenshine and Meister’s two numbers are more useful anyway, precisely because they are separated by the thing that turned out to matter.

    Numbered list of five steps for running reciprocal teaching in a secondary class period, covering modeling the strategies first, choosing a hard text, group size, teacher prompting and session length.

    How do you run reciprocal teaching in a secondary class period?

    Teach the strategies first, then hand over the roles, and keep the groups small enough that turns come round quickly. The reviews found gains more often where explicit teaching came before the dialogues.

    1. Model one strategy at a time, for days, not minutes. Rosenshine and Meister found that when the dialogues ran without explicit teaching first, only three of nine studies got significant results.
    2. Write the four jobs on four cards and stop there. The four descriptions in the graphic above are the whole of what belongs on a role card. Nothing here requires a purchased kit, and this site does not put anything behind an email address.
    3. Pick a passage that is actually hard. A text with nothing confusing in it gives the clarifier nothing to do, and the role turns into a formality that students see through immediately.
    4. Keep groups to six to eight. That is Palincsar’s own guidance — bigger than eight and turns come too slowly to hold anyone’s attention.
    5. Sit inside a group and prompt. Student-led does not mean teacher-absent. In the one grade 9 content-area study of this, the teacher was still needed to prompt and prod, and student-led sessions had mixed results depending on who was in the group.
    6. Stop at about twenty minutes. Long enough for two or three passes through the roles, short enough to leave the rest of the period for the content. That is roughly the session length the original studies used.

    One thing the sequence above hides: going first is expensive. The students this was built for are weak comprehenders, and you are asking one of them to summarize a hard passage out loud in front of peers. Let everyone write their question or summary before anybody says one, and do not open with the student who reads worst. The writing makes the turn survivable.

    Expect to cover less material at first. Palincsar says plainly that the primary objective is teaching reading processes and that content coverage grows back as students get better at it. If your department head needs to know why week two is slower than usual, that is the answer and it is in print.

    What goes wrong with reciprocal teaching?

    The roles become a ritual. Students learn the shape of each turn and perform it without doing the thinking underneath, and from the front of the room a class doing this looks exactly like a class doing it properly.

    The evidence for that is not anecdotal. A dissertation studying grade 9 readers in a social studies setting recorded clarification turns that went “Does anyone need anything clarified? No. OK”, questions that asked only for a date, a place or a person, and predictions that restated the subheading back to the group. Some roles were more sought after than others, and the teacher was still needed to prompt and prod.

    It is worth being fair about why that happens. From a desk, “no, nothing to clarify” is the rational answer, because saying you did not understand the paragraph is an admission in front of people you sit with all year. The role does not fix that by existing. A text with something genuinely confusing in it does, because then not understanding is the text’s fault rather than yours.

    The second failure is logistics, not pedagogy. In the 2026 trial, the obstacles teachers named were timetabling (65 percent), not enough staff (32 percent) and nowhere to put the groups (29 percent). The third is that the training is usually thinner than the studies’ own training, which was itself thin: three sessions in the original, three hours plus six coaching visits in the trial that found nothing.

    And the one the federal practice guide warns about directly: strategies can crowd out the reading. Its panel writes that “the goal should always be comprehending texts—not using strategies” and that too much focus on the process “can take away from students’ understanding of the text itself.” That is the same trap as turning marking up a page into a compliance exercise, and it is the reason this site is sceptical of techniques that feel like studying without being studying.

    Does it work in content-area classes like history and science?

    The evidence there is thin and what exists is not encouraging about fidelity. Most reciprocal teaching research happens in reading classes or pull-out groups, not in a content-area room with a curriculum to cover.

    The clearest look at what happens in a subject classroom comes from a study of nine experienced history teachers in four Dutch secondary schools, working with classes in grade 7. After training, the researchers found teachers “often did not fully or correctly implement” the practices, that reading texts “occurred sparingly during regular lessons,” and that the instruction that did happen focused on how to study rather than how to read. One teacher wrote “I have no time to do this” in the manual. Another said “I really prefer telling stories.” The authors concluded that positive teacher attitudes were not enough.

    For English learners the picture is similarly unfinished. A systematic review of 18 studies covering 1,674 ESL and EFL students found six studies at secondary level and no pooled effect size at all, with several studies showing gains only in attitude. The best secondary-specific randomized trial, 315 students in Year 7 across 14 schools, found a significant gain on sentence completion (+0.25) but not on passage comprehension (+0.13), with the overall reading measure at p = 0.06.

    Clay’s take: it is a discussion structure, and that is enough

    I would use this and I would stop calling it a reading intervention.

    What reciprocal teaching reliably produces is students talking about a text in a way that makes their thinking visible, which is worth a great deal in a room where the alternative is nodding. What it does not reliably produce is movement on a reading score, and the honest version of the pitch says so. The four roles give a quiet student a job and a reason to speak, and they give me something to listen to besides whether the homework got done.

    The part I would not skip is the modeling. Every study where this failed had thin training behind it, and the one thing the whole literature agrees on is that the dialogue has to be taught before it is handed over. Give it a week of your own modeling before you give a student a role card, or you will get four students performing four rituals on a text nobody read.

    What to do next week

    Pick one passage you already assign that students routinely misread, and teach the questioning role on it — just that one, with you doing it out loud.

    Ask students to write a question a teacher could ask, then compare the questions as a class and sort them into the ones that need the text and the ones that need only a memory. That single sort is the whole point of the role, it takes fifteen minutes, and it tells you whether this class is ready to run the other three. If it goes well, pair it with a second pass through the same passage rather than a new text.

    Frequently Asked Questions

    What are the four steps of reciprocal teaching?

    Predicting, questioning, clarifying and summarizing, all applied to the same passage with students taking turns leading the discussion. The teacher models each one first, then hands the role over gradually. Palincsar and Brown’s original paper lists them as summarizing, questioning, clarifying and predicting, and the order is less important than the dialogue itself.

    Is reciprocal teaching evidence based?

    It has four decades of studies behind it and a mixed record. Rosenshine and Meister reported es = .87 on researcher-made tests and .32 on standardized tests. The What Works Clearinghouse rates it ‘mixed effects’ across six qualifying studies. The largest trial, across 295 schools, found 0.06 and one month’s additional progress.

    Does reciprocal teaching work in a whole class?

    The evidence is weaker there than in small groups. A year-long randomized trial with 369 students in grade 7 found no significant difference between treatment and control classes, and a meta-analysis found larger effects when a researcher rather than a teacher ran the training. What predicted results was the quality of the strategy instruction itself.

    How long does it take to see results from reciprocal teaching?

    In the original studies most students reached criterion within about 15 days of daily sessions, but those were small groups taught by researchers or closely trained teachers. Larger trials running 12 to 16 weeks have produced much smaller gains. Expect better discussion quickly and movement on reading scores slowly, if at all.

    What group size works best for reciprocal teaching?

    Palincsar recommends six to eight students, because larger groups make turns come too slowly to hold attention. Rosenshine and Meister complicate this: they recorded significant results with groups of 18 and 19, and found non-significant results tended to come from smaller groups. Six to eight is the safer starting point for a secondary class.

    Why do students treat the reciprocal teaching roles as a ritual?

    Because the shape of each turn is easy to perform without the thinking underneath. A study of grade 9 readers recorded clarification turns answered with a flat no, questions asking only for a date or a name, and predictions that restated the subheading. Choosing a text with something genuinely confusing in it is the main fix.

    Can reciprocal teaching be used in history or science classes?

    It can, but the content-area evidence is thin and fidelity is the problem. In a study of nine experienced history teachers, researchers found the practices often were not implemented correctly, that reading happened rarely in regular lessons, and that instruction drifted toward how to study rather than how to read. Training time was the constraint.

    Is reciprocal teaching the same as a literature circle?

    No. Both assign roles to students in small groups, but reciprocal teaching uses four fixed comprehension strategies on a single passage and is designed as strategy instruction, with the teacher modeling each role before handing it over. Literature circles are organized around discussion of a longer text and vary widely in structure.

    Sources

    • Palincsar, A. S., & Brown, A. L. (1984). Reciprocal teaching of comprehension-fostering and comprehension-monitoring activities. Cognition and Instruction, 1(2), 117–175. Full text. Source of the two original studies, their sample sizes and grade levels, the four strategies, the 15-month average gain and the eight-week decline.
    • Rosenshine, B., & Meister, C. (1993). Reciprocal Teaching: A Review of 19 Experimental Studies. Technical Report 574, Center for the Study of Reading, University of Illinois. Full text. Source of es = .87 and es = .32, the explicit-teaching finding, the group-size finding and the age range. The report is internally inconsistent about how many studies used each test type.
    • Park, H. (2007–08). Critical review: reciprocal teaching. University of Western Ontario. Review. Cited as a secondary source for the published 1994 figures of .88 and .32, because that article could not be opened, and for the argument that experimenter-made tests were easier.
    • Okkinga, M., van Steensel, R., van Gelderen, A. J. S., van Schooten, E., Sleegers, P. J. C., & Arends, L. R. (2018). Effectiveness of reading-strategy interventions in whole classrooms: a meta-analysis. Educational Psychology Review. Publisher record. Source of d = .186 and d = .431 across 52 studies and of the researcher-versus-teacher moderator.
    • Okkinga, M. (2018). Teaching Reading Strategies in Classrooms: Does It Work? Doctoral thesis, University of Twente. Full text. Source of the 369-student randomized trial, the null result, the two-year follow-up and the 37 percent of class-level variance explained by instruction quality.
    • What Works Clearinghouse, Institute of Education Sciences (2010). Reciprocal Teaching intervention report appendix. Report. Source of the “mixed effects” rating, the 0.16 domain average, the six study populations and the −0.48 negative result.
    • Institute of Education Sciences (2008). Improving Adolescent Literacy: Effective Classroom and Intervention Practices. NCEE 2008-4027. Practice guide. Source of the Strong rating for comprehension strategy instruction generally, and of the warning that strategies can displace comprehension. Reciprocal teaching is named once, under the intensive-intervention recommendation.
    • Behavioural Insights Team for the Education Endowment Foundation (2026). Reciprocal Reading: effectiveness trial evaluation report. Report. Source of the 295-school, 4,263-pupil result: 0.06, one month’s progress, p = 0.117, and the timetabling, staffing and space obstacles. The pupils were aged 9 to 11.
    • Thurston, A., Cockerill, M., Taylor, A., Chiang, T.-H., & O’Keeffe, J. (2020). An efficacy randomized controlled trial of Reciprocal Reading in secondary schools. Queen’s University Belfast. Scientific report. Source of the 315-student Year 7 trial and its subscale results.
    • Palincsar, A. S. (2017). Using reciprocal teaching to support strategy instruction and language use among second language learners. Contact, TESL Ontario. Article. Source of the six-to-eight group size, the statement that only the dialogic version was effective, and the note about content coverage.
    • Hogewood, R. H. (2004). Building a Reading Bridge: The Impact of Reciprocal Teaching on Poor Readers in Ninth Grade Social Studies. Doctoral dissertation, University of Maryland. Full text. Source of the transcript evidence of ritual role performance and of the time-on-task figures. It had no control group, and no effect sizes were legible in the copy read, so none is quoted.
    • ter Beek, M., Opdenakker, M.-C., Deunk, M. I., & Strijbos, J.-W. (2019). Teaching reading strategies in history lessons: A micro-level analysis of professional development training and its practical challenges. Studies in Educational Evaluation, 63. Full text. Source of the fidelity findings and the teacher quotations.
    • Ting Pick Dew, Swanto, S., & Pang, V. (2021). The Effectiveness of Reciprocal Teaching as Reading Comprehension Intervention: A Systematic Review. Journal of Nusantara Studies, 6(2). Full text. Source of the 18-study review, the 1,674 students and the six secondary-level studies. It reports no pooled effect size.
    • Visible Learning. Hattie Ranking: 252 Influences And Effect Sizes. Ranking page. Source of the d = 0.74 listing, and of the fact that the page discloses no study or meta-analysis count for it.
    • Bergeron, P.-J., with Rivard, L. How to engage in pseudoscience with real data: A criticism of John Hattie’s arguments in Visible Learning from the perspective of a statistician. McGill Journal of Education, 52(1). Full text. Cited for the critique of the aggregation method; it does not discuss reciprocal teaching.

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

Teacher Emergency Toolkit — practical resources, real classroom support. Shop on TPT.Teacher Emergency Toolkit — practical resources, real classroom support. Shop on TPT.