The Elevate Blog banner: Real Classrooms. Practical Ideas. Higher Expectations. Three students climb a rocky ridge at sunrise, each pulling the next one up, toward a teacher reaching down to help.

Tag: assessment

  • Learning Targets: How to Write One a Student Can Actually Use

    Learning Targets: How to Write One a Student Can Actually Use

    By Clay Shumate

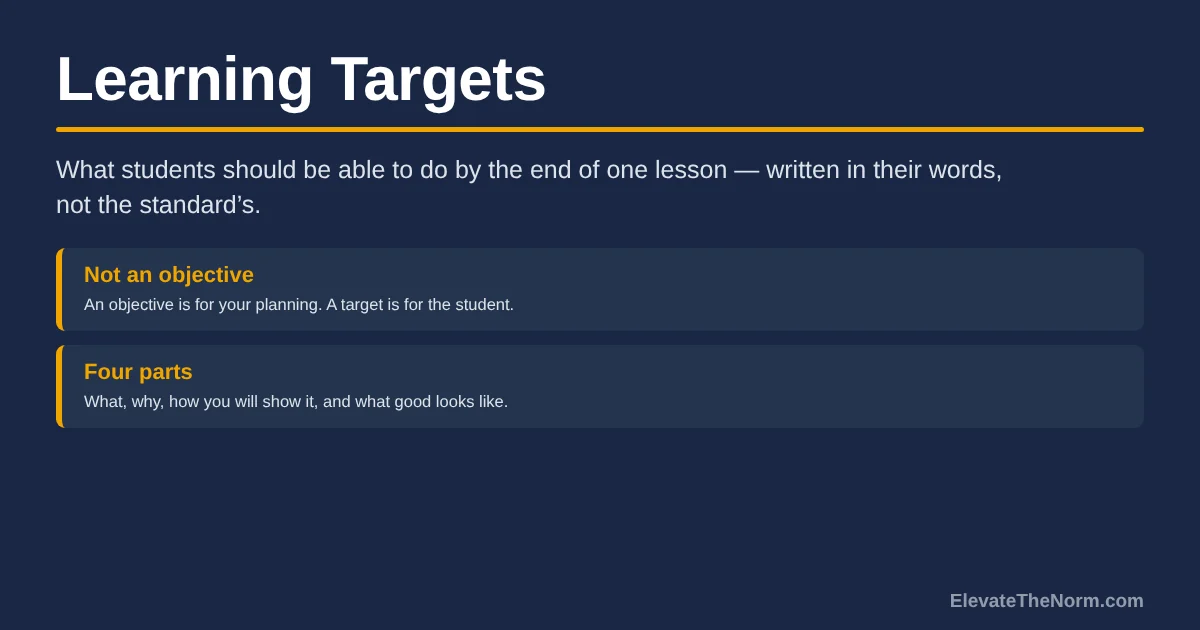
    A learning target is a short statement of what a student should be able to do by the end of one lesson, written in the student’s own language and paired with a description of what good work looks like. It is not the standard. It is not the objective in your plan book. Those are written for you. The target is written for them.

    That distinction sounds like semantics until you walk into a room at minute twenty-five and ask three students what they are working on. If you get three different answers, there was no target. There was a sentence on a whiteboard.

    Key Takeaways

    • A target answers three student questions: what am I learning, why does it matter, and how will I know when I have it. Drop the third and you have a topic, not a target.
    • Objectives and learning targets are not the same document. An objective is a planning tool written in standards language. A target is a communication tool written in student language.
    • The evidence is thinner than the training says. One video study of 13 physics classes found real benefits from goal clarity. A broad review by the same lead author put “goal setting and orientation” near the bottom of the list at .03.
    • In real classrooms, goals are usually implicit. Across 146 videotaped lower-secondary maths lessons in five Nordic systems, only about 19 percent of segments had an explicit goal. Most had to be inferred by the researchers.
    • Do not quote the famous effect sizes. The 0.5 and 0.88 numbers that circulate for learning intentions come out of a synthesis whose method has been published as statistically unsound. Argue for targets on what they do for students, not on a number.

    What Is a Learning Target?

    It is a lesson-sized piece of learning, stated from the student’s point of view, that a student could repeat back in their own words and use to judge their own work before you grade it.
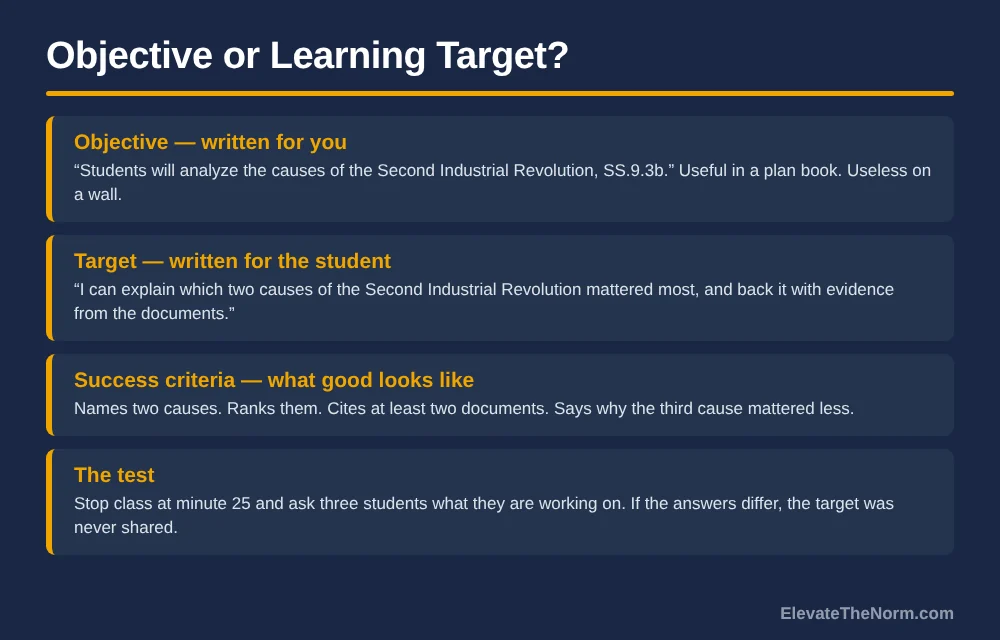
    Four-row comparison graphic showing an instructional objective written in standards language, the same content rewritten as a student-facing learning target, the matching success criteria, and a test for whether the target was actually shared
    The same lesson, written three ways. Only one of them is for the student.

    Connie Moss, Susan Brookhart and Beverly Long put it plainly in Educational Leadership: a shared learning target “unpacks a ‘lesson-sized’ amount of learning” and frames the lesson from where the student is sitting. They argue instructional objectives “are not designed for students but for the teacher,” and that targets have to be translated into language that is developmentally appropriate and culturally respectful before they are worth anything.

    They also name the part most people skip. The single best way to share a target, they argue, is a learning experience that embodies it — a task where finishing the task is the evidence. Not a sentence read aloud at the bell and never mentioned again.

    How Is a Learning Target Different From an Objective?

    An objective tells you what you are teaching. A target tells a student what they are learning and how they will know they got there. You need both, and they are written at different times, for different readers, in different words.

    Here is the same lesson three ways.

    • The standard: “Analyze the causes and effects of industrialization in the late nineteenth century.”
    • The objective, in your plan book: “Students will analyze primary and secondary sources to evaluate the relative significance of three causes of the Second Industrial Revolution.”
    • The target, on the board and in their mouths: “I can explain which two causes of the Second Industrial Revolution mattered most, and back it up with evidence from the documents.”

    The third one is the only version a fifteen-year-old can act on. It also tells them what you will not be asking for, which matters more than teachers usually admit. Students spend a lot of class time guessing at the real assignment.

    Do Learning Targets Actually Improve Learning?

    The honest answer is that goal clarity shows up as a real effect in a small number of careful classroom studies, and close to nothing in broad averages across the field. That is a reason to write good targets, not a reason to build a school initiative on them.
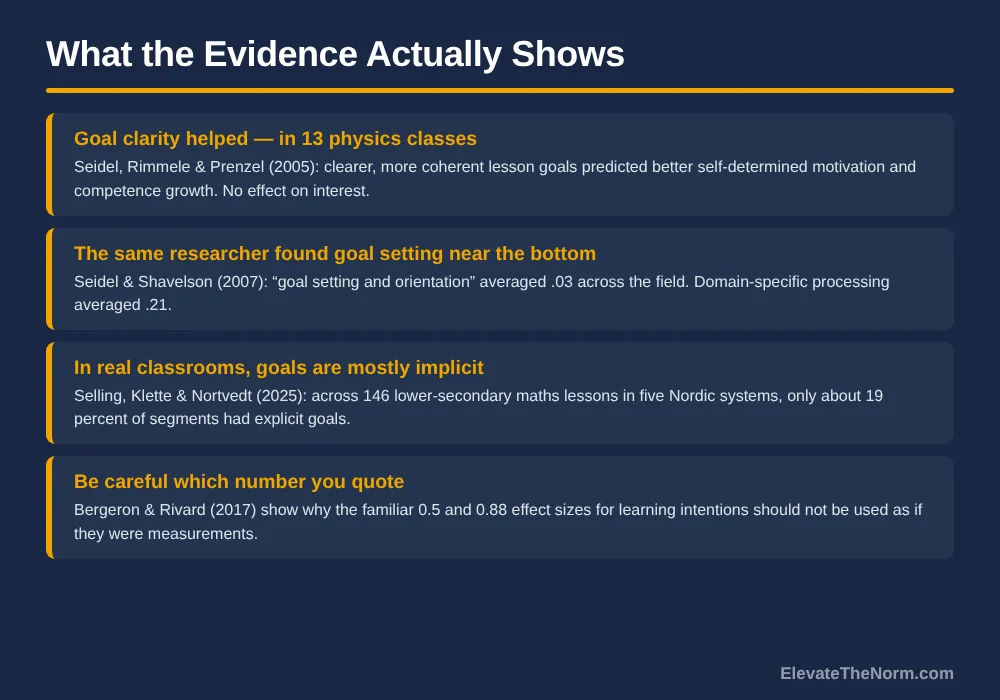
    Four-row research graphic summarizing evidence on learning targets: Seidel Rimmele and Prenzel 2005 on goal clarity in 13 physics classes, Seidel and Shavelson 2007 placing goal setting near the bottom at .03, Selling Klette and Nortvedt 2025 finding only about 19 percent of lesson segments had explicit goals, and Bergeron and Rivard 2017 on why familiar effect sizes should not be quoted
    Four findings that should change how confidently anyone sells you learning targets.

    Start with the study that supports the practice. Tina Seidel, Rolf Rimmele and Manfred Prenzel video-recorded introductory lessons for two topics across 13 physics classes and rated how clear and coherent the lesson goals were. Classes with high goal clarity and coherence reported more supportive learning conditions, more self-determined motivation, and better organization of their own learning. Over a school year, high clarity was also linked to positive competence development. It had no effect on individual interest.

    Thirteen classes, one subject. That is a careful study, not a large one, and the abstract does not report the grade level or an effect size. Treat it as suggestive.

    Now the part the professional development rarely includes. Two years later Seidel co-authored a review of a decade of teaching-effectiveness research with Richard Shavelson in the Review of Educational Research. Across the field, “goal setting and orientation” averaged .03. Domain-specific processing — the actual thinking students do inside your subject — averaged .21, by far the largest component. The same researcher who found goal clarity mattered in physics classrooms also found that, averaged across everything, goal setting is one of the smallest levers in teaching.

    Both of those can be true. Clarity probably matters most when it is the thing that is missing, and almost not at all once it is adequate. That is how most classroom variables behave.

    There is also a related body of work on teacher clarity, which is broader than learning targets. Titsworth, Mazer, Goodboy, Bolkan and Myers ran two meta-analyses, one covering 144 reported effects across more than 73,000 participants. They found a moderate overall relationship, with clarity accounting for roughly 13 percent of the variance in student learning, and a larger effect on affective learning than on cognitive learning. Worth knowing — but the ERIC record does not state what education levels those studies drew on, so I am not going to hand it to you as a secondary-school finding.

    Why Shouldn’t I Quote the Effect Size I Was Shown in Training?

    Because the most-quoted numbers for learning intentions and success criteria come from a synthesis whose statistical method has been formally challenged in print, and the challenge has not been answered to the satisfaction of people who do statistics for a living.

    Pierre-Jérôme Bergeron’s critique, translated by Lysanne Rivard in the McGill Journal of Education, lays out the specifics: common language effect values that come out negative or above 100 percent, averaging incompatible effects together, converting correlations into Cohen’s d in ways that make weak relationships look strong, and a 0.4 “desired effect” threshold with no stated basis. He notes that a correlation of .196 lands in the desired zone while explaining under four percent of the variance. His conclusion is blunt: the method should be qualified as pseudoscience.

    You will still see 0.88 quoted for success criteria. It turns up, for example, in a 2023 practitioner article in the NECTFL Review, attributed onward to another source. That article collects no original data and reports no sample. The number has a long life because it is convenient, not because it was measured in rooms like yours.

    None of this means targets are useless. It means you should defend them the way you would defend any other practice that asks students to be treated as capable adults — on the grounds that a student who knows what they are doing and why can do something about it.

    Why Don’t Students Know the Target Even When It’s on the Board?

    Because in most lessons the goal is never actually said out loud. Researchers watching real classrooms find they have to infer the goal themselves most of the time.

    Selling, Klette and Nortvedt analyzed 146 videotaped lessons from 48 lower-secondary mathematics classrooms across Norway, Sweden, Finland, Denmark and Iceland. Using the PLATO observation protocol, they found most lesson segments scored a 2 on Purpose — meaning the goal existed but had to be inferred. Only about 19.4 percent of segments scored a 3 or 4 for explicit goals, and just 3.7 percent scored at the top. In Sweden, roughly 94 percent of segments sat at the inferred level.

    They also found that in Iceland, Norway and Sweden, more than 40 percent of segments made no reference at all to what students already knew. A goal with no bridge from prior knowledge is a destination with no road to it.

    Two honest caveats. This study measured instruction, not outcomes — it did not test whether clearer goals produced more learning. And the only relationship it reports is a weak correlation (r = 0.265) between the Purpose score and references to prior knowledge. What it shows is simply that the practice everyone says they do is rare when someone puts a camera in the room.

    How Do You Write a Learning Target?

    Four parts: what the student will be able to do, why it is worth doing, how they will show it today, and what good looks like. If you cannot write all four in under two minutes, the target is too big for one lesson.
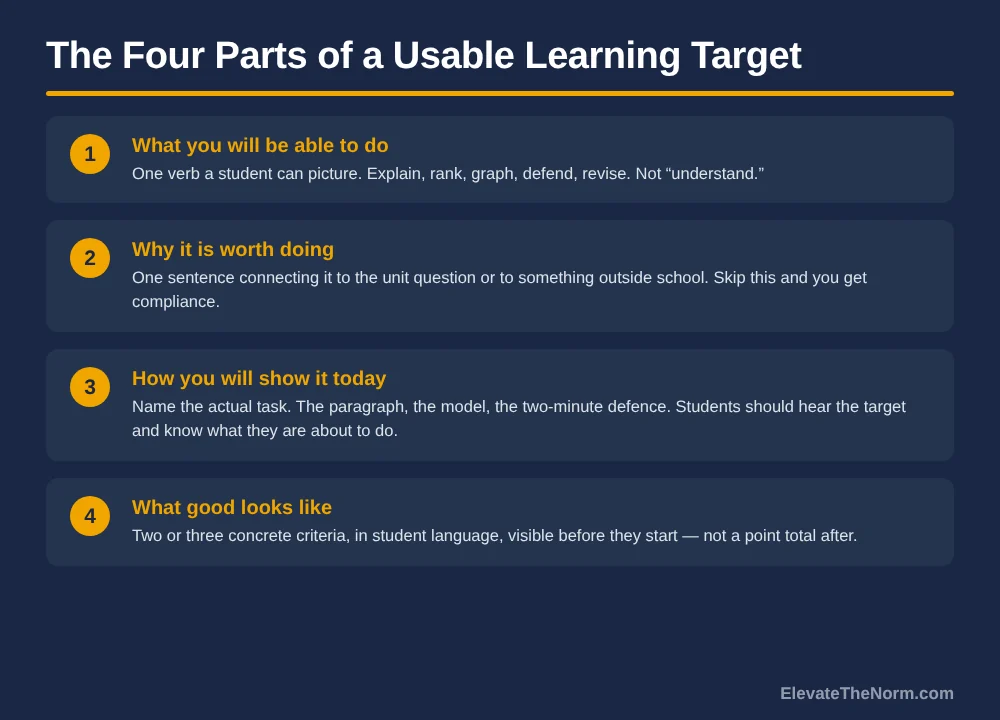
    Numbered four-card graphic listing the parts of a usable learning target: what you will be able to do, why it is worth doing, how you will show it today, and what good looks like
    Four parts. Drop any one of them and the target stops working.

    1. What you will be able to do. One verb a student can picture. Explain, rank, graph, defend, revise, predict, trace. Not “understand,” not “be exposed to,” not “explore.” If a student cannot tell from the verb whether they are writing, talking, building or calculating, pick a different verb.

    2. Why it is worth doing. One sentence tying it to the unit question or to something outside the building. Skip this and the best you get is compliance. Teenagers give you compliance cheaply and it is worth exactly what you paid.

    3. How you will show it today. Name the actual task. The paragraph, the labeled model, the two-minute defense, the corrected problem set. Students should hear the target and already know what they are about to be doing.

    4. What good looks like. Two or three concrete criteria, in student language, visible before they start. Not a point total handed back afterward.

    Learning Target Examples for Grades 6–12

    Each of these is one lesson, with criteria attached. Steal the shape, not the content.

    Social studies, grade 9

    Target: “I can rank three causes of an event by importance and defend my ranking with evidence.”
    Criteria: Names all three causes accurately. Puts them in an order and says why. Uses at least two documents. Names the strongest objection to my ranking.

    Science, grade 7

    Target: “I can tell the difference between a result my data supports and one it doesn’t.”
    Criteria: Points to the specific numbers behind each claim. Says what the data cannot tell us. Does not use the word “prove.”

    Algebra, grade 8

    Target: “I can find my own mistake in a solved equation and explain what rule I broke.”
    Criteria: Circles the exact line. Names the property or step. Rewrites from that line forward instead of starting over.

    English, grade 11

    Target: “I can rewrite a paragraph so the evidence comes before the opinion, and say why that order is stronger.”
    Criteria: Quote appears before the claim is restated. Explains the quote in my own words. Cuts at least one sentence that was doing no work.

    Notice what is missing from all four: a standard code. Put the code in your plan book and your standards-based gradebook where it belongs. A student does not need to read “SS.9.3b” to learn anything.

    What Are Success Criteria, and How Are They Different?

    The target says what you are learning. The success criteria say what it will look like when you have learned it. The criteria are the half that gets dropped, and they are the half students actually use.

    Moss, Brookhart and Long describe success criteria as “developmentally appropriate descriptions and concrete examples” of quality — not grades and not item counts. Three to five points. Rubrics and real work samples help, because most students cannot picture “well organized” until they have seen two versions side by side.

    The strongest version of this is letting students help build the criteria from exemplars. Hand two anonymous pieces of past work to a table group, ask them what the better one does that the other does not, and write their answers on the board. You will get most of your rubric back in their words, which makes it far more likely to be used. It also pairs naturally with student self-assessment, which is close to pointless when students are guessing at the standard.

    A Two-Minute Check Before You Post It

    • Can a student read it and say what they will be doing in the next ten minutes?
    • Is there exactly one lesson in it? Two verbs usually means two days.
    • Does it survive the “so what” question without a speech?
    • Are the criteria specific enough that two students would grade the same paper the same way?
    • Is there any jargon in it you would not use at a dinner table?
    • Can you check it at the end of class in under four minutes? Pick one of the quick formative checks and name it before the lesson starts. If you cannot, you have no way of knowing whether the target landed.

    That last one matters more than the wording. A target with no check at the end of the period is a prediction nobody ever scores.

    Where Learning Targets Go Wrong

    They become a compliance item

    The fastest way to kill the practice is to audit it. When a walkthrough form has a box for “objective posted,” every board in the building gets a sentence on it by 8:05 and nothing else changes. If you lead a building and you want to know whether targets are working, do not look at the wall. Ask three students in the hallway what they were working on and why. That takes ninety seconds and it is the only version of this audit that measures anything.

    They get written for five preps every night

    Nobody is writing twenty-five fresh targets a week in December. The realistic move is to write targets at the unit level once, during planning, and break them into lesson-sized pieces as you go. Most units have four to six real targets in them, not twenty. Reusing a target across two days is fine and honest — it tells students the thing is hard enough to take two days.

    They are read aloud and then abandoned

    A target mentioned at the bell and never again is theater, and students know it faster than adults do. Come back to it twice: once in the middle, when you stop and ask what part of it they have so far, and once at the end, when the exit check is visibly the same thing the target promised.

    They get confused with a schedule

    “Today we will finish the packet and start the lab” is an agenda. Agendas are useful. They are not targets, and posting one in the target’s slot is how most classrooms end up believing they do this already.

    What About Targets for a Multi-Day Project?

    Keep one project-length target for the whole arc, and write a smaller daily target underneath it that names today’s piece.

    On a three-week project, “I can design and defend a solution to a real problem” is the arc. Today’s is “I can write two interview questions that will get me something I cannot find online.” Students need both: the arc so the work has a point, the daily piece so they know what finished looks like by 2:15. This is also where students setting their own goals stops being an add-on — once the criteria are public, a student can name their own next step without you assigning it.

    What to Say to a Parent

    You will get the question eventually, usually phrased as “what are they actually supposed to be learning?” A posted target makes that a short conversation. “Here is the target for this week, here is what good work looks like on it, and here is where your son is against those three criteria” is a different conference than reading a column of percentages aloud. It also makes a low grade explicable instead of mysterious, which is most of what parents want from a conference.

    Learning Targets: What to Do in Your Next Lesson

    Pick one lesson you are teaching this week. Write the target in a student’s voice, add three criteria, and name the four-minute check that will tell you whether it landed. That is the entire practice.

    Then do the thing that actually tests it: stop the class halfway through and ask three students what they are working on and how they will know they did it well. If you get the same answer three times, the target is doing its job. If you get three different answers, the problem is not that your students were not listening. The sentence was never written for them in the first place.

    And if you only change one thing, add the criteria. The target without them is a topic.

    Check the target at the bell. The fastest way to find out whether students hit today’s learning target is a one-question exit ticket. Our sister site has free exit tickets and exit slips for grades 6–12, plus daily bell ringers to open the period.

    Frequently Asked Questions

    What is a learning target?

    A learning target is a short statement of what a student should be able to do by the end of one lesson, written in the student’s own language and paired with a description of what good work looks like. It is distinct from an instructional objective, which is written in standards language for the teacher’s planning. Moss, Brookhart and Long describe a shared learning target as unpacking a “lesson-sized” amount of learning from the student’s point of view.

    What is the difference between a learning target and an objective?

    The reader. An objective is a planning document written in standards language for the teacher — “students will analyze primary sources to evaluate the relative significance of three causes.” A learning target is a communication document written for the student — “I can explain which two causes mattered most, and back it up with evidence from the documents.” You need both, and they are written at different times in different words.

    Do learning targets improve student achievement?

    The evidence is mixed and thinner than most training implies. Seidel, Rimmele and Prenzel (2005) found that clearer, more coherent lesson goals across 13 physics classes predicted more self-determined motivation and positive competence development over a year, though no effect on interest. But Seidel and Shavelson’s (2007) review of a decade of teaching-effectiveness research placed “goal setting and orientation” near the bottom at .03, well below domain-specific processing at .21. Clarity most likely matters when it is missing and much less once it is adequate.

    Why shouldn’t I quote the 0.88 effect size for success criteria?

    Because it traces back to a synthesis whose statistical method has been formally challenged in print. Bergeron and Rivard (2017), in the McGill Journal of Education, document miscalculated common language effects, averaging of incompatible effects, unreliable conversion of correlations into Cohen’s d, and an unexplained 0.4 threshold, and conclude the methodology should be qualified as pseudoscience. Argue for learning targets on what they do for students, not on a number.

    How many learning targets should one lesson have?

    One. If your target contains two verbs, you most likely have two lessons. A realistic planning approach is to write four to six real targets at the unit level during planning and break them into lesson-sized pieces as you go, rather than drafting a fresh target every night for every prep. Reusing a target across two days is honest — it tells students the content is hard enough to need two days.

    What are success criteria?

    Success criteria describe what it will look like when a student has met the target. Moss, Brookhart and Long call them developmentally appropriate descriptions and concrete examples of quality — not grades and not item counts. Three to five specific points works. The strongest version is building them with students from two anonymous work samples, because most students cannot picture “well organized” until they have seen a better and a worse version side by side.

    Do students actually hear the learning target?

    Usually not. Selling, Klette and Nortvedt (2025) analyzed 146 videotaped lessons from 48 lower-secondary mathematics classrooms in five Nordic systems and found that only about 19.4 percent of lesson segments contained an explicit goal; in most, researchers had to infer the goal themselves. More than 40 percent of segments in three of the countries made no reference to students’ prior knowledge. The test in your own room is to stop at minute 25 and ask three students what they are working on.

    Should administrators check whether learning targets are posted?

    Checking the wall measures the wall. If a walkthrough form has a box for “objective posted,” every board in the building will have a sentence on it and nothing else will change. The useful version takes ninety seconds: ask three students in a hallway what they were working on and how they would know they did it well. That measures whether the target was shared, which is the only thing that matters.

    Sources

    1. Seidel, T., Rimmele, R., & Prenzel, M. (2005). Clarity and Coherence of Lesson Goals as a Scaffold for Student Learning. Learning and Instruction, 15(6), 539–556. Video ratings of introductory lessons in 13 physics classes; high goal clarity and coherence predicted supportive learning conditions, self-determined motivation, better organization of learning, and positive competence development over a year, with no effect on individual interest. Thirteen classes, one subject; the ERIC abstract does not state grade level, country, or effect sizes, and the full text is paywalled. https://eric.ed.gov/?id=EJ724179
    2. Seidel, T., & Shavelson, R. J. (2007). Teaching Effectiveness Research in the Past Decade: The Role of Theory and Research Design in Disentangling Meta-Analysis Results. Review of Educational Research, 77(4), 454–499. Weighted Fisher’s Z-based effects across all outcomes: domain-specific processing .21; goal setting and orientation .03; organization of learning .01. These are not Cohen’s d and should not be read as such; cited from the abstract and published tables, as the full article is paywalled. https://journals.sagepub.com/doi/10.3102/0034654307310317
    3. Selling, A. J. V., Klette, K., & Nortvedt, G. A. (2025). Teachers’ Goal Communication in Nordic Mathematics Classrooms. Mathematics Education Research Journal, 37(3), 483–506. 146 videotaped lessons from 48 lower-secondary mathematics classrooms in Norway, Sweden, Finland, Denmark and Iceland; about 19.4 percent of segments scored 3 or 4 for explicit goals and 3.7 percent scored 4. The study measured instruction, not student outcomes. https://link.springer.com/article/10.1007/s13394-024-00498-w
    4. Titsworth, S., Mazer, J. P., Goodboy, A. K., Bolkan, S., & Myers, S. A. (2015). Two Meta-analyses Exploring the Relationship Between Teacher Clarity and Student Learning. Communication Education, 64(4), 385–418. 144 reported effects (N = 73,281) and a second random-effects analysis of 46 studies (N = 13,501); clarity accounted for roughly 13 percent of the variance in student learning, with a larger effect on affective than cognitive learning and significant unexplained heterogeneity. The ERIC record does not state the education levels sampled, so this is not presented here as a secondary-school finding. https://eric.ed.gov/?id=EJ1082982
    5. Bergeron, P.-J., & Rivard, L. (trans.) (2017). How to Engage in Pseudoscience With Real Data: A Criticism of John Hattie’s Arguments in Visible Learning From the Perspective of a Statistician. McGill Journal of Education, 52(1), 237–246. Documents miscalculated common language effects, averaging of incompatible effects, unreliable correlation-to-d conversion, and an unexplained 0.4 threshold. https://mje.mcgill.ca/article/view/9475
    6. Moss, C. M., Brookhart, S. M., & Long, B. A. (2011). Knowing Your Learning Target. Educational Leadership, 68(6), 66–69. Defines a shared learning target, distinguishes it from an instructional objective, and describes success criteria as developmentally appropriate descriptions and concrete examples rather than grades. A practitioner article, cited for its definitions rather than as empirical evidence. https://www.montanalanguageteachers.org/uploads/6/6/4/8/66489615/3_excerpts_brookhart_knowing_your_learning_target_march_2011.pdf
    7. Eagan, T. (2023). Unlocking Student Success: The Power of Success Criteria, Relationships, and Clarity. NECTFL Review, Number 90, 95–102. Cited as an example of the .88 success-criteria figure circulating in practitioner literature; the article reports no original data and no sample. https://files.eric.ed.gov/fulltext/EJ1382629.pdf
    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • Formative Assessment Strategies in Science That Catch a Misconception Before the Unit Test

    Formative Assessment Strategies in Science That Catch a Misconception Before the Unit Test

    By Clay Shumate

    Formative assessment strategies in science are the short, ungraded checks you run mid-lesson to find out what model a student is actually using — not just whether the answer is right. In science that distinction matters more than in most subjects, because a student can reach the correct result from a wrong theory and nobody finds out until a transfer question in March.

    That is the case for doing this. The case against overselling it comes next, and it is stronger than most articles on this topic will tell you.

    Key Takeaways

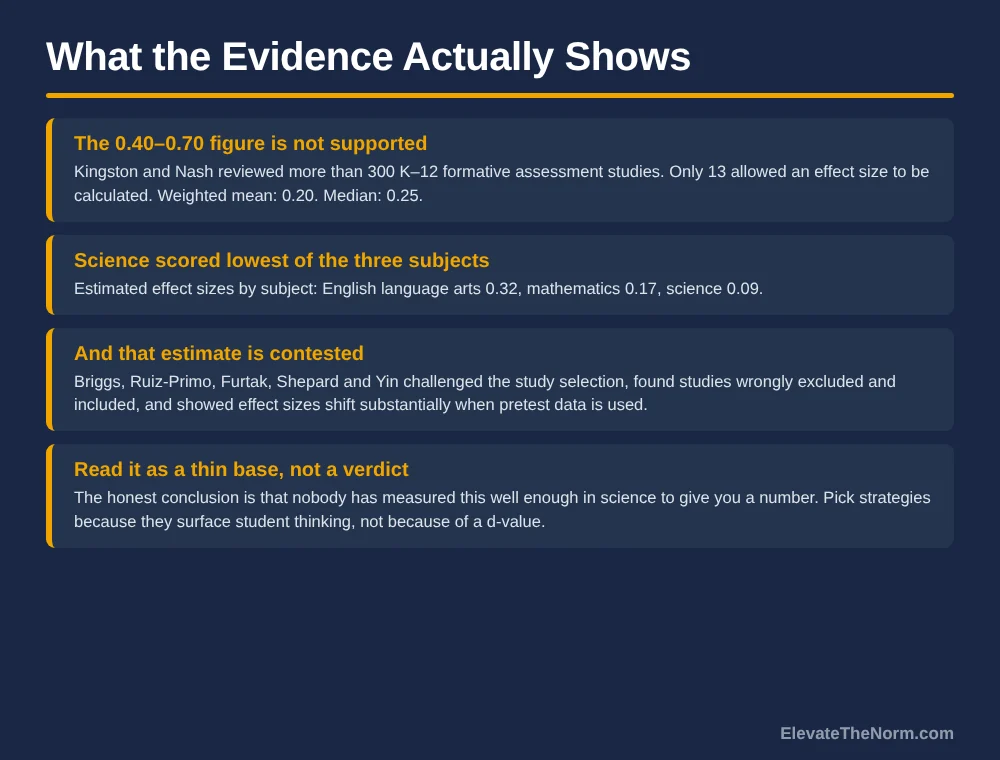
    • The famous effect size is not real. The often-quoted 0.40–0.70 for formative assessment was not supported when somebody went and checked. The best meta-analysis found a weighted mean of 0.20 — and 0.09 in science, the lowest of the three subjects.
    • That 0.09 is contested too. A published commentary by five assessment researchers challenged the study selection and the effect-size calculations. Do not use the small number as a reason to skip formative assessment any more than you should have used the big one as proof.
    • Chase the model, not the answer. The checks that pay in science are the ones that make a student’s underlying theory visible — a written prediction, a forced choice plus an explanation, a piece of reasoning.
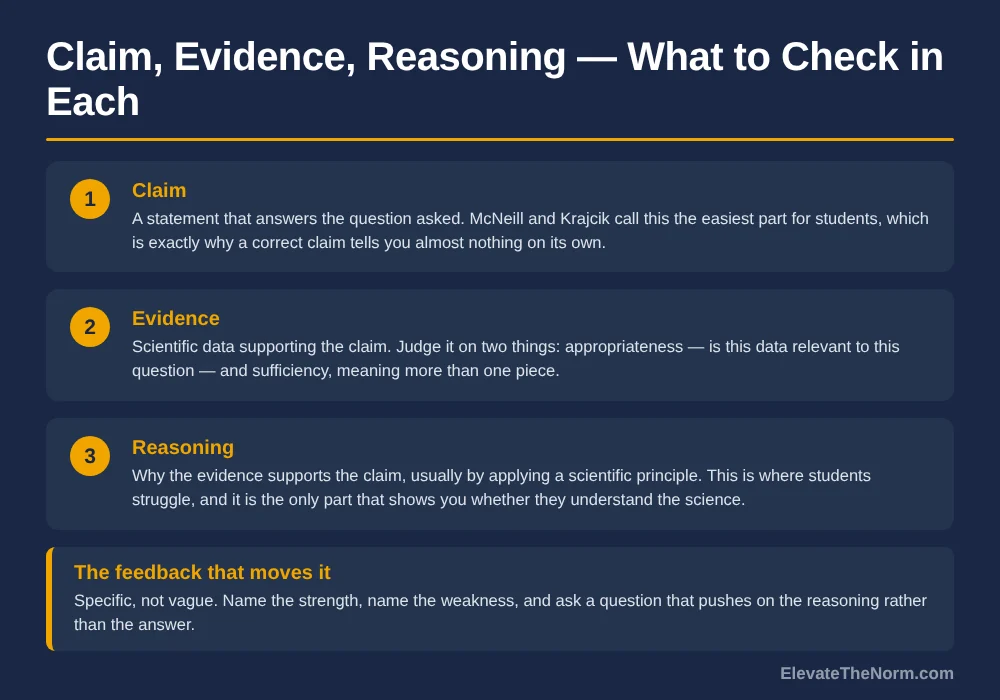
    • Reasoning is the part they cannot do. In the claim-evidence-reasoning framework, the claim is the easiest piece for students. A correct claim is close to no information on its own.
    • If it takes an evening to read, it will not survive October. Every strategy below is designed to be readable in the time between classes.

    What Are Formative Assessment Strategies in Science?

    They are checks run during instruction, for the purpose of changing instruction, and they are not graded. That last clause is the one people drop. A quiz you record is a small summative assessment, and the moment students know it counts they start writing what they think you want instead of what they believe — which destroys the only thing you were collecting it for.

    The Developing Assessments for the Next Generation Science Standards report from the National Research Council puts classroom assessment at the centre of instruction and separates its two jobs cleanly: formative assessment guides instructional decisions and lesson planning, summative assessment assigns grades. The same report sets the bar that makes science assessment hard. Three-dimensional science learning asks students to use science practices and crosscutting concepts in the context of disciplinary core ideas, and assessment tasks therefore need multiple components reflecting that connected use. The committee is blunt that tasks like these are challenging to design, implement and interpret, and that teachers will need real professional development to do it.

    This is the general version of the argument we make in the main list of formative assessment strategies. What follows is the part that is specific to a science room.

    Does Formative Assessment Actually Work Better in Science?

    On the measured evidence, science is the weakest of the three subjects studied — and the measurement itself is disputed. Anyone who tells you formative assessment is a 0.7-effect intervention in your biology class is quoting a number that was checked and did not hold up.

    Four-row graphic on formative assessment evidence: the 0.40 to 0.70 claim is unsupported, Kingston and Nash found a weighted mean of 0.20 from 13 usable studies, subject effect sizes of 0.32 for English language arts, 0.17 for mathematics and 0.09 for science, and a published critique of that estimate
    Science scores lowest of the three subjects, on a very thin evidence base.

    Here is what happened. Neal Kingston and Brooke Nash reviewed more than 300 studies that appeared to address formative assessment in grades K–12. Their abstract states plainly that the commonly claimed effect of about 0.70, or 0.40 to 0.70, “is not supported by the existing research base.” Many studies had severely flawed designs yielding uninterpretable results. Only 13 provided enough information to calculate an effect size at all, producing 42 independent estimates. The median observed effect was 0.25; the weighted mean under a random-effects model was 0.20. Their moderator analysis estimated 0.32 for English language arts, 0.17 for mathematics and 0.09 for science.

    Then the argument got better rather than worse. Derek Briggs, Maria Araceli Ruiz-Primo, Erin Furtak, Lorrie Shepard and Yue Yin published a commentary in the same journal challenging the analysis on four grounds: that the keyword search was not validated and could not be fully replicated, that the inclusion criteria were applied inconsistently — they name two studies that met the criteria and were excluded and one that was wrongly included — that effect sizes computed without pretest data diverge substantially from adjusted ones, and that the analysis never examined whether outcome measures close to the taught curriculum inflated results differently across subjects.

    So the responsible reading is not “formative assessment barely works in science.” It is that 13 usable studies out of 300 is not an evidence base, and the subject-level split sits on a fraction of those 13. We treat contested evidence as contested on this site, and this is as contested as school research gets.

    Which leaves you with a practical standard instead of a statistical one: use a check because it makes student thinking visible to you in time to act on it. That is a claim you can verify in your own room by Friday, and it does not depend on anyone’s meta-analysis.

    Why Science Is Different From Reading and Writing

    Because the wrong ideas students bring in are coherent, useful to them, and survive being taught the right answer. A student who thinks heavier objects fall faster is not missing information; they have a working theory built from a decade of watching things fall, and it predicts most of what they have seen. Telling them the correct rule does not remove the theory. It adds a second one they use on tests.

    This is why the science version of “check for understanding” has to go after the model. A thumbs-up, a right answer on a plug-in-the-formula problem, or a confident nod all leave the old theory completely intact. Our broader piece on checking for understanding makes the case against compliance signals generally; in science the gap between the signal and the understanding is just wider.

    The second difference is the three-dimensional structure described above. A check that only asks students to recall a core idea is assessing one third of what the standards ask for and none of the practice. The strategies below are chosen because most of them put a practice — arguing from evidence, analysing data, constructing an explanation — into a five-minute container.

    Nine Formative Assessment Strategies That Fit Inside One Science Period

    Every one of these is readable in a planning period and none of them needs to be graded. Pick two and run them until they are automatic rather than trying all nine in a week.

    Numbered graphic listing nine formative assessment strategies for science: misconception probe, prediction before data, claim evidence reasoning exit slip, card sort, graph read, one-criterion notebook check, confidence rating, error analysis, and student-written question
    Nine checks, each short enough to run inside one period.

    1. The misconception probe. A short forced choice among several plausible student ideas, followed by “explain your thinking.” NSTA has published these for years as the Uncovering Student Ideas series by Page Keeley, and the teacher notes that come with them summarise the research behind each misconception. You can write your own in ten minutes once you know the common wrong answers in your unit. The choices are the hook; the explanations are the data.

    2. Prediction before data. Before the lab or the demo runs, every student writes down what will happen and why. Thirty seconds. The “why” is the whole point — a wrong prediction with sound reasoning is a different student than a right prediction with no reasoning, and only one of them needs reteaching. It also stops the quiet rewrite where students adjust their memory of what they expected once they see the result.

    3. The claim-evidence-reasoning exit slip. One claim, one piece of evidence from today’s data, one sentence of reasoning. Ten minutes at the end of class gives you a whole-class picture of who can connect data to a conclusion. More on what to look for below.

    4. Card sort. Twelve items to sort into examples and non-examples of a concept — physical and chemical change, or inherited and acquired traits. Sorting takes four minutes. The assessment is the argument over the three hard cards, and you should be circulating with a notebook while it happens.

    5. The graph read. Hand them an unfamiliar graph from the same system and ask one question: what does the slope mean here? Students who have learned a procedure answer the shape; students who understand the science answer the quantity. This is the fastest way to separate the two.

    6. One-criterion notebook check. Walk the room and check every notebook against exactly one thing — units, or the controlled variable, or whether the axis is labelled. A full notebook review does not scale and so it does not happen. A single-criterion pass takes six minutes and actually happens.

    7. Confidence rating. Answer the question, then rate how sure you are. The quadrant that matters is confident-and-wrong, because those students will not ask for help and will not revise. Unsure-and-right is a different problem and needs reassurance rather than reteaching.

    8. Error analysis. Give them a flawed explanation and ask them to find the fault. Catching a bad inference is cognitively harder than producing a tidy one, and it tells you whether a student can evaluate reasoning or only generate it. Write the flawed version yourself from the errors you saw last year.

    9. The student-written question. Ask each student to write a test question on today’s objective. What they think is worth testing tells you exactly what they think the lesson was about, which is frequently not what you thought it was about.

    What If You Teach 150 Students?

    Then you read a sample, not a set. Nobody reads 150 exit slips in a planning period, and pretending otherwise is how a good strategy dies in week three.

    Take one class’s worth — thirty slips — and sort them into three piles as you go: has it, partly has it, does not have it. Do not write on them. Count the piles, read four or five from the middle pile properly, and that is your instructional decision made in eight minutes. If the sampled class is wildly different from what you saw while circulating in the others, sample a second class before you change anything.

    The sample is for the decision. The individual feedback is a separate job and does not have to happen on every check — which is the trade most teachers get backwards, giving thin comments to everyone instead of a real decision to themselves.

    How Do You Check Reasoning and Not Just the Answer?

    Use claim, evidence and reasoning as three separate things to look at, and spend your attention on the third one. Katherine McNeill and Joseph Krajcik, writing for NSTA Press on assessing middle school students’ written scientific explanations, are direct about the asymmetry: the claim is the easiest component for students to construct.

    Three-card graphic breaking down the claim, evidence and reasoning framework and what a teacher should check in each part, with a fourth row on giving specific feedback
    Reasoning is the part that tells you whether they understand the science.

    Their framework splits the work. The claim is a statement that answers the question. The evidence is scientific data supporting it, and they give you two criteria for judging it: appropriateness, meaning the data is actually relevant to the problem, and sufficiency, meaning students use more than one piece rather than resting on a single data point. The reasoning is the justification for why that evidence supports that claim, and it usually requires applying a scientific principle — which is also what tells students what counts as evidence in the first place.

    They report that students often struggle to justify their claims appropriately, which is the finding with the most practical consequence here. If you mark a CER response by checking whether the claim is right, you will grade a lot of students as proficient who cannot explain why anything follows from anything.

    One caution the framework does not raise and a science teacher has to. A written explanation is a literacy task sitting inside a science check, and a student who understands the chemistry but cannot yet produce a paragraph in English will score as not understanding the chemistry. That is a measurement error, not a finding. Sentence stems fix most of it — “My claim is… The evidence that supports this is… This matters because…” — and for students on language or writing accommodations, take the reasoning verbally or as a labelled diagram. You are assessing whether they can justify a claim, not whether they can type it.

    On feedback, their guidance is specific rather than encouraging: identify the particular strength, identify the particular weakness, suggest an improvement, and ask a question that pushes on the thinking. “Good evidence — explain more” is not feedback. “Your evidence is relevant but it is one trial; what would a second trial have to show for your claim to hold?” is.

    Where Science Formative Assessment Goes Wrong

    Four failure modes, and three of them are about what happens after the data arrives.

    You collect and do not act. This is the big one. A probe you read on Saturday and never mention again is a worksheet. If you are not willing to change Monday, do not run it on Friday.

    You reteach by repeating. If a dozen explanations contain the same wrong idea, you have found a shared model, and volume does not displace a model. Find the case their theory cannot explain and build ten minutes around that instead.

    You grade it. Covered above and worth repeating, because it is the most common way a good probe gets ruined. Record completion if you must record something.

    Say that part out loud to the room, and be ready to say it to a parent. Teenagers are not stupid about ungraded work; left unexplained, “this does not count” reads as “this does not matter,” and the effort drops accordingly. The version that works is the honest one: this is not graded because I need to know what you actually think, and if it counted you would write what you think I want. A parent asking why work in the gradebook is marked complete rather than scored gets the same sentence. It is a better answer than most grading policies can give.

    The other half of the dignity question is what you do with a wrong answer once you have it. Patterns go on the board; names do not. The whole arrangement depends on students believing that telling you what they really think is safe, and one wrong explanation read aloud with an author attached ends that for the year.

    You run too many. Nine strategies in one article is a menu, not a schedule. Two strategies you run every week beat nine you run once, both for your sanity and because students get fluent in a format and stop spending their effort decoding the task. That is the same argument as the one for stable classroom routines, applied to assessment.

    What to Do Next

    Pick two. One that runs before instruction — the misconception probe or the written prediction — and one that runs after, which for most science rooms should be the CER exit slip. Run them for three weeks before you judge them, because the first week measures how well students understand the format rather than the content.

    Then write down what you changed. If after three weeks you cannot name a lesson you taught differently because of what a check told you, the problem is not the strategy. It is that the data is arriving somewhere that does not feed a decision, and that is fixable in a way a 0.09 effect size is not.

    One note for anyone reading this with a department rather than a classroom in mind. Eight of these nine checks run on paper and none of them needs a device, a subscription or a consumable, which matters in a building where the lab budget and the technology cart are not evenly distributed. What they do need is the thing the National Research Council flagged: the skill to design and interpret them. That is a department-level job. A shared bank of probes for the three units everyone teaches, built once and reused, is worth considerably more than nine teachers each inventing their own in September.

    The sibling guides for other subjects are built the same way: formative assessment in reading and in writing, and the printable strategy guide collects the cross-subject versions in one free download.

    Ready to build the whole unit? Our guide to project based learning science for grades 6–12 has 25 projects, the randomized evidence with its caveats, and the safety and standards questions that shut science projects down.

    Need tomorrow’s check already written? Our sister site has free science bell ringers for the start of class and science exit tickets for the last five minutes, both built for grades 6–12.

    Frequently Asked Questions

    What are formative assessment strategies in science?

    They are the short, low-stakes checks a science teacher runs during a lesson or unit to find out what students actually think before the summative assessment does it for them. In science specifically they have to surface the student’s model of how something works — not just whether they got the answer — because a student can produce a correct result from a wrong mental model and nobody notices until the transfer question.

    Is formative assessment proven to work in science?

    Less than you have been told. Kingston and Nash’s meta-analysis found a weighted mean effect size of 0.20 across subjects and an estimated 0.09 in science — the lowest of the three subject areas they examined — from only 13 studies that were methodologically usable out of more than 300 reviewed. A published commentary then challenged that estimate on several grounds. The honest summary is that the research base is too thin to give you a number in either direction.

    How is science formative assessment different from reading or writing?

    Two things. First, science misconceptions are durable — students arrive with working theories about force, heat, inheritance and seasons that instruction often fails to displace, so a check has to go after the model and not the vocabulary. Second, the Next Generation Science Standards ask for three dimensions at once: a disciplinary core idea, a science practice and a crosscutting concept. A check that only tests recall is not assessing what you are teaching.

    How long should a formative check take?

    Five to ten minutes, and the reading of it should take less than that. If a strategy costs you twenty minutes of class and an evening of marking, it will not survive October, which means it is not a strategy — it is a one-off. The one-criterion notebook check exists precisely because a full notebook review does not scale and a single-criterion pass does.

    Do I have to grade formative assessments?

    No, and grading them usually ruins them. The moment a probe counts, students answer what they think you want rather than what they believe, and the data you wanted disappears. Record completion if your gradebook needs something. Keep the content ungraded.

    What is a misconception probe?

    A short question — often a forced choice between several plausible student ideas — followed by “explain your thinking.” NSTA publishes a long-running series of them under the title Uncovering Student Ideas, written by Page Keeley, with teacher notes that summarise the research on each misconception. The choice is only the hook. The explanation is the assessment.

    What do I do when half the class gets it wrong?

    Reteach, but not by repeating. If the same wrong idea shows up in a dozen explanations you have found a shared model, and saying the correct version louder does not displace a model — confronting it with a case it cannot explain does. Pick the piece of evidence their idea gets wrong and build the next ten minutes around that.

    Can I use these strategies without lab equipment?

    Most of them, yes. The misconception probe, card sort, graph read, error analysis and student-written question all run on paper. Prediction before data needs a demonstration rather than a full lab, and a single front-of-room demo works. The claim-evidence-reasoning exit slip needs data, which can be a data set you hand out rather than one the class collected.

    Sources

    1. Kingston, Neal, and Brooke Nash. “Formative Assessment: A Meta-Analysis and a Call for Research.” Educational Measurement: Issues and Practice, vol. 30, no. 4, 2011, pp. 28–37. More than 300 K–12 studies reviewed; only 13 allowed effect-size calculation, yielding 42 independent effect sizes. Median 0.25; random-effects weighted mean 0.20. Moderator estimates: ELA 0.32, mathematics 0.17, science 0.09. Cited from the published abstract via the ERIC record; the full article sits behind a publisher paywall and was not read in full. https://eric.ed.gov/?id=EJ951173
    2. Briggs, Derek C., Maria Araceli Ruiz-Primo, Erin Furtak, Lorrie Shepard, and Yue Yin. “Meta-Analytic Methodology and Inferences About the Efficacy of Formative Assessment.” Educational Measurement: Issues and Practice, 2012. Commentary challenging Kingston and Nash on four grounds: unvalidated and non-replicable keyword search; inconsistently applied inclusion criteria, naming Andrade et al. (2008) and Bonner (2009) as wrongly excluded and one study as wrongly included; divergence between effect sizes computed with and without pretest data; and unexamined effects of curriculum-proximal outcome measures. A commentary, not an independent meta-analysis — it argues the estimate is unreliable, not that a different number is correct. https://www.colorado.edu/education/sites/default/files/attached-files/EMIP_Commentary_FINAL_082012.pdf
    3. National Research Council. Developing Assessments for the Next Generation Science Standards. National Academies Press, 2014. Places classroom assessment at the centre of instruction; distinguishes formative assessment (guiding instructional decisions) from summative (assigning grades); states that three-dimensional assessment tasks require multiple components reflecting the connected use of science practices, crosscutting concepts and disciplinary core ideas, and that such tasks are challenging to design, implement and interpret. https://nap.nationalacademies.org/read/18409/chapter/2
    4. McNeill, Katherine L., and Joseph S. Krajcik. “Assessing middle school students’ content knowledge and reasoning through written scientific explanations.” National Science Teachers Association Press. Defines the claim-evidence-reasoning framework; identifies the claim as the easiest component for students to construct, sets appropriateness and sufficiency as the two criteria for evidence, and describes reasoning as the justification that applies a scientific principle. Reports that students often have difficulty appropriately justifying their claims, and recommends explicit, specific feedback over general comments. A book chapter written for practitioners, not a peer-reviewed empirical report; the version read is the authors’ accepted manuscript and carries no publication year on its face. https://websites.umich.edu/~krajcik/McNeill&Krajcik_NSTA.pdf
    5. “Uncovering Student Ideas Probes.” National Science Teaching Association. Describes the probe series by Page Keeley as questions designed to reveal what all students are thinking and to uncover initial ideas and misconceptions about core concepts, with teacher notes containing research summaries and instructional suggestions. A publisher’s description of a commercial series, cited for what a probe is rather than as evidence of effect. https://www.nsta.org/uncovering-student-ideas-probes

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • Presentation Rubric: How to Grade a Student Presentation Without Grading Confidence

    Presentation Rubric: How to Grade a Student Presentation Without Grading Confidence

    By Clay Shumate

    A presentation rubric is a scoring guide that splits a student presentation into separate criteria and describes what each level of performance looks like on each one. A good one scores the claim, the evidence, the organization, the audience work and the answers to questions. A bad one scores how comfortable the student looked. That difference is the entire article.

    Most presentation rubrics you can download in thirty seconds have a row called “poise” or “confidence” or “enthusiasm.” I understand why — those are what you notice from the back of the room. They are also what you did not teach, cannot coach in a week, and should not be putting in a gradebook.

    Key Takeaways

    • Score five things: the claim, the evidence, the organization, the adaptation to the audience, and the answers to unscripted questions. Weight the claim heaviest.
    • Confidence is not a criterion. Neither is eye contact on its own. Both measure temperament and cultural habit more than anything you taught. Delivery still matters — it belongs inside audience adaptation, where it describes a choice the student made rather than a personality they have.
    • Rubrics improve scoring reliability, but only under conditions. A review of 75 studies found the gains come from rubrics that are analytic and topic-specific and paired with exemplars or rater training — not from having a rubric at all.
    • Visual aids are the least reliable row on any presentation form. In an ETS study, trained raters agreed exactly on visual aids only 40 percent of the time. Score whether the visual carries information, and nothing else.
    • Your own severity drifts across a week of presentations. That has been measured on seventh graders, and it drifted at the individual level, not the group level. Which means it is your problem to control, not the rubric’s.

    What Should a Presentation Rubric Measure?

    It should measure the five things a student can actually get better at: the accuracy of what they claimed, the quality of what they used to support it, whether a listener could follow the order, whether the talk was built for the people in the room, and whether the student could answer a question they did not write.

    Everything else on a typical form is either a proxy for one of those five or it is personality.

    Those five also map onto what most state speaking-and-listening standards ask for at the secondary level: present findings and supporting evidence clearly and logically, organize the information so a listener can follow the line of reasoning, make strategic use of a visual, and adapt speech to the task and audience. Check your own state’s wording before you borrow mine — but if your rubric has a row that matches no standard in your course of study, that row is worth questioning.

    The rubric is only as good as whether you can explain a row to a fifteen-year-old who disagrees with their score, so here is the one-line version of each. Claim: does the presentation say something, and is it right? A tour of a topic is not a claim. Evidence: is each point supported by a source named specifically enough to check? “A study said” is not sourcing. Organization: could a listener follow the sequence with the slides turned off? Audience adaptation: did the student define unfamiliar terms, pace it for listening, and answer the question this room would actually have? Response to questions: the one row that cannot be faked the night before, and the one most rubrics leave off entirely.

    Five-row graphic listing what a presentation rubric should measure: claim and content accuracy, evidence and sourcing, organization, audience adaptation, and response to questions
    Five criteria. The claim carries the most weight.

    On whether rubrics help at all: Anders Jonsson and Gunilla Svingby reviewed 75 studies of scoring rubrics for Educational Research Review and concluded that reliable scoring of performance assessments can be improved by rubrics — especially if those rubrics are analytic, topic-specific, and supported by exemplars or rater training. That qualifier is the useful part. They also found that a rubric does not by itself make the judgement valid. Handing out a form is not the intervention; the design and the training are.

    If you want a professionally built reference point, the National Communication Association’s Competent Speaker Speech Evaluation Form breaks public speaking into eight competencies — among them narrowing the topic for the audience and occasion, providing supporting material, using an organizational pattern, and using physical behaviors that support the verbal message — each scored unsatisfactory, satisfactory or excellent. Notice that even the delivery competencies are written as things the speaker does, not states they are in. One honest caveat: the 1990 development report states plainly that reliability and validity testing was still planned rather than completed, so treat the form as a well-reasoned professional instrument rather than a validated one.

    I am not going to re-argue analytic versus holistic scoring here, because that question already has a home on this site. The Socratic seminar rubric article works through that choice and the mechanics of scoring a room full of students at once, and the answer there applies to presentations too. A third option skips the filled-in levels entirely and describes only the proficient target, leaving the rest of each row blank for feedback — what that format buys and what it does not is worth reading before rebuilding a form around it.

    Why Most Presentation Rubrics Grade the Wrong Thing

    Because the categories that are easiest to see from the back of the room — confidence, enthusiasm, eye contact, polish — are the categories least connected to anything you taught.

    Take the oral presentation rubric published by the National Council of Teachers of English through ReadWriteThink — probably the most-printed presentation rubric in American schools. It is a reasonable, free form covering grades 3 through 12 on a 1–4 scale across three categories: Delivery, Content/Organization, and Enthusiasm/Audience Awareness. I am naming it as the common case, not to dunk on it. But Delivery is defined there as eye contact and voice inflection, and Enthusiasm is scored as something a student either has or does not.

    For a third grader learning to speak above a whisper, those categories do real work. For a sixteen-year-old, scoring enthusiasm means putting a number on whether a teenager performed excitement about a topic you assigned. I have never heard anyone defend that score to a parent well.

    Four-row graphic listing what to keep off a presentation rubric: confidence, eye contact as its own line item, slide design polish, and group participation points
    Four categories that look fair on a rubric and are not.

    There is a fairness problem underneath this, and it is not a small one. This next part is my own judgement as a classroom teacher rather than a research finding, and I want it labeled that way. A rubric row for confidence transfers points from students with anxiety to students without it. A row for eye contact scores a cultural norm about looking adults in the face. A row for slide polish scores whose family owns a laptop and which students have had reason to learn design software. None of those rows are measuring the standard. All of them are measuring something a student brought in the door.

    The right move is not to stop caring about delivery. It is to put delivery inside audience adaptation, defined as choices the student made for the listener, which is coachable. “You spoke to the slides for two minutes without looking up, so the room stopped following” is feedback. “You seemed nervous” is an observation about a person.

    The Presentation Rubric

    Here is the full form. Five criteria, four levels, and the claim row weighted double. Copy it, cut a row if you must, and change the point values to fit your gradebook. It is free and there is no form to fill out.

    Criterion4 — Exceeds3 — Meets2 — Approaching1 — Not yet
    Claim and accuracy
    (×2)
    States a clear, specific, defensible claim and sustains it. No factual errors.States a clear claim and mostly sustains it. Minor errors that do not undercut the point.Topic is clear but the claim is vague, or an error undercuts part of the argument.No identifiable claim, or central content is inaccurate.
    Evidence and sourcingEvery significant point is supported. Sources named specifically enough to check. Weighs a counterpoint.Main points supported. Sources named.Some points supported; sourcing vague (“a study,” “online”).Assertions without support, or sources that do not exist as described.
    OrganizationA listener could follow the sequence with the visuals off. Opening frames it; close lands it.Clear beginning, middle and end. Order makes sense.Follows the slide order rather than an argument. Close trails off.No discernible structure.
    Audience adaptationUnfamiliar terms defined, pace set for listening, addresses the question this audience would have. Visual carries information the talk does not.Mostly built for the listener. Visual supports the talk.Delivered at the slides or the notes. Visual duplicates what is being said.Read verbatim; audience not accounted for.
    Response to questionsAnswers directly, distinguishes what they know from what they are inferring, says “I don’t know” where true.Answers the question asked, with reasonable accuracy.Answers adjacent to the question, or repeats a line from the talk.Cannot engage a question about their own material.
    A presentation rubric for grades 6–12. Claim is weighted double; delivery lives inside audience adaptation.

    One more thing worth doing, and it costs a class period’s first ten minutes: hand students the draft and let them argue one row’s descriptors. Not the criteria — those come from the standard and they are not up for a vote — but the wording of what a 3 looks like. Students who have argued over a descriptor stop treating the number as something that happened to them.

    Three notes on using it. Give it out before students plan, not before they present — a rubric handed out the morning of is a grading instrument, not a teaching one. Show them a 4 and a 2; Jonsson and Svingby’s review is explicit that exemplars are part of what makes rubric scoring reliable, and students calibrate off one example faster than off four paragraphs of descriptors. And say out loud that confidence is not on the rubric. The kids who most need to hear it are the ones who would otherwise spend their prep week worrying about the wrong thing.

    What If Your School Already Adopted a Rubric?

    Then use it, and use the rows above as your feedback rather than your grade.

    Plenty of schools have a common presentation rubric attached to a capstone, a portfolio or a graduate profile, and a teacher quietly swapping in their own form breaks the one thing that instrument is for — comparability across classrooms. Score the adopted rubric as written. Then give the student the five rows above in the comment, because that is where the coachable information is. If the adopted form scores confidence, that is a department or district conversation and it is worth having with the evidence in this article in hand. It is not worth having by going rogue on your own section.

    Visual Aids Are the Least Reliable Row You Will Score

    If you and another teacher score the same presentation, the row you are most likely to disagree about is the visual aid.

    An Educational Testing Service study had trained raters score video of oral presentations and reported intraclass correlations for each dimension. Most held up well — word choice at .93, vocal expression at .91, nonverbal behavior at .89, organization at .73. Visual aids came in at an ICC of .78 but only 40 percent exact agreement, the weakest exact-agreement figure on the form. The same study found that when raters worked from transcripts alone, scoring word choice collapsed to an ICC of .27 and persuasion to .39.

    Two caveats before anyone quotes that at a department meeting. The participants were college students and the raters were trained, not a teacher scoring period four. And trained raters disagreeing sets a ceiling, not a floor — your agreement with a colleague is unlikely to be better.

    Three-card research graphic: rubrics improve reliable scoring when analytic and paired with exemplars or rater training, visual aids reached only 40 percent exact agreement in an ETS study, and individual raters drifted more severe or lenient while scoring seventh-grade presentations over four days
    Three findings that change how you write and use a presentation rubric.

    The practical conclusion is to stop asking the visual-aid row to do too much. Do not score design. Ask one question: does the visual carry information the talk does not? A chart the student made from their own data is a 4. A slide of the paragraph they are reading aloud is a 1, no matter how clean the template. That question is answerable and it is the same question whether the student had Canva or a sheet of poster board.

    Your Scoring Drifts, and Somebody Measured It

    Over four days of presentations, individual raters got measurably more severe or more lenient — and the drift was personal, not shared.

    Aslıhan Erman Aslanoğlu and Mehmet Şata looked at exactly this in a secondary setting, which is rare and worth knowing about. Twenty-eight raters scored eight oral presentations by seventh graders across four days, two per day. Using many-facet Rasch measurement, they found that some raters tended toward more severity or more leniency over time, but found no significant rater drift at the group level. The shifts had no common pattern.

    That is a small study and it is one grade level. But the finding matches what every teacher who has graded thirty presentations in two days already suspects, and the group-level result is the interesting half: you cannot correct for drift by assuming everyone drifts the same way. Four things help, and none of them cost money.

    1. Score during the presentation, not after the period. Scores written from memory are scores written against whoever presented most recently.
    2. Keep two anchor examples in front of you — a known 4 and a known 2, from last year or from the exemplars you showed the class.
    3. Randomize the order, and tell students it is random. Volunteers-first means your strongest students set your scale on day one.
    4. Re-score the first two presentations at the end — before you enter anything. If those scores move, your scale moved, and the fix is to re-score the set rather than to split the difference. Do this while the grades are still in your notes; changing a posted grade is a conversation with a family that you do not need to have.

    How to Get Thirty Presentations Through in One Period

    Cap the talk at four minutes, take one question, and finish the rubric in the sixty seconds while the next student sets up.

    Thirty four-minute presentations will not fit in one period, so make the call deliberately: run them across two days, run them in parallel small groups with you rotating, or shorten the format. A four-minute talk with a required claim and two pieces of evidence tests more than a twelve-minute one, because the student has to decide what matters.

    The question row only works if a question gets asked, and in a real room it will not happen on its own. Assign it. Two students per presenter, named in advance, each owing one question that is not “how long did this take you.” If nobody bites, you ask — but then you are the only questioner for thirty presentations, and by the twentieth your questions get thin.

    Do not write comments live. Score the five rows, write one sentence, and move. The sentence should name the single highest-value change: “Your evidence was strong but the claim never got stated as a sentence — write it on a card next time and open with it.” If you try to write paragraphs you will either stop watching or stop scoring, and both are worse than a short comment.

    If the goal is to get more students talking more often rather than to grade a formal performance, a presentation is a heavy tool for the job. A gallery walk puts every student’s work in front of an audience in one period, and most of the quicker moves on the list of formative assessment strategies get you the same information about who understands the material without anyone standing up, and a Socratic seminar gets them accountable for speaking without the stage. Use the rubric above when the presentation itself is the standard being assessed — not as the default whenever you want students to speak.

    Grading Group Presentations Without Hiding the Silent Student

    Score each speaker on their own segment against the same five criteria, then score one shared row for whether the parts added up to a single argument.

    A single group score is how a student who said eleven words gets the same grade as the student who built the thing, and it makes the grade indefensible the moment a parent asks what their kid specifically did. The fix is not peer-rated effort percentages, which mostly measure social standing. It is to require that every member owns a segment, and to score the segment.

    The individual-versus-group grading problem is worked through in more depth in the project based learning rubric, including how to keep collaboration points from covering for weak content. The principle is the same here: teamwork can be a criterion, but it cannot be a criterion that rescues a grade.

    What About the Student Who Cannot Stand Up There?

    Change the size of the audience, not the criteria.

    Some students genuinely cannot present to thirty peers, and a few have a documented plan that says so. Those plans are not optional — follow them and talk to the case manager rather than improvising.

    And do not build an informal workaround for a student you merely suspect is struggling. If a student seems unable to do this, the route is the counselor or the case manager, not a side deal at your desk — a private arrangement that changes how a student is assessed is a modification nobody has reviewed, and it can quietly cost that student the evaluation that would have gotten them real support.

    For everyone else, notice what the five criteria actually require. A claim, evidence, structure, adaptation to an audience, and answering a question. None of that requires a stage. A student can present to you and two classmates at a back table, or record it, or present to a group of four, and still be scored on the identical form. If you take the recording route, check your district’s policy first and keep the file out of shared drives — a video of a minor is not a normal piece of student work, and a parent is entitled to ask where it went. What you must not do is quietly drop the claim row or the questions row because the setting got smaller. That is lowering the standard and calling it an accommodation, and students can tell.

    And the fixed version of the rubric helps here more than any kindness would. When confidence is not scored, the student who shakes through four minutes and nails the claim, the evidence and the questions gets the grade they earned.

    What to Do Next

    Tell families what the rubric does and does not score before the first grade is entered. A one-line note that reads “this presentation is graded on the claim, the evidence, the structure, how it was built for the audience, and the answers to questions — not on confidence or slide design” prevents most of the emails you would otherwise get, and it reaches the parent of the anxious kid before that kid spends a week dreading the wrong thing.

    Take the table above, cut it to the rows you can defend, and hand it out with the assignment rather than the week of. Pull a 4 and a 2 to show the class. Then, the first time you use it, re-score your first two presentations at the end of the set and see whether your scale moved. That one check will tell you more about your grading than the rubric will.

    If you only change one thing today, delete the confidence row.

    Frequently Asked Questions

    What should a presentation rubric include?

    Five criteria, each scored separately: the accuracy and clarity of the student’s claim, the quality and sourcing of their evidence, the organization of the talk, how well it was adapted to the audience in the room, and how the student handled a question they did not script. Weight the claim heaviest, because it is the only row that measures the subject you teach. Everything else on a typical form is either a proxy for one of those five or it is personality.

    Should a presentation rubric grade confidence or eye contact?

    No. Confidence is a trait rather than a skill you taught, and scoring it moves points from students with anxiety to students without it. Eye contact as its own line scores a cultural habit about looking adults in the face. Delivery still matters — put it inside an audience-adaptation row, where it describes a choice the student made for the listener and can therefore be coached. “You spoke to the slides, so the room stopped following” is feedback. “You seemed nervous” is not.

    How do you grade a group presentation fairly?

    Require that every member owns a segment, then score each student on their own segment against the same five criteria, and add one shared row for whether the parts added up to a single argument. A single group score lets the student who said eleven words earn the same grade as the student who built the project, and it is indefensible the first time a parent asks what their child specifically did. Avoid peer-rated effort percentages — they mostly measure social standing.

    How do you score thirty presentations in one class period?

    You do not. Thirty four-minute talks is two hours of speaking before a single question. Make the call deliberately: run presentations across two days, run parallel small groups with you rotating, or shorten the format. Score the rows during the presentation rather than from memory afterwards, write one sentence naming the single highest-value change, and move. Scores written at the end of the period are scores written against whoever presented most recently.

    Do rubrics actually make grading more consistent?

    They help, but not automatically. Jonsson and Svingby’s review of 75 studies found that reliable scoring of performance assessments is improved by rubrics — especially rubrics that are analytic, topic-specific, and paired with exemplars or rater training. They also found that having a rubric does not by itself make the judgement valid. The design and the training are the intervention, not the handout.

    Does my scoring really change over several days of presentations?

    There is evidence that it does. Aslanoğlu and Şata had 28 raters score eight oral presentations by seventh graders across four days and found that individual raters tended to get more severe or more lenient over time — with no significant drift at the group level, meaning the shifts had no shared pattern. Practical defences: keep a known 4 and a known 2 in front of you, randomize the presentation order, and re-score your first two before you enter any grades.

    What if a student has severe anxiety about presenting?

    Change the size of the audience, not the criteria. A claim, evidence, structure, audience adaptation and answering a question do not require a stage — a student can present to you and two classmates, to a group of four, or on video and be scored on the identical form. What you must not do is quietly drop the claim row or the questions row because the setting got smaller; students can tell. If a student has a documented plan, follow it and talk to the case manager rather than improvising a private arrangement nobody has reviewed.

    Is this presentation rubric free to use?

    Yes. Copy it, cut rows, change the point values, put your school’s name on it. There is no email form, no download gate and nothing to buy. Everything on ElevateTheNorm.com is free.

    Sources

    1. Jonsson, A., & Svingby, G. (2007). The Use of Scoring Rubrics: Reliability, Validity and Educational Consequences. Educational Research Review, 2(2), 130–144. A review of 75 studies; reliable scoring is improved by rubrics that are analytic, topic-specific, and complemented with exemplars and/or rater training, and a rubric alone does not ensure a valid judgement. https://eric.ed.gov/?id=EJ796733
    2. Erman Aslanoğlu, A., & Şata, M. (2023). Examining the Rater Drift in the Assessment of Presentation Skills in Secondary School Context. Journal of Measurement and Evaluation in Education and Psychology. 28 raters scored 8 oral presentations by 7th-grade students across four days; individual-level drift toward severity or leniency was found, with no significant drift at the group level. Small sample, one grade level. https://dergipark.org.tr/en/pub/epod/issue/76343/1213969
    3. A Proof-of-Concept Study on Scoring Oral Presentation Videos in Higher Education. (2019). ETS Research Report Series. Trained raters scoring full videos reached ICCs of .73–1.00 across dimensions; visual aids had the weakest exact agreement at 40 percent, and transcript-only scoring dropped word choice to ICC .27. Participants were college students and raters were trained — not a secondary-classroom sample. https://files.eric.ed.gov/fulltext/EJ1238389.pdf
    4. Morreale, S. P., et al. (1990). “The Competent Speaker”: Development of a Communication-Competency Based Speech Evaluation Form and Manual. National Communication Association / ERIC ED325901. Eight competencies, each scored unsatisfactory, satisfactory or excellent. The report states that reliability and validity testing was planned rather than completed at publication, so it is cited here as a professionally developed instrument, not a validated one. https://files.eric.ed.gov/fulltext/ED325901.pdf
    5. National Council of Teachers of English. Oral Presentation Rubric. ReadWriteThink. A free grades 3–12 form scoring Delivery, Content/Organization and Enthusiasm/Audience Awareness on a 1–4 scale. Cited as the widely used common case this article argues with, not as supporting evidence. https://www.readwritethink.org/classroom-resources/printouts/oral-presentation-rubric

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • One Pager Assignment: How to Make It Think Instead of Decorate

    One Pager Assignment: How to Make It Think Instead of Decorate

    By Clay Shumate

    A one pager assignment asks a student to put their thinking about a text, a topic or a unit onto a single page, combining writing and drawing. Done well, it is a compact analysis task with a visual element. Done badly, it is a craft project with a quotation glued to it — and the difference is almost entirely in what you require and what you grade.

    The format came out of AVID and has spread well beyond it. The spread is the problem: most of what teachers see online is the finished art, which tells you nothing about whether the student understood anything.

    Key Takeaways

    • Require elements, not an aesthetic. A claim written as a sentence, two cited pieces of evidence, a drawing that carries an idea, a labelled connection, a lingering question, and one line of so-what. If you can hit every requirement and still not have thought, the requirements are wrong.
    • The research supports the ingredients, not the poster. Drawing to learn improved outcomes in 26 of 28 comparisons at a median effect size of 0.40; summarizing in 26 of 30 at a median of 0.50. Both come with a condition: students need to be taught how.
    • Do not justify a one-pager with “visual learners.” The meshing hypothesis has been examined and found wanting. Justify it because drawing and summarizing are generative work — which is a better reason anyway.
    • Grade the thinking. Four criteria: accuracy of the claim, quality of the evidence, whether the image carries an idea, and completeness. Artistic skill appears nowhere.
    • A template is not a crutch. It is the thing that lets the non-artist start, and the research on drawing says explicitly that pretraining and structure improve the effect rather than diluting it.

    What Is a One Pager Assignment?

    It is a single page on which a student represents their understanding of something, in words and images, using a required set of elements. That is the whole definition. The page is the constraint; the elements are the assignment.

    AVID developed the strategy and it is now used well outside AVID classrooms. In practice you will see it most in English and social studies — after a novel, a chapter, a documentary, a unit — but nothing about the format is subject-specific. A one-pager works anywhere a student needs to compress something large into something defensible.

    What it is not is a poster. A poster communicates to an audience. A one-pager is evidence of thinking, submitted to you. Those two things want different rules, and most of the trouble with one-pagers starts when a teacher writes poster rules and grades them as analysis.

    Three-row research graphic: drawing to learn supported with 26 of 28 comparisons positive and median effect size 0.40, summarizing supported with 26 of 30 positive and median 0.50 but requiring training, and visual learners not supported
    Two of the three claims people make about one-pagers hold up. The third does not.

    Does the Research Support One-Pagers?

    Not directly — there is no body of research on “one-pagers” as such. What there is, and it is good, is evidence on the two things a one-pager makes students do: draw and summarize.

    Fiorella and Mayer’s 2015 review in Educational Psychology Review is the best single place to see it. They assessed eight generative learning strategies against the experimental record. Drawing produced positive effects in 26 of 28 comparisons, with a median effect size of d = 0.40, across elementary, high school and college students — one of their strongest examples was ninth graders working on chemistry comprehension. Summarizing produced positive effects in 26 of 30 comparisons, median d = 0.50.

    So far, so encouraging. Here is the part that changes how you run the assignment. For drawing, the authors are explicit that the effect improves when students receive explicit pretraining in how to draw, detailed guidance about which elements to include, partial illustrations to work from, or a chance to compare their drawing with the author’s. The thing they warn against is “extraneous cognitive load caused by the mechanics of drawing” — a student spending their working memory on composition is not spending it on the content. For summarizing, the training studies they review gave middle schoolers roughly six hours of instruction over five weeks before the summaries got good.

    Read that honestly and it says something uncomfortable: handing out a blank page and saying “be creative” is the version of this assignment the research does not support.

    There is a second line of evidence worth knowing. Fernandes, Wammes and Meade’s 2018 review in Current Directions in Psychological Science describes a reliable “drawing effect” on memory — drawing a word at encoding beats writing it, repeatedly, and the benefit holds for older adults and even appeared in a small group of patients with dementia. Two details matter for a classroom. The benefit arrived with as little as four seconds of drawing per item, and it applies “regardless of one’s artistic talent.” The caveat is the population: these were adults in memory experiments with word lists, not teenagers writing about a novel. It tells you the mechanism is real. It does not tell you the size of the effect on a literary analysis.

    What About “Visual Learners”?

    Leave it out of your rationale. It is the most common justification given for one-pagers and it is the weakest one available.

    Pashler, McDaniel, Rohrer and Bjork examined the evidence for the meshing hypothesis — the idea that matching instruction to a student’s preferred style improves learning — in Psychological Science in the Public Interest in 2008. Their finding was blunt: they found “virtually no evidence for the interaction pattern” that would be required to validate the educational application, and concluded that “there is no adequate evidence base to justify incorporating learning-styles assessments into general educational practice.”

    This is not a reason to stop assigning one-pagers. It is a reason to describe them accurately to students, to parents and to an administrator who asks. The honest sentence is: drawing and summarizing are generative activities with a decent evidence base, so I am asking every student to do both. That is stronger ground than a learning style, and it does not sort children into categories the research does not support.

    Six-row graphic listing required elements of a one pager assignment: a claim written as a sentence, two pieces of cited evidence, one drawn image that carries meaning, a labeled connection, a question the student still has, and one sentence of so-what
    Six required elements. Every one of them is thinking, not decoration.

    What Should a One-Pager Actually Require?

    Six elements, each of which is a thinking move rather than a design choice. The test for any element you add: could a student satisfy it without understanding the material? If yes, cut it.

    A claim, written as a sentence. Not a title, not a theme word. An arguable statement the student could defend out loud. This single requirement does more work than the other five combined, because it is the one that cannot be faked with a border.

    Two pieces of cited evidence. Quoted or paraphrased, with a page number, a line, or a source. “Cited” is doing real work here — if a student cannot point to where it came from, it is not evidence yet.

    One drawn image that carries meaning. The drawing has to do something the words are not doing: show a relationship, a sequence, a contrast, a scale. A decorative border is not an element. A badly drawn diagram that makes a comparison visible is.

    A labelled connection. An arrow, a line or a bracket with words on it, showing how two things on the page relate. This is the cheapest way to force synthesis, and it is the element students most often skip.

    A question the student still has. In their own voice. It is the most honest window you will get into what they actually understood, and it costs them thirty seconds. If you want a wider version of this, it is the same instinct behind asking a student to judge their own work before you do.

    One sentence of so-what. Why this matters outside the unit. Short, and theirs. Most students will write something flat the first time. They get better at it the fourth time, which is an argument for assigning one-pagers more than once a year.

    Numbered four-criteria grading graphic for a one pager assignment: accuracy of the claim, quality of the evidence, whether the image carries an idea, and completeness and legibility rather than neatness
    Four criteria, none of which is artistic skill.

    How Do You Grade a One-Pager Without Grading Art?

    Put artistic skill nowhere on the rubric, and tell students that before they start. Four criteria will carry it. The same problem turns up on any student artefact that repeats every unit; our piece on grading an interactive notebook without grading the craft works through that version.

    Accuracy of the claim is the heaviest weight. Is it defensible against the text or the evidence? This has nothing to do with how the page looks. Quality of the evidence comes second: cited, relevant, and actually supporting the claim rather than being the first quotation the student found. Does the image think? — scored on whether the drawing carries an idea, never on execution. A labelled stick figure can score full marks and should. Completeness and legibility is the last and the smallest: all six elements present, and a reader can follow it. Legibility is not neatness. A page can be messy and perfectly readable.

    Two things to resist. Do not add a “creativity” or “visual appeal” category — it is unscoreable, it rewards students who already had art supplies at home, and it is the single fastest way to turn this into an equity problem. And do not give points for colour. If you want the general version of this argument, the same reasoning applies to any rubric where presentation can hide thin understanding.

    Three practical conditions follow from that. The assignment has to be completable with a pencil — if markers are required, you have built a supply test, so keep whatever you have in a tub on the counter and do the work in class rather than at home. Score the “question you still have” element present-or-absent, never on quality, or students will stop telling you the truth in the one place they were being honest. And tell families the rubric excludes artistic skill before the first grade goes in the book, because a parent looking at a drawing with a C on it will reasonably assume you graded the drawing. If you grade on a 4-point scale, this 1-4 grading scale chart shows the percentage behind each level.

    Alternatives need to be available without a formal plan: typed and printed elements pasted down, cut images instead of drawn ones, or the whole thing explained to you verbally while you score the same four criteria. A student with a fine-motor difficulty, a visual impairment, or a hand in a cast should not have to disclose anything to get a different route.

    On grading time — this is the objection every teacher with 150 students will have, and it is correct. Score in one pass, in bands rather than points, and write a comment only on the claim. If the claim is wrong, nothing downstream of it is worth your ink. Four criteria scored 1–4 with one sentence on the first of them runs about ninety seconds a page.

    One more move that costs four minutes and is worth more than the rubric. Walk the room while they work and ask three or four students to defend the claim on their page out loud — not to justify the picture, just the sentence. I do a version of this constantly: circulating, pulling a student aside, and making them explain the decision they made rather than telling them whether it was right. You find the gap between a page that looks finished and a page that is understood in about twenty seconds, and you find it while there is still time to fix it. That is the same thing any good in-the-moment check is for.

    What About the Student Who Says They Cannot Draw?

    Give them a template and say the sentence out loud: nobody is being graded on drawing. Then mean it, because teenagers will test whether you meant it.

    Betsy Potash, writing at Cult of Pedagogy, identifies the problem exactly: the one-pagers that circulate online are made by artistic students, and everybody else concludes the assignment is not for them. Her fix is a template — a page with designated spaces for each required element — which she describes as a creative constraint that paradoxically frees students up, because the paralysis is usually about placement rather than content. Students who want a blank page can flip the template over and use the back.

    That is a practitioner’s recommendation rather than a research finding, and it should be read as one. But it points the same direction the research does: Fiorella and Mayer found that structure, partial illustrations and guidance about which elements to include increase the benefit of drawing rather than watering it down. The template is not a concession. It is the scaffold the evidence asks for.

    Where One-Pagers Go Wrong

    Four failure modes, and three of them are the teacher’s.

    The first is the blank page with no requirements, which produces decoration from the artists and panic from everyone else. The second is grading the aesthetic, which teaches students that the assignment was about markers all along. The third is assigning it once, at the end of a unit, as a summative grade — the first one a student makes is always the worst one, and the research on summarizing says the skill takes weeks of instruction to develop. Run the first as practice. The fourth is the student version: filling every element with something technically present and entirely hollow. The claim sentence catches most of this, and the four-minute verbal check catches the rest.

    How Do You Launch It the First Time?

    Spend twenty minutes before anyone touches a page. This is the pretraining the drawing research keeps pointing at, and skipping it is why most first attempts disappoint.

    Show two finished examples — one strong, one weak — and have the class score both against your four criteria before they know which is which. Make the weak one visually attractive and analytically thin, because that is the trap. Then model the hardest element: write a claim sentence in front of them, out loud, and revise it once. Then let them start, with the template on the desk and the requirements on the board.

    If you want the pages to do a second job, hang them and run a structured walk around the room where students read each other’s claims and leave one question each. The reading is worth more than the display, and it makes the “question you still have” element feel like it has a purpose beyond the gradebook. Make the display opt-out without explanation — some students are genuinely uncomfortable having a drawing on the wall, and nothing about the learning requires it to be public.

    Afterwards, do not just file them. Read the question column across the whole class in one sitting; it is the cheapest reteach list you will ever assemble, and it was generated by students who thought nobody was grading it.

    What to Do Next

    Take whatever you were going to assign as a written response this month and convert it — same content, six required elements, four grading criteria, a template on every desk, and twenty minutes of launch before the first page gets made. Run it as practice rather than as a test grade.

    Then do it again inside the same semester. Almost everything useful about one-pagers shows up on the second and third attempt, once students have stopped worrying about the layout and started arguing on paper. If you need the in-between measurement, a two-minute check sorted by where it falls in a lesson will tell you more, sooner, than waiting for the pages to come in.

    Frequently Asked Questions

    What is a one pager assignment?

    A single page on which a student represents their understanding of a text, topic or unit using both words and images, against a required set of elements. The strategy came out of AVID and is now used well beyond it, most commonly in English and social studies. The page is the constraint; the required elements are the actual assignment. It is not a poster — a poster communicates to an audience, while a one-pager is evidence of thinking submitted to a teacher, and the two want different rules.

    Is there research showing one-pagers work?

    Not on one-pagers as a named format. There is good evidence on the two things a one-pager makes students do. In Fiorella and Mayer’s review of generative learning strategies, drawing produced positive effects in 26 of 28 comparisons at a median effect size of d = 0.40, and summarizing in 26 of 30 at a median of d = 0.50, across elementary, high school and college students. Both come with the same condition: the effect improves when students are explicitly taught how, and the summarizing training studies gave middle schoolers roughly six hours of instruction over five weeks.

    Should I say one-pagers are good for visual learners?

    No. Pashler, McDaniel, Rohrer and Bjork examined the meshing hypothesis — that matching instruction to a preferred style improves learning — and found “virtually no evidence” for the interaction pattern it requires, concluding there is “no adequate evidence base” for using learning-styles assessments in general practice. Use the better justification instead: drawing and summarizing are generative activities with real support, so every student does both. That reasoning survives a conversation with an administrator, and it does not sort students into categories the evidence does not back.

    How do I grade a one-pager fairly?

    On four criteria, none of which is artistic skill: accuracy of the claim, quality of the cited evidence, whether the drawn image carries an idea rather than decorates, and completeness and legibility. Weight the claim heaviest. Do not add a creativity or visual-appeal category — it is unscoreable and it rewards students who own art supplies. Tell families the rubric excludes drawing before the first grade is entered, because a parent seeing a low mark on a page with a picture on it will assume you graded the picture.

    What do I do about students who say they cannot draw?

    Give them a template with a designated space for each element and say out loud that nobody is graded on drawing — then hold to it, because they will test whether you meant it. A labelled stick figure that makes a comparison visible should score full marks. Alternatives need to be available without a formal plan: typed elements pasted down, cut images rather than drawn ones, or explaining the page to you verbally while you score the same four criteria.

    Does a template make the assignment too restrictive?

    The evidence points the other way. Fiorella and Mayer found that structure, partial illustrations and guidance about which elements to include increase the benefit of drawing rather than diluting it, and the risk they name is extraneous cognitive load from the mechanics of drawing — which is exactly what a blank page creates. The template removes the paralysis about placement so the student can spend their attention on the content. Students who want the open page can use the back of it.

    Should a one-pager be a test grade?

    Not the first one. The first attempt is always the worst attempt, and the research on summarizing says the skill takes weeks of instruction to develop, so a summative grade on a first try is measuring unfamiliarity with the format. Run the first as practice, assign a second inside the same semester, and grade that one. Almost everything useful about one-pagers appears on the second and third attempt, once students have stopped worrying about layout and started arguing on paper.

    Does handwriting the page help more than typing it?

    There is no good evidence for that, and it is worth knowing because the claim gets repeated a lot. Urry and colleagues ran a direct replication of the well-known longhand-versus-laptop study with 142 undergraduates and found a negligible effect in the opposite direction on conceptual questions, and a mini meta-analysis across eight studies found no significant difference in quiz performance. Assign a one-pager because drawing and summarizing are generative, not because the student held a pen.

    Sources

    1. Fiorella, Logan, and Richard E. Mayer. “Eight Ways to Promote Generative Learning.” Educational Psychology Review, vol. 27, 2015, pp. 1–47. Drawing: positive effects in 26 of 28 comparisons, median d = 0.40, across elementary, high school and college students; effect increases with explicit pretraining in how to draw, guidance on elements, partial illustrations or comparison with author-provided drawings, and the stated risk is extraneous cognitive load from the mechanics of drawing. Summarizing: 26 of 30 comparisons positive, median d = 0.50; middle-school training studies required roughly six hours of instruction over five weeks. https://doi.org/10.1007/s10648-015-9348-9
    2. Fernandes, Myra A., Jeffrey D. Wammes, and Melissa E. Meade. “The Surprisingly Powerful Influence of Drawing on Memory.” Current Directions in Psychological Science, vol. 27, no. 5, 2018, pp. 302–308. Reports a reliable recall advantage for drawn over written words, benefits arriving with as little as four seconds of drawing per item, and the authors’ statement that the benefit applies “regardless of one’s artistic talent.” Populations are younger adults, older adults and a group of 13 patients in long-term care — not secondary students, and the materials are word lists rather than academic content. Cited for mechanism, not for an effect size on classroom work. https://doi.org/10.1177/0963721418755385
    3. Pashler, Harold, Mark McDaniel, Doug Rohrer, and Robert Bjork. “Learning Styles: Concepts and Evidence.” Psychological Science in the Public Interest, vol. 9, no. 3, 2008, pp. 105–119. The authors found “virtually no evidence for the interaction pattern” required to validate learning-styles instruction and concluded “there is no adequate evidence base to justify incorporating learning-styles assessments into general educational practice.” https://doi.org/10.1111/j.1539-6053.2009.01038.x
    4. Urry, Heather L., et al. “Don’t Ditch the Laptop Just Yet: A Direct Replication of Mueller and Oppenheimer’s (2014) Study 1 Plus Mini Meta-Analyses Across Similar Studies.” Psychological Science, vol. 32, no. 10, 2021, pp. 1479–1492. Direct replication, N = 142 undergraduates. Conceptual-question performance showed a negligible effect in the opposite direction to the original (Hedges’s g = −0.13, 95% CI [−0.45, 0.20]), significantly different from the original result. A mini meta-analysis of eight studies found g = 0.04, 95% CI [−0.13, 0.20], not significant. The authors conclude results “do not support the idea that longhand note taking improves immediate learning via better encoding of information.” Cited as contrary evidence: do not justify handwritten work on the grounds that writing by hand beats typing. https://doi.org/10.1177/0956797620965541
    5. Potash, Betsy. “A Simple Trick for Success with One-Pagers.” Cult of Pedagogy, 26 May 2019 (updated 2026). Credits AVID with developing the strategy; describes the template as a creative constraint that helps non-artistic students start, and recommends simple rubric categories such as textual analysis, required elements and thoroughness. Cited as practitioner recommendation, not as research evidence. https://www.cultofpedagogy.com/one-pagers/

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • Test Corrections: How to Make Them Teach Instead of Hand Back Points

    Test Corrections: How to Make Them Teach Instead of Hand Back Points

    By Clay Shumate · Updated October 24, 2026

    Test corrections are a structured second pass in which a student identifies why an answer was wrong and produces a correct one. The research on learning from errors is strong and supports the practice. The research on what students actually do with error feedback is much less flattering, and it is the part that determines whether your version works.

    Done well, a test correction is the most efficient reteaching you will ever get: the student already knows what they missed. Done badly, it is twenty minutes of copying answers off a neighbor’s paper for half the points back.

    Key Takeaways

    • Making errors and then correcting them beats avoiding errors. A review in the Annual Review of Psychology concluded that error avoidance “appears to be the rule in American classrooms” and that errorful learning followed by corrective feedback produces better retention.
    • Feedback is not optional — it is the whole mechanism. In one lab study, errors were corrected on a later test about 70% of the time with feedback and roughly 4% of the time without it.
    • Your most confident wrong answers are the ones most likely to get fixed. That is the hypercorrection effect, and it means the student who argues with you about question 14 is the student most likely to remember the right answer in May.
    • When corrections are optional, most students skip them. Across 20,058 assessments from 2,826 students in grades 5–11, students opened the detailed error feedback in only 44% of cases — and the students with the lowest scores were the least likely to look.
    • A reflection form on its own does nothing. A randomized study of “exam wrappers” found no effect on exam scores, final grades, or measured metacognition. The structure has to force the thinking, not just ask for it.

    Free Download · PDF

    The Test Correction Sheet and Policy Card (2 pages)

    Page 1 is the student sheet — three blocks of the four-box correction, with the reasoning box that makes copying an answer useless. Page 2 is a policy card to fill in and staple to the first test of the term, plus a sorting sheet for reading a class set in five minutes.

    Download the free PDF

    Free. No email address required. Designed for grades 6–12. Browse every printable in Your Free Library.

    Two-column graphic on test corrections evidence: 70 percent versus 4 percent correction rates with and without feedback and roughly 82 percent for high-confidence errors on one side, a 44 percent feedback open rate and a median of one error reviewed on the other
    The case for corrections and the complication, side by side.

    What Are Test Corrections?

    A test correction is a required second pass over a returned assessment in which the student states what the right answer is and why their first one was wrong. That second clause is the whole practice. Without it you have a transcription exercise.

    Two versions run in American schools under the same name, and they produce opposite results.

    Version one: hand back the test, let students fix wrong answers, give half credit back. Most look at the answer key, write the right letter, hand it in. Nobody learns anything, the grade goes up, and the next test looks exactly like the last one.

    Version two: the student has to name the error — not the answer, the error. What did I think was true that was not? That version is slower, harder to grade, and is the one with research behind it.

    If you only take one thing from this article: the credit is not the intervention. The credit is the thing that gets students to do the intervention. Confusing the two is how a good practice turns into grade inflation with extra steps.

    Does the Research Actually Support Learning From Mistakes?

    Yes, and more strongly than most teachers assume. Janet Metcalfe’s review “Learning from Errors,” published in the Annual Review of Psychology in 2017, surveys the laboratory evidence and reaches a blunt conclusion: error avoidance “appears to be the rule in American classrooms,” and it is the wrong rule. Errorful learning followed by corrective feedback produces better retention than carefully steering students around mistakes.

    Her recommendation is that teachers should “allow and even encourage students to commit and correct errors while they are in low-stakes learning situations rather than to assiduously avoid errors at all costs,” precisely because the goal is performance later, when the stakes are high.

    The crucial qualifier is the phrase followed by corrective feedback. Metcalfe is explicit that the feedback, “including analysis of the reasoning leading up to the mistake,” is what makes the error productive. A wrong answer left wrong is just a wrong answer. Same logic that makes formative assessment worth the class time: information is only worth collecting if something happens next.

    Why Your Most Confident Students Gain the Most

    Students correct the errors they were most sure about more reliably than the ones they guessed at. That is the hypercorrection effect, and it is counterintuitive enough that it is worth stating twice.

    Janet Metcalfe and Bridgid Finn tested it directly in a 2011 paper in the Journal of Experimental Psychology: Learning, Memory, and Cognition. Participants answered general-knowledge questions, rated their confidence, received corrective feedback on their errors, and were tested again later. Errors held with high confidence were corrected on the final test around 82% of the time. Overall recall after feedback was about 70%. Without feedback, correction rates fell to roughly 4%.

    Two things follow. First, the gap between 70% and 4% is the clearest number in this entire literature, and it says the thing teachers most need to hear: returning a graded test without a correction process is close to doing nothing. Second, the student who comes up after class and argues that question 14 was unfair is not being difficult. High confidence plus a wrong answer is the configuration most likely to produce durable learning. Argue back, with evidence.

    Stated honestly: these were college undergraduates, in a lab, answering trivia. Samples ran from 25 to 45 people per experiment. The mechanism is about confidence and attention rather than age, so it is reasonable to expect it to transfer to a fifteen-year-old and a unit test. The exact percentages are not yours to quote as classroom results.

    Four numbered boxes of a test correction form: what I put, why I put it, the right answer and where it came from, and what would make me miss this again
    Box 2 is the one that makes copying an answer off a neighbour useless.

    So Why Don’t Test Corrections Always Work?

    Because when looking at the feedback is optional, most students don’t — and the ones who need it most are the least likely to. This is the finding that should change what you build, and it comes from the largest secondary-school sample in this article.

    Ulrich Maier and Christian Klotz analyzed log data from a digital formative assessment system used in German schools, published in Contemporary Educational Psychology in 2025. The scale is unusual: 2,826 students across 182 secondary classrooms in grades 5 through 11, covering 20,058 formative assessment cases collected between 2020 and 2024. After each assessment the system offered a detailed error feedback page explaining what went wrong.

    What students did with it:

    • They opened the error feedback page in only 44% of cases. In the majority of assessments, nobody looked at the explanation at all.
    • Among those who opened it, the median number of error items reviewed was one. The average was 1.74, roughly half of the errors available to them.
    • Prior knowledge was by far the strongest predictor of whether a student looked. Higher scorers were dramatically more likely to seek feedback. The authors state the paradox plainly: low-achieving students tend to ignore elaborated feedback, despite being the group most likely to benefit from it.
    • Students who thought they had passed were more likely to open the feedback than students who thought they had failed — even when the confident ones had actually failed.

    That is a digital platform rather than a paper test, and German secondary schools rather than American ones, so the exact rates will not be yours. But the shape of it will be. Optional reflection is self-selecting, and it selects for the students who already understand the material. Any correction process you design has to assume the student who most needs it will skip it unless the structure does not permit skipping.

    The Reflection Sheet Is Not the Intervention

    A form that asks students to reflect does not, on its own, produce reflection. There is a direct test of this.

    Raechel Soicher and Regan Gurung studied “exam wrappers” — short reflection sheets students complete after a returned exam about how they studied and what they will change. Published in Psychology Learning & Teaching in 2017, the study randomly assigned 86 students to three conditions: real exam wrappers with metacognitive instruction, sham wrappers with no instruction, or a control group. There were no improvements in exam performance, final grades, or measured metacognitive ability. Scores on the Metacognitive Awareness Inventory rose over the semester in every condition, including the control, which is a reminder of what happens to an uncontrolled before-and-after comparison.

    The authors suggest the effect may require use across multiple courses rather than one. Fair. But the practical lesson for a secondary teacher is immediate: if your test correction process is a sheet of reflection prompts stapled to the front, you have bought the packaging and not the thing. The questions that produce learning are about the specific item — this question, this error, this misconception — not about study habits in general.

    A Four-Part Test Correction That Produces Thinking

    Each wrong answer gets four boxes. Not three, and not six. This is the smallest structure that makes transcription impossible.

    BoxWhat the student writesWhy it is there
    1. What I putThe original answer, copied over.Makes them look at the error rather than skipping straight to the key. Takes five seconds.
    2. Why I put it“I thought the Senate confirmed treaties on its own.” A sentence naming the belief, not “I didn’t study.”This is the box that does the work. It is also the one students resist, because it requires admitting what they believed.
    3. The right answer, and the evidenceThe correct answer plus where it came from — page, slide, notes, a worked line.Forces a source. A student who cannot find it does not understand it yet, and now you both know.
    4. What would make me miss this again“Any question that uses ‘ratify.’” A trigger, not a resolution.Transfer. The point is the next question of this type, not this question.

    Box 2 is the one people cut when they are short on time, and it is the only one that distinguishes this from an answer key. “Careless mistake” is not an acceptable entry in box 2 more than once per test; if a student writes it three times, the pattern is the finding and it is worth a two-minute conversation.

    For a free-response or math item, box 3 becomes “the first line where it went wrong,” which is more useful than reworking the whole problem and usually faster.

    List of five ways test corrections go wrong, including becoming a points economy and only failing students completing them, each with a fix
    Each of these turns a correction into paperwork.

    How Much Credit Should Test Corrections Be Worth?

    Enough that students do them, little enough that the grade still means something. Half the missed points back is the common answer and it is defensible. So is a flat cap — corrections can move a score up to a 79 and no further. Credit for corrections holds up for the same reason most extra credit arrangements do not — the points still measure the learning the grade claims to report.

    Three things to settle before you announce it:

    1. Check your district’s grading policy first. Many boards have adopted language about reassessment, grade replacement, and minimum scores. A teacher-invented points-back scheme that conflicts with board policy is a problem that has nothing to do with pedagogy, and you will lose that argument in March rather than in September.
    2. Write it down and hand it out. Parents are reasonable about a policy that exists and furious about one that appears to change by student. “Up to half the missed points, corrections due within one week, box 2 must be completed” fits on an index card.
    3. Decide whether a correction can raise an A. The honest answer is yes. A student who got a 97 has three errors worth understanding, and excluding the strongest students from the only reteaching structure in the class is backwards. If credit is the only incentive you have, offer the strongest students the thing they actually want: the correction counts, and it gets read.

    A note on what this does to your gradebook. If corrections replace scores rather than adding points, you are most of the way to standards-based grading already, and you should read the honest case against it before you commit, because the implementation problems there are real.

    Test Corrections or a Retake — Which One Do You Need?

    A correction analyzes the test the student already took. A retake is a new assessment of the same material. They answer different questions and they are not substitutes.

    If the retake half is the part you are still arguing about, the evidence on whether students should be allowed to retake tests — including where it cuts against the practice — is worked through separately, with a policy you can hand to an administrator.

    • Use corrections when the errors are scattered. A 71 made of eleven different small mistakes is a diagnosis problem. Corrections surface the pattern.
    • Use a retake when the student did not know the material. A 44 does not have a pattern to find. It has a hole, and corrections on a test you did not understand is just copying.
    • Use both, in order, when the stakes are real. Corrections first, as the price of admission to the retake. It is a reasonable gate and it stops the retake from being a free second roll of the dice.

    Sequencing them that way also solves a fairness problem administrators raise: if a retake is available to anyone who asks, the students who ask are the students whose families know to ask. Requiring the correction makes the path the same for everybody.

    What About the Student Who Just Copies the Right Answer?

    Assume this will happen and build so it does not pay. Box 2 is most of the defence — you cannot copy someone else’s misconception off their paper, because it was not your misconception.

    Beyond that the answers are ordinary. Do corrections in class, not as homework, at least the first few times — so you see the thinking happen and so students without a quiet place to work are not disadvantaged. Spend two of those minutes circulating and asking one student per row to explain box 2 out loud.

    The Grading Burden, Honestly

    If you teach 150 students and read four boxes on every missed item, you will stop doing this by October. Anyone who tells you otherwise has not graded a stack of 150.

    Three ways to make it survivable:

    • Cap it. Students correct their five worst items, not all of them. Five is plenty for a pattern and it bounds your reading.
    • Score box 2 only, and score it pass/fail. A complete, specific sentence gets the credit. A blank or “I didn’t study” does not. You can do that at a glance.
    • Read them as a class set, not as individual papers. Sort the box-2 responses into piles by misconception. Five minutes of sorting tells you what to reteach tomorrow, which is the only reason to collect them at all.

    That last one is also the answer to a coach’s question: the evidence of learning is not the corrected test. It is what you teach differently on the next item of that type, and whether the same misconception shows up again on the unit after this one. If it does, the corrections were decoration. The habit of asking that question after an assessment is the same one behind any serious approach to checking for understanding.

    What Does This Look Like From a Student’s Seat?

    It looks like being asked to write down, on paper, in your own handwriting, the thing you were wrong about. That is harder than it sounds at fifteen, and it is worth naming out loud the first time you assign it.

    Say the thing directly: this is not a punishment, everyone does it including the people who scored highest, and nobody is reading box 2 to laugh at you. Then make that true. A correction process where the teacher reads a student’s misconception back to them in front of the class is a process that will be filled in with nothing real by Thanksgiving.

    Students should also be able to argue. If a student’s box 2 says “I put B because the question says ‘primarily,’ and both A and B are true,” they may be right and the item may be bad. Give points back when they are. A correction process in which the teacher is never wrong is one the students will correctly read as theatre.

    And handle accommodations through the plan, not through the policy. A student with extended time or a scribe on the test has the same entitlement on the correction. A student with a processing or writing accommodation can answer box 2 out loud to you in ninety seconds; the requirement is the thinking, not the handwriting. The plan governs, and designing the correction so that honoring it looks ordinary is easier than making an exception every time.

    Where Test Corrections Go Wrong

    • They become a points economy. Students negotiate credit instead of analyzing errors. Fix: cap the recovery and never bargain over it mid-conversation.
    • Only failing students do them. Which teaches that corrections are what happens when you mess up, rather than what everyone does with a returned test. Fix: everyone corrects, including the 97.
    • They are assigned as homework on day one. The students least likely to complete unsupervised work are the students whose errors you most need to see — the same self-selection Maier and Klotz measured.
    • Nobody reads box 2. If the teacher never responds to the reasoning, students learn within two tests that the reasoning is ceremonial.
    • They substitute for reteaching. A correction is the student’s work. If eleven students missed the same item, that is your work.

    What to Do Next

    Take the next test you are about to hand back and do three things. Require corrections from every student, not just the ones who failed. Make box 2 — why I put it — mandatory for credit, and refuse “careless mistake” as a repeat answer. Then sort the box-2 responses into piles before you plan tomorrow, because that pile is the most honest data you will get all unit.

    The deeper argument here is not about points. It is that a test handed back and filed away teaches a teenager that a wrong answer is a verdict, and a test corrected teaches them it is information. That is the same case the site makes about learning from mistakes everywhere else, and it is the reason a correction belongs in the student’s hands rather than the gradebook — which is also the argument for student self-assessment as a routine rather than an event.

    Corrections only work if the student can check an answer against something, which is why I would not run them on a test without a key. The midterm library at Mid-Terms.org has 200 free printable exams for grades 6–12, every one with an answer key, across Social Studies, ELA, Math and Science.

    Test corrections are retrieval practice after the fact. Running the same mechanism before the test is cheaper, and the study skills research explains why a few minutes of closed-notes recall beats an hour of rereading.

    Before you go: grab the free The Test Correction Sheet and Policy Card (2 pages) (PDF) — ElevateTheNorm.com branded, printable, no email required.

    Frequently Asked Questions

    What are test corrections?

    Test corrections are a required second pass over a returned test in which the student states the right answer and explains why their first answer was wrong. Naming the error, not just the answer, is the whole practice. Without that explanation, corrections become a transcription exercise that raises the grade without reteaching anything.

    Should test corrections be optional?

    No. When reviewing errors is optional, most students skip it, and the lowest scorers skip it most. In one study of 20,058 assessments from 2,826 students in grades 5 to 11, students opened the detailed error feedback in only 44 percent of cases. A correction process has to be built so the students who need it cannot quietly opt out.

    Do test corrections actually work?

    The underlying mechanism is well supported. Metcalfe’s 2017 review in the Annual Review of Psychology concludes that errorful learning followed by corrective feedback beats error avoidance, and in one lab study errors were corrected on a later test about 70% of the time with feedback against roughly 4% without it. The complication is compliance. In a study of 20,058 assessments by 2,826 students in grades 5–11, the error feedback page was opened in only 44% of cases. Corrections work. Optional corrections mostly do not.

    How much credit should test corrections be worth?

    Enough that students do them and little enough that the grade still means something. Half the missed points back is the common answer and it is defensible; so is a flat cap that lets corrections raise a score to a 79 and no further. Check your district’s grading and reassessment policy before you announce anything, write the policy down, hand it out, and do not vary it by student.

    What is the difference between test corrections and a retake?

    A correction analyzes the test the student already took. A retake is a new assessment of the same material. Use corrections when the errors are scattered — a 71 made of eleven small mistakes is a diagnosis problem. Use a retake when the student did not know the material, because corrections on a test you did not understand is just copying. When the stakes are real, use both in order and make the completed correction the price of admission to the retake.

    How do I stop students from just copying the right answer?

    Require a box that asks why they put what they put — the belief, not "I didn’t study." You cannot copy somebody else’s misconception off their paper, because it was not your misconception. Beyond that, do the first few rounds in class rather than as homework so you can see the thinking happen, and ask one student per row to explain that box out loud.

    Should students who got an A do test corrections?

    Yes. A student who scored 97 has three errors worth understanding, and excluding your strongest students from the only reteaching structure in the class is backwards. It also fixes a dignity problem: if only failing students correct, corrections become what happens when you mess up rather than what everybody does with a returned test.

    How do I grade test corrections for 150 students?

    Cap it at the five worst items per student, score only the reasoning box and score it pass/fail at a glance, and read the set as a class rather than as individual papers — sort the responses into piles by misconception. Five minutes of sorting tells you what to reteach tomorrow, which is the only real reason to collect them. If you are reading four boxes on every missed item for 150 students, you will stop doing this by October.

    Is there a free test corrections template?

    Yes — the two-page PDF linked on this page. Page 1 is the student sheet with three blocks of the four-box correction. Page 2 is a policy card to fill in and staple to the first test of the term, plus a sorting sheet for reading the set as a class. Free, printable, no email address required.

    What should a student actually write in the "why I put it" box?

    A sentence naming the belief that produced the wrong answer — "I thought the Senate confirmed treaties on its own" rather than "I rushed" or "careless mistake." Careless mistake is acceptable once per test. Written three times it is itself the finding, and worth a two-minute conversation. Students should also be allowed to argue: if the box says the item was ambiguous and they are right, give the points back. A correction process in which the teacher is never wrong is one students will correctly read as theatre.

    Sources

    1. Metcalfe, Janet. “Learning from Errors.” Annual Review of Psychology, vol. 68, 2017, pp. 465–489. Review concluding that error avoidance “appears to be the rule in American classrooms” and that errorful learning followed by corrective feedback is beneficial; that corrective feedback “including analysis of the reasoning leading up to the mistake” is crucial; and recommending that educators allow students to commit and correct errors in low-stakes situations. A review of laboratory evidence, not a classroom trial. https://www.annualreviews.org/content/journals/10.1146/annurev-psych-010416-044022
    2. Metcalfe, Janet, and Bridgid Finn. “People’s Hypercorrection of High-Confidence Errors: Did They Know It All Along?” Journal of Experimental Psychology: Learning, Memory, and Cognition, vol. 37, no. 2, 2011, pp. 437–448. Three experiments, 25–45 participants each. High-confidence errors corrected at roughly 82% on the final test; overall recall with feedback about 70%; correction without feedback roughly 4%. College undergraduates answering general-knowledge questions in a laboratory, not secondary students on a unit test. https://pmc.ncbi.nlm.nih.gov/articles/PMC3079415
    3. Maier, Ulrich, and Christian Klotz. “Students Ignore Their Mistakes: Elaborated Error Feedback Processing in a Digital Learning System.” Contemporary Educational Psychology, vol. 82, 2025, article 102395. Observational log analysis of 20,058 formative assessment cases from 2,826 students across 182 secondary classrooms, grades 5–11, 2020–2024. Error feedback opened in 44% of cases; median one error item reviewed; 51% of available errors reviewed on average; prior knowledge the strongest predictor of feedback seeking. Observational, German secondary schools, a digital grammar application rather than a paper test. https://www.sciencedirect.com/science/article/pii/S0361476X25000608
    4. Soicher, Raechel N., and Regan A. R. Gurung. “Do Exam Wrappers Increase Metacognition and Performance? A Single Course Intervention.” Psychology Learning & Teaching, 2017, pp. 64–73. 86 students randomly assigned to exam wrappers, sham wrappers, or control. No improvement in exam performance, final grades, or Metacognitive Awareness Inventory scores; MAI rose in all conditions including control. University students, single course. https://liberalarts.oregonstate.edu/biblio/do-exam-wrappers-increase-metacognition-and-performance-single-course-intervention
    5. Rice, Bethany S. “How Extra Credit Quizzes and Test Corrections Improve Student Learning While Reducing Stress.” ASEE 127th Annual Conference & Exposition, 2020. Average exam scores rose 5% (2018) and 3% (2019) when corrections were offered; 80% of students participated; survey responses strongly favourable. Cited as a descriptive classroom report, not a controlled study: no comparison group, 31 survey respondents, university engineering technology students. https://peer.asee.org/how-extra-credit-quizzes-and-test-corrections-improve-student-learning-while-reducing-stress.pdf
    6. McDade, Margaret. “Using Test Corrections as a Learning Tool.” Edutopia, George Lucas Educational Foundation. A high school math teacher’s small-group correction routine, with retesting for full credit rather than partial credit on corrections. Cited as practice knowledge: the article reports a teacher’s own method and cites no studies. https://www.edutopia.org/article/test-corrections-high-school-math/

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

Teacher Emergency Toolkit — practical resources, real classroom support. Shop on TPT.Teacher Emergency Toolkit — practical resources, real classroom support. Shop on TPT.