Category: Assessment & Feedback

Checking for understanding, feedback, and assessment that changes what happens next.

  • Socratic Seminar Rubric: A Four-Criterion Version for Grades 6–12

    Socratic Seminar Rubric: A Four-Criterion Version for Grades 6–12

    By Clay Shumate

    A Socratic seminar rubric should score four things: preparation, use of the text, how a student treats other people’s ideas, and what they wrote afterward. It should not score how many times somebody spoke. The full rubric is below, free, on this page, with no email to give — and a printable version at the bottom if you want one.

    It comes with an argument, because a rubric that counts talking turns is worse than no rubric at all — and because the research on rubrics is more qualified than the phrase “research-based rubric” suggests.

    Key Takeaways

    • Four criteria, four levels, and none of them is participation frequency. Counting comments rewards volume and punishes the students who most need the practice.
    • Most of the score comes from writing, not talking. Preparation before and reflection after are visible, gradeable, and fair to a student who spoke twice.
    • Analytic beats holistic on reliability. A review of 75 studies found scoring agreement improves with analytic, topic-specific rubrics plus exemplars or rater training.
    • Rubrics are not automatically valid. The same review is explicit that a rubric improves agreement between scorers without guaranteeing you are measuring the right thing.
    • You cannot facilitate and score thirty students at once. Anyone who says otherwise is describing a checklist, not an assessment.

    Free Download · PDF

    Socratic Seminar Rubric (Four Criteria)

    The same four-criterion rubric printed above, laid out to print and cut, plus the scoring rotation for thirty students and a student self-score half-sheet.

    Download the free PDF

    Free. No email address required. Designed for grades 6–12. Browse every printable in Your Free Library.

    What Should a Socratic Seminar Rubric Measure?

    The things a student controls, that leave evidence, and that you would still care about if the student were quiet. That test eliminates most of what standard seminar rubrics score.

    Four criteria survive it.

    1. Preparation. Did they read it, mark it, and bring a written question? This is visible before anyone speaks and it is the single best predictor of whether the seminar works.
    2. Use of the text. When they did speak or write, did they point at a specific place in the text, or at a general impression?
    3. Treatment of other people’s ideas. Did they build on, question, or directly respond to a classmate — or deliver a prepared statement into the middle of the circle and stop?
    4. Reflection afterward. Can they name what changed in their thinking and whose comment did it? This one is only answerable by a student who was listening, which is why it is the hardest to fake.

    If your gradebook is standards-based, those four map cleanly onto speaking-and-listening standards without inventing a category: preparation and use of the text are evidence standards, treatment of others’ ideas is a collaborative-discussion standard, and the reflection is usually assessable under both. You do not need a “participation” line item, and if the gradebook has one, these are what should feed it.

    One caution on the third criterion, and it is the one I would want a department to talk through before adopting any seminar rubric. Norms about interrupting, turn length, directness and how openly you disagree are not universal — they vary by family, by community, and by what a student has been taught is respectful. A rubric that scores “treatment of others’ ideas” can quietly encode one conversational style as the correct one. Keep the descriptors pointed at what the student did with the idea — responded to it, questioned it, built on it — and away from manner, volume and poise. If a descriptor could be satisfied by a confident student who said nothing of substance, it is scoring style.

    Three of those four produce writing. That is deliberate. A rubric whose evidence is mostly written is a rubric you can actually apply after the period ends, and it is a rubric a student who said very little can still score well on.

    The Socratic Seminar Rubric

    Four criteria, four levels, no participation count. Copy it, cut it, change the language to match your school’s scale. It is free, it is printed in full right here, and there is a printable version at the bottom of this page.

    One framing worth saying to students before you hand it over: the level-one column describes something that happened on one day, not a kind of person. A student who arrived without the text marked is a student who arrived without the text marked. If a descriptor reads to a fourteen-year-old like a verdict on their character, rewrite it — that costs nothing and it changes whether they look at the rubric again.
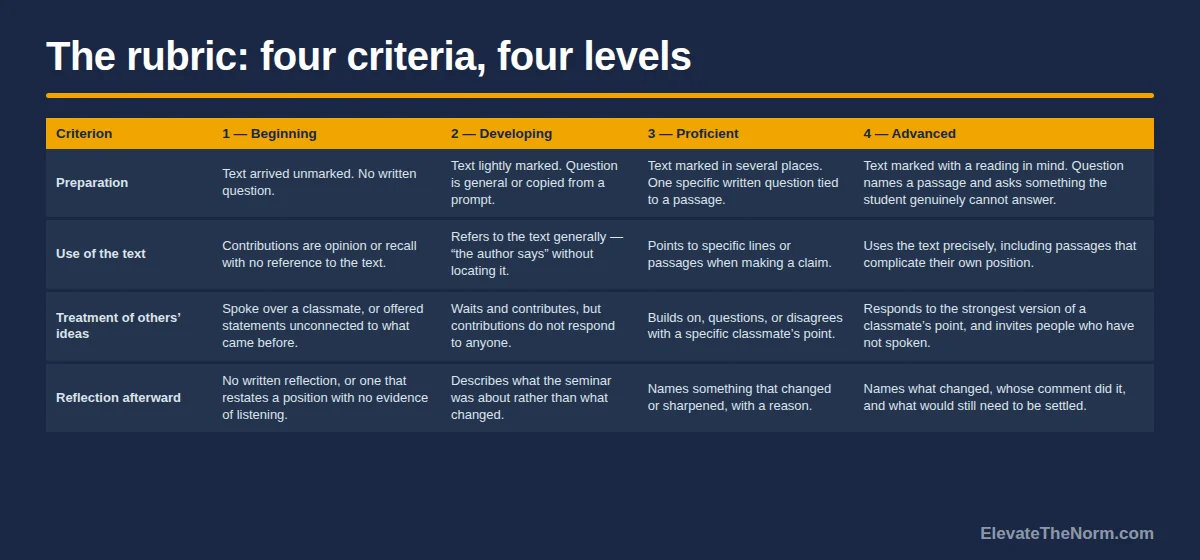
    Four by four Socratic seminar rubric table with criteria for preparation, use of the text, treatment of others' ideas and reflection afterward, each described at beginning, developing, proficient and advanced levels
    The full rubric. The same table is written out below so you can copy it.
    Criterion1 — Beginning2 — Developing3 — Proficient4 — Advanced
    PreparationText arrived unmarked. No written question.Text lightly marked. Question is general or copied from a prompt.Text marked in several places. One specific written question tied to a passage.Text marked with a reading in mind. Question names a passage and asks something the student genuinely cannot answer.
    Use of the textContributions are opinion or recall with no reference to the text.Refers to the text generally — “the author says” without locating it.Points to specific lines or passages when making a claim.Uses the text precisely, including passages that complicate their own position.
    Treatment of others’ ideasSpoke over a classmate, or offered statements unconnected to what came before.Waits and contributes, but contributions do not respond to anyone.Builds on, questions, or disagrees with a specific classmate’s point.Responds to the strongest version of a classmate’s point, and invites people who have not spoken.
    Reflection afterwardNo written reflection, or one that restates a position with no evidence of listening.Describes what the seminar was about rather than what changed.Names something that changed or sharpened, with a reason.Names what changed, whose comment did it, and what would still need to be settled.
    Free to copy, cut and rewrite. No email address. A printable version is linked below.

    Why This Rubric Does Not Count How Often You Spoke

    Because a participation count measures confidence and rewards it, and confidence is not the skill you are teaching. The moment students know comments are scored, you get performances of the right length at the right frequency, and the conversation stops being about the text.
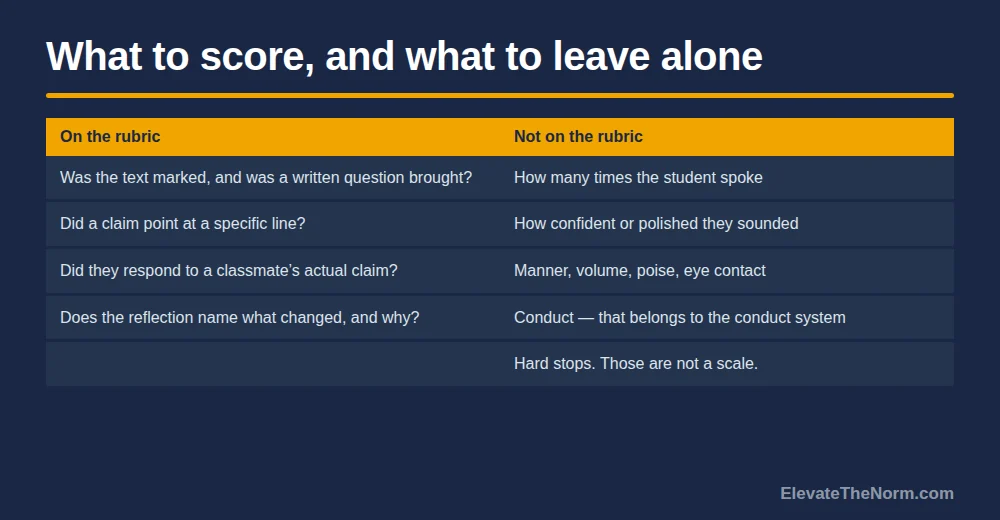
    Two column table contrasting what belongs on a Socratic seminar rubric with what does not, including how many times a student spoke, manner and poise, and conduct
    If a descriptor could be met by a confident student who said nothing of substance, it is scoring style.

    There is a second reason, and it is about who pays. A qualitative study of quiet students — ten undergraduates, so treat it as a description rather than a finding about your seventh period — found that nine of the ten struggled with instructor expectations for verbal participation, and six reported physical reactions when speaking aloud: trembling, blushing, stuttering. One described planning out what they wanted to say before speaking. A frequency count charges those students a fee the loud ones never pay, for a behavior that is not the learning objective.

    Related, and worth checking against your district’s grading policy: criterion three has to stay academic. “Responded to a classmate’s specific claim” is an academic behavior. “Was respectful” is conduct, and in a lot of districts conduct is not permitted inside an academic grade — for good reason. If a student’s behavior in a seminar is a problem, that is the conduct system’s job, handled the way you would handle it on any other day, and not something you fold into a score for a speaking standard.

    This also gives you a clean answer when a parent asks. A quiet student can earn full marks here, because three of the four criteria are about preparation, precision and listening, and none of them requires their child to perform in front of the class. Say that in the same sentence you send the rubric home, before anyone has to ask.

    If your school requires a participation grade, pull it from criteria one and four — both of which are written, both of which are about preparation and listening, and neither of which requires a student to perform. Then say out loud to the class that talking is not scored. The first seminar after they believe you is a different conversation.

    One thing that belongs nowhere on a rubric: the behaviors that are not a continuum. In my room, making fun of how unusual somebody’s name is is a hard stop — not a criterion where a student can earn a 2. A rubric is for things that improve by degrees. Hard stops are a different category, and putting them on a scoring scale quietly suggests there is an acceptable amount.

    Do Rubrics Actually Help?

    They reliably help scoring agreement. Their effect on learning is real, mixed, and badly confounded — and the honest version is more useful than the sales version.

    Jonsson and Svingby reviewed 75 empirical studies on rubrics. Their finding on reliability is clear: scoring “can be enhanced by the use of rubrics, especially if they are analytic, topic-specific, and complemented with exemplars and/or rater training.” Their finding on validity is the one people skip — rubrics do not by themselves make an assessment judgement valid. Two teachers agreeing on a score is not the same as the score measuring the thing you care about.

    Panadero and Jonsson then reviewed 21 studies on using rubrics formatively. Some reported large effects on performance — effect sizes from 0.99 to 1.6 — and others reported little or nothing. The authors are direct about why that range is not as impressive as it looks: “most studies reporting on such improvements have combined the use of rubrics with other instructional interventions.” The rubric usually arrived alongside self-assessment, peer assessment or extended instruction, so the rubric’s own contribution is hard to isolate. They also note that positive effects were more likely in higher education, in interventions lasting several weeks or longer, and when rubrics were paired with metacognitive work.

    What they identify as the mechanism is worth keeping, because it tells you how to use the thing: rubrics work by making expectations transparent, which reduces anxiety, supports feedback, and lets students plan. Students in those studies described using a rubric “much like a recipe or a map.”

    The practical conclusion: hand the rubric out before the seminar, not after. A rubric used as a scoring instrument is a grading tool. A rubric used as a description of what good looks like, given to students in advance, is the version with evidence behind it.

    Analytic or Holistic?

    Analytic, if you want two teachers to agree. That is the clearest single recommendation in the rubric literature, and the rubric above follows it — four separate criteria scored separately rather than one overall impression.

    Jonsson and Svingby list four things that improve scoring agreement, and it is worth reading them as a to-do list rather than a finding: analytic design, topic-specific criteria, exemplars, and rater training. The first two are free and you did them by choosing this rubric. The third costs one seminar — keep two reflections, one strong and one thin, and show students both. Anonymised means actually anonymised — names and identifying details stripped, and the student asked first. A class can usually recognise its own handwriting and its own arguments, and “this is the weak one” is not a thing to do to a student by accident. The fourth matters only if more than one adult is scoring.

    “Topic-specific” is the one worth acting on. A rubric that says “uses evidence effectively” is generic and every scorer fills in their own meaning. Rewriting that row to name what evidence looks like in this text — a line number, a date, a specific claim — takes two minutes and does more for consistency than any amount of descriptor polishing. The same principle runs through the site’s approach to rubrics generally: specific beats elegant.

    How Do You Score Thirty Students in One Period?

    You do not, and the sooner you stop trying the better your seminars get. Facilitating and scoring are two jobs. Doing both means doing the first one badly, and the first one is the one that makes the seminar work.
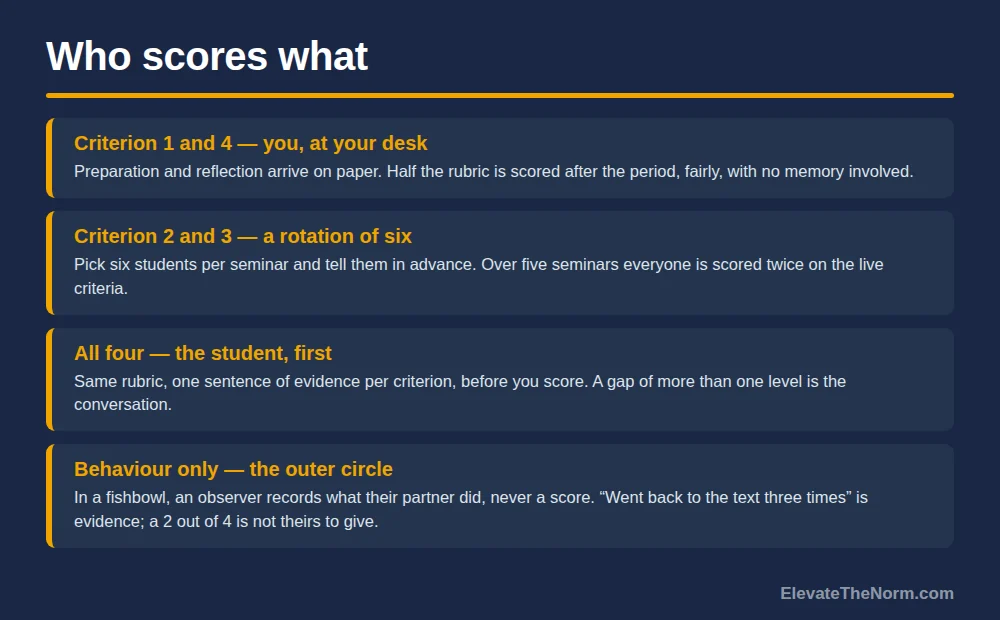
    Four rows describing who scores which rubric criteria: the teacher scores preparation and reflection from paper, a rotating group of six is scored on the live criteria, students self-score first, and outer-circle observers record behaviour only
    Facilitating and scoring are two jobs.

    Three ways out, in order of how much I trust them.

    1. Score the writing, not the room. Criteria one and four are collected on paper. That is half the rubric done at your desk, after school, fairly, with no memory involved.
    2. Score a rotation. Pick six students per seminar for criteria two and three and tell them in advance. Over five seminars everyone gets scored twice on the live criteria. Telling them beforehand is not cheating — it is the transparency the research says is doing the work.
    3. Use the fishbowl. If half the class is in an outer circle already, give each observer one partner and one behavioral thing to record. Their notes are not the grade, but they are evidence you did not have to generate while running the conversation.

    Check one thing before you adopt any of this: if a student has an IEP or 504 plan that addresses oral participation, the live criteria may need to be replaced rather than adapted for that student. Ask the case manager rather than improvising a workaround, and note that this rubric already makes that easy — half the score is written, so substituting the other half costs you less than it would on most discussion rubrics.

    On time, honestly: four criteria for twenty-eight students is about twenty minutes if you are scoring the written half from paper and six students on the live half. It is not nothing. It is roughly the cost of grading a set of exit tickets, and it is the reason the rotation exists.

    What I would not do is score from memory at the end of the period. Twenty minutes after a good seminar, what you remember is who was interesting, and “interesting” correlates with confident far more than it correlates with prepared.

    Who Should Do the Scoring?

    Students first, on the same rubric, before you score anything. This is the change that makes the rubric an instructional tool rather than a grading one, and it costs four minutes.

    Hand out the rubric before the seminar. Afterward, have each student score themselves on all four criteria and write one sentence of evidence for each. Then score them yourself. Where you disagree by more than one level, that is your conversation — and it is a better conversation than any comment you would have written unprompted.

    Two guards on this. The student’s self-score is not the grade; it is information, and the moment it becomes the grade you have taught them to inflate it. And peer scoring should stay behavioral: what a classmate did, not how well they did it. A fifteen-year-old can honestly record “went back to the text three times.” A fifteen-year-old should not be handing another fifteen-year-old a 2 out of 4 on how they treat people’s ideas. This is the same line the site draws around having students judge their own work: the judgement is real, and it does not become the record.

    What to Do With the Score

    Use it to decide what to teach next, and put as little of it in the gradebook as your school allows. A seminar rubric’s best use is diagnostic.

    Look down the columns rather than across the rows. If twenty of twenty-eight students scored low on use of the text, that is not twenty-eight individual grades — that is one lesson about citing a line, and you should teach it before the next seminar instead of recording twenty low scores. If preparation is the weak column, the problem is upstream of the seminar entirely and no amount of facilitation will fix it.

    If the scores do go in the gradebook, weight them low and tell students the weight. A seminar is a practice format. Grading practice heavily is how you get students who will not risk a wrong reading out loud, which is the one behavior the whole format exists to produce.

    What to Do Next

    Take the rubric above, rewrite the use of the text row so it names what evidence looks like in the specific text you are teaching, and hand it to students the day before — not the day after. Score criteria one and four from the paper they turn in. Pick six students for the live criteria and tell them who they are.

    Then run it twice before you judge either the rubric or your class. If you need the rest of the format, it is in the guide to running a Socratic seminar, and the questions that make one worth scoring are in the seminar question bank.

    Before you go: grab the free Socratic Seminar Rubric (Four Criteria) (PDF) — ElevateTheNorm.com branded, printable, no email required.

    Frequently Asked Questions

    What should a Socratic seminar rubric include?

    Four criteria: preparation, use of the text, treatment of other people’s ideas, and written reflection afterward. Three of the four produce writing, which means you can score them after the period rather than while facilitating, and a student who spoke twice can still score well. What it should not include is a count of how many times a student spoke.

    Should you grade a Socratic seminar at all?

    Grade the preparation and the reflection, and weight the whole thing lightly. A seminar is a practice format, and grading practice heavily produces students who will not risk a wrong reading out loud — which is the behavior the format exists to create. If a participation grade is required, take it from the written criteria and say plainly that speaking is not scored.

    Why shouldn’t a rubric count how many times a student speaks?

    Because it measures confidence and charges a fee to students who find speaking aloud genuinely hard. A study of quiet students found most struggled with verbal participation expectations and several reported physical symptoms — trembling, blushing, stuttering — when speaking in class. Frequency is also easy to game: three short comments at the right moments will beat one student who prepared thoroughly and spoke once.

    Is an analytic or holistic rubric better for a seminar?

    Analytic, if you want consistency. A review of 75 rubric studies found scoring reliability improves when rubrics are analytic and topic-specific and are paired with exemplars or rater training. Holistic rubrics are faster and less consistent, and with something as fuzzy as discussion quality, consistency is exactly what you are short of.

    Do rubrics actually improve student learning?

    The evidence is genuinely mixed. A review of 21 studies of formative rubric use found effects ranging from very large to nothing, and noted that most studies combined rubrics with other interventions, so the rubric’s own contribution is hard to isolate. What the authors identify as the mechanism is transparency — which means handing the rubric out before the seminar rather than attaching it to the grade afterward.

    How do you score thirty students during one seminar?

    You do not. Facilitating and scoring are two jobs, and doing both means doing the facilitation badly. Score the two written criteria from paper afterward, and score the two live criteria for a rotating group of about six students per seminar, told in advance. Over five seminars everyone gets scored twice on the live criteria.

    Should students score themselves on the seminar rubric?

    Yes, before you score them, using the same rubric with one sentence of evidence per criterion. Where your score and theirs differ by more than one level, that gap is the conversation worth having. Keep the self-score as information rather than as the grade — the moment it becomes the grade, students learn to inflate it.

    Is this Socratic seminar rubric free to use?

    Yes. It is printed in full on this page and there is a free printable version too, with no email address to hand over, and you are welcome to copy it, cut criteria, or rewrite the language to match your school’s scale. Rewriting the use-of-the-text row so it names what evidence looks like in your specific text is the single change that will do the most for consistency.

    Sources

    1. Jonsson, Anders, and Gunilla Svingby. “The Use of Scoring Rubrics: Reliability, Validity and Educational Consequences.” Educational Research Review, vol. 2, no. 2, 2007, pp. 130–144. Review of 75 empirical studies; reliable scoring “can be enhanced by the use of rubrics, especially if they are analytic, topic-specific, and complemented with exemplars and/or rater training”; rubrics do not by themselves guarantee valid judgements. https://eric.ed.gov/?id=EJ796733
    2. Panadero, Ernesto, and Anders Jonsson. “The Use of Scoring Rubrics for Formative Assessment Purposes Revisited: A Review.” Educational Research Review, vol. 9, 2013, pp. 129–144. 21 studies; effects on performance ranged from large (0.99–1.6) to negligible, and “most studies reporting on such improvements have combined the use of rubrics with other instructional interventions.” Positive effects more likely in higher education, over longer interventions, and when paired with metacognitive activity. https://platform.europeanmoocs.eu/users/4567/Les3/Panadero-Jonsson-rubrics-3.pdf
    3. Murphy, P. Karen, et al. “Examining the Effects of Classroom Discussion on Students’ Comprehension of Text: A Meta-Analysis.” Journal of Educational Psychology, vol. 101, no. 3, 2009, pp. 740–764. Discussion produced strong increases in student talk and substantial gains in text comprehension, but “few approaches to discussion were effective at increasing students’ literal or inferential comprehension and critical thinking and reasoning.” https://eric.ed.gov/?id=EJ861185
    4. Applebee, Arthur N., Judith A. Langer, Martin Nystrand, and Adam Gamoran. “Discussion-Based Approaches to Developing Understanding: Classroom Instruction and Student Performance in Middle and High School English.” American Educational Research Journal, vol. 40, no. 3, 2003, pp. 685–730. 64 middle and high school English classrooms, grades 7, 8, 10, 11 and 12. https://eric.ed.gov/?id=EJ782328
    5. Medaille, Ann, and Janet Usinger. “Quiet Students’ Experiences with the Physical, Pedagogical, and Psychosocial Aspects of the Classroom Environment.” Educational Research: Theory and Practice, vol. 31, no. 2, 2020, pp. 41–55. Ten upper-division undergraduates — not secondary students; nine of ten struggled with verbal participation expectations and six reported physical symptoms when speaking aloud. https://files.eric.ed.gov/fulltext/EJ1274336.pdf
    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • Student Goal Setting: What Works in Grades 6–12, and What the Evidence Won’t Carry

    Student Goal Setting: What Works in Grades 6–12, and What the Evidence Won’t Carry

    By Clay Shumate

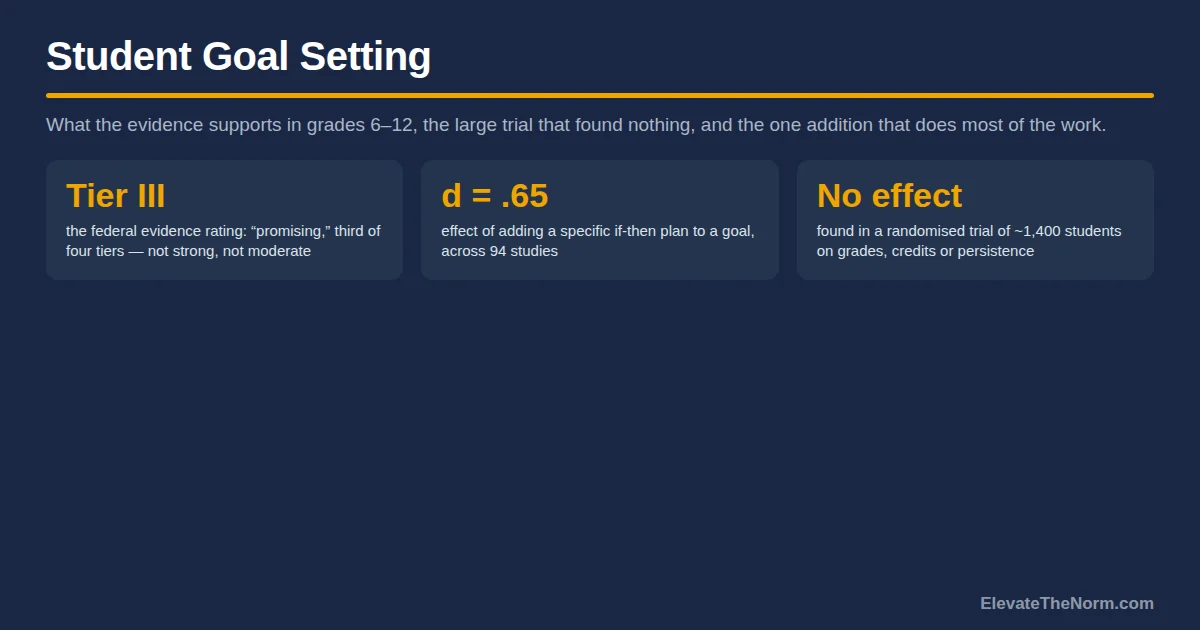
    Student goal setting is the practice of having students name a specific, near-term target for their own learning, plan how they will hit it, and check whether they did. It is cheap, it is popular, and the federal evidence review rates it “promising” rather than strong — which is a more useful place to start than the version you got in a faculty meeting.

    What follows is what the research supports, the large trial that found nothing, and the part that actually moves the needle: the plan, not the goal.

    Key Takeaways

    • The official rating is Tier III, “promising evidence.” That is the third-highest tier, below strong and moderate. Anyone selling this as settled is overselling it.
    • The best secondary study is correlational. 1,273 high school students over five years showed a significant relationship between goal writing and proficiency — with no control group, so causation is not established.
    • A large randomised trial found nothing. About 1,400 first-year college students, precisely estimated null on grades, credits and persistence — and it was a failed replication of a pilot that had reported more than half a standard deviation.
    • The plan beats the goal. Across 94 studies, forming a specific “if X, then I will Y” plan had a medium-to-large effect on goal attainment (d = .65). Wanting it more is not the mechanism.
    • Goal setting alone is not an intervention. The federal review says so outright: it “cannot be assumed to produce positive outcomes for students” on its own.

    Free Download · PDF

    The Student Goal and If-Then Plan Sheet

    Student-facing: five tests for a goal worth setting, the if-then plan frame, four worked examples by subject, and a two-week check-back log.

    Download the free PDF

    Free. No email address required. Designed for grades 6–12. Browse every printable in Your Free Library.

    What Is Student Goal Setting?

    Student goal setting is a short cycle, not a form. The student names a specific target for their own learning, decides what they will actually do to reach it, does it, gathers some evidence, and judges honestly whether they got there. Then the cycle runs again.

    The word doing the work in that definition is own. A target a teacher assigns and a student copies onto a sheet is not goal setting; it is an objective with a student’s handwriting on it. The federal practice guide is specific that letting students set their own goals is one of the components associated with better outcomes, alongside goals that are proximal (near-term rather than end-of-year), specific rather than general, and optimally challenging — hard enough to require something, not so hard the student has already lost.

    It is also the forward-facing half of a pair. Student self-assessment asks a teenager to judge work they have already done. Goal setting asks the same student to aim at work they have not done yet. Neither one works well without the other — a goal set by a student with no accurate read on where they currently stand is a guess.

    Does Student Goal Setting Actually Work?

    The honest answer is “promising, conditional, and less certain than the training implies.” Three pieces of evidence, and they do not all point the same way.

    The official rating. The Regional Educational Laboratory Midwest reviewed student goal setting for the Institute of Education Sciences and rated it Tier III, “promising evidence” under the federal evidence standards. Tier III is the third-highest of four. It means there is correlational research with statistical controls behind the practice — not that it has been shown to cause anything in a well-controlled trial.

    The best secondary-school study. Moeller, Theiler and Wu followed 1,273 high school students across five years, 21 teachers and 23 Nebraska schools, using a portfolio system built on self-assessment, goal writing and evidence collection. Goal writing and action-plan writing both showed statistically significant relationships with language proficiency scores, independent of teacher effects. It is a large, long, genuinely secondary study, and the authors say plainly that there was no control group and causation cannot be established.

    The trial that found nothing. Dobronyi, Oreopoulos and Petronijevic randomly assigned about 1,400 first-year university students to a structured goal-setting exercise, with or without follow-up reminders, against a control group. They found “no evidence of an effect of treatment” on grades, credits taken, credits failed, or second-year persistence — and their sample was large enough to have detected a 7 percent standardised effect. Their study was an attempt to replicate an earlier pilot that had reported a treatment effect on GPA of more than half a standard deviation. It did not replicate.

    Those students were undergraduates, not teenagers, and a one-off written exercise is not a classroom routine. Both of those are real reasons the null might not transfer. But it is exactly the kind of result that quietly disappears from professional development, and it is the reason the federal review ends up at “promising” instead of “strong.”

    What the review actually concludes is the sentence to keep: goal setting “in isolation cannot be assumed to produce positive outcomes for students.” It works when it is attached to planning, self-evaluation, regular feedback and reflection. Handed out as a September worksheet, it is a September worksheet.

    Why Do Most Classroom Goal-Setting Systems Die by October?

    Because the goal gets set and nothing after it is scheduled. Every failure I have watched has the same shape: a strong launch, a folder, and then nothing on the calendar that forces anyone to look at the folder again.

    Four specific failure modes, and each one has a cheap fix.

    1. The goal is too far away. “Raise my grade this semester” gives a student nothing to do on Tuesday. Proximal beats distal in the research and in the room. Two weeks is a good default.
    2. The goal is a wish, not a behavior. “Try harder in this class” cannot be checked by anybody, including the student. If you cannot tell from the outside whether it happened, it is not a goal.
    3. Nobody scheduled the review. This is the big one. If the goal review is not a thing that happens on a specific day, it does not happen. Put it in the plan the same way you would put in a quiz.
    4. The teacher owns it. The moment students believe the goal sheet is for you — for a binder check, for a walkthrough, for the folder an administrator might ask about — they write what looks good. You will get twenty-eight reasonable-sounding goals and zero information.

    There is a version of the fourth failure that no teacher can fix alone. If a district requires the goal sheet as a walkthrough artifact or a PLC deliverable, it has made the sheet an adult document by design, and students will read that correctly within a week. Goal setting is cheap enough to mandate and fragile enough that mandating it is usually how it dies. If it has to be collected, collect the evidence that the review happened — a date, a count — and leave the goals themselves with the student.

    The fourth one is the one worth guarding hardest, and it connects to something this site keeps coming back to: a choice that is really a compliance task in disguise teaches students to produce the appearance of the thing instead of the thing.

    What Makes a Goal Worth Setting?

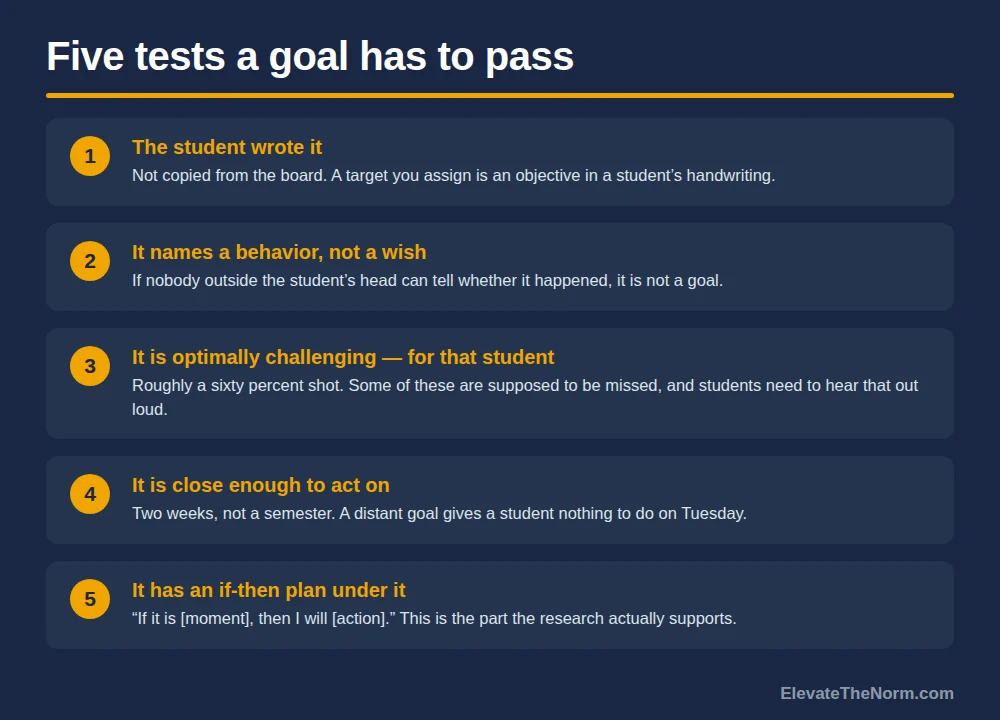
    Five tests, and a goal that fails any of them will not survive two weeks. Run a student’s draft against these before it goes in the folder.

    Numbered list of five tests for a student goal: the student wrote it, it names a behavior rather than a wish, it is optimally challenging for that student, it is close enough to act on, and it has an if-then plan under it
    Run a student’s draft against these before it goes in the folder.

    The hardest of the five is the third. “Optimally challenging” sounds like jargon, and in practice it means a goal a student has maybe a sixty percent chance of hitting — which means some goals are supposed to be missed. Say that to the students in those words, on day one: you are supposed to miss some of these, and missing one is not a problem you will be in trouble for. If you do not say it, they will write goals they are certain of, and the whole system drifts toward targets everybody hits and nobody learns anything from. Say it to whoever reads the folder too, for the same reason.

    And “optimally challenging” is calibrated to the student, not to the class. A goal that is a genuine stretch for one student is a formality for the one beside them, which means the whole point breaks the moment you set a common goal and call it differentiated. It also means a student who has spent years being told they are behind may aim absurdly low the first time. That is information, not defiance, and the move is to negotiate one notch up rather than to reject the goal. The same argument sits underneath holding a standard high while making the path to it real: a target nobody misses was never a target.

    Are SMART Goals the Right Format?

    They are a reasonable checklist and a weak intervention, and it is worth knowing which one you are using. Specific and measurable are supported by the research on goal specificity. What SMART does not contain is the part that most predicts whether a goal gets reached.

    Look at what a SMART goal actually produces: a well-formed description of a destination. “I will score at least 80 percent on the next two vocabulary quizzes.” Specific, measurable, achievable, relevant, time-bound — and it contains no information about what the student will do differently on Wednesday. A student who could already answer that question did not need the acronym.

    I am not telling anyone to throw the format out. If your school uses it, use it. Just do not stop there, because the next section is where the evidence is.

    The If-Then Plan That Does the Work

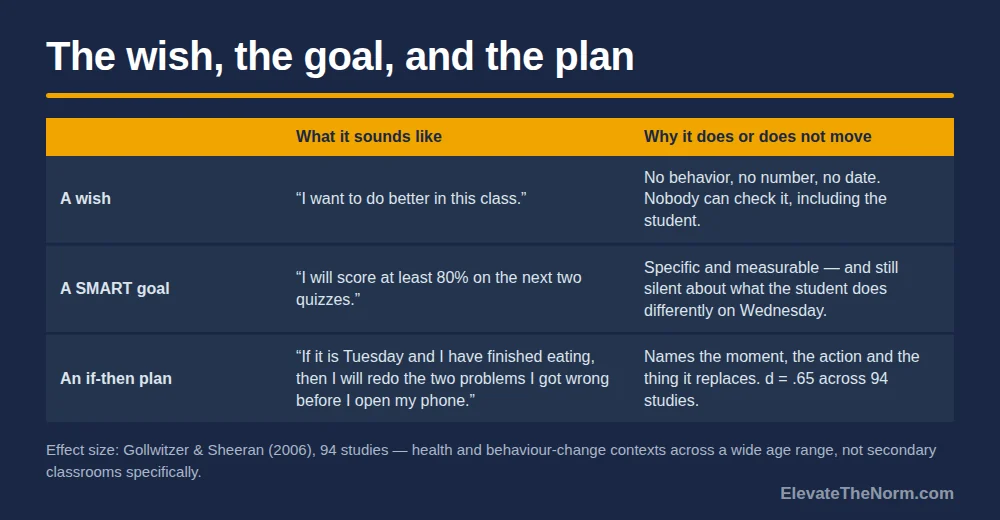
    Adding a specific “if X happens, then I will do Y” plan to a goal had a medium-to-large effect on whether the goal got reached — d = .65 across 94 studies. Psychologists call these implementation intentions. Students can call them if-then plans and use them in about ninety seconds.

    Table comparing a wish, a SMART goal and an if-then plan, showing what each sounds like and why the if-then plan names the moment, the action and the thing it replaces
    SMART describes a destination. The if-then plan names the moment you act.

    Gollwitzer and Sheeran’s meta-analysis describes them as “if-then plans that link situational cues… with responses that are effective in attaining goals.” The effect split two ways that map exactly onto what teenagers struggle with: d = .61 for getting started and d = .77 for getting derailed. The larger of the two is the one about staying on track after something goes wrong, which is the failure mode for most students, most of the time.

    Two honest limits from the same paper. If there are few real barriers to a goal, the if-then plan is superfluous — a student who was going to do it anyway does not need one. And the strong effects showed up “predominantly when the underlying goal intention was strong.” An if-then plan attached to a goal the student does not care about does nothing. That is not a flaw in the technique; it is the reason the student has to write the goal.

    Here is the frame students actually use, and it is worth writing on the board: “If it is [a specific time or trigger], then I will [a specific action].” The test is whether a stranger could tell from the outside that it happened. Watch a real one get fixed: “I will review my notes more” is not a plan. “If it is Tuesday and I have finished eating, then I will redo the two problems I got wrong before I open my phone” is one, because it names the moment, the action and the thing it replaces. Most student first drafts are missing the moment. That is the only edit you usually have to make.

    Worth saying about the population too: this meta-analysis spans health, behavior change and academic contexts across a wide age range, not a set of secondary classrooms. The mechanism is general. The classroom result is a reasonable inference, not a measured one.

    Student Goal Setting Examples for Grades 6–12

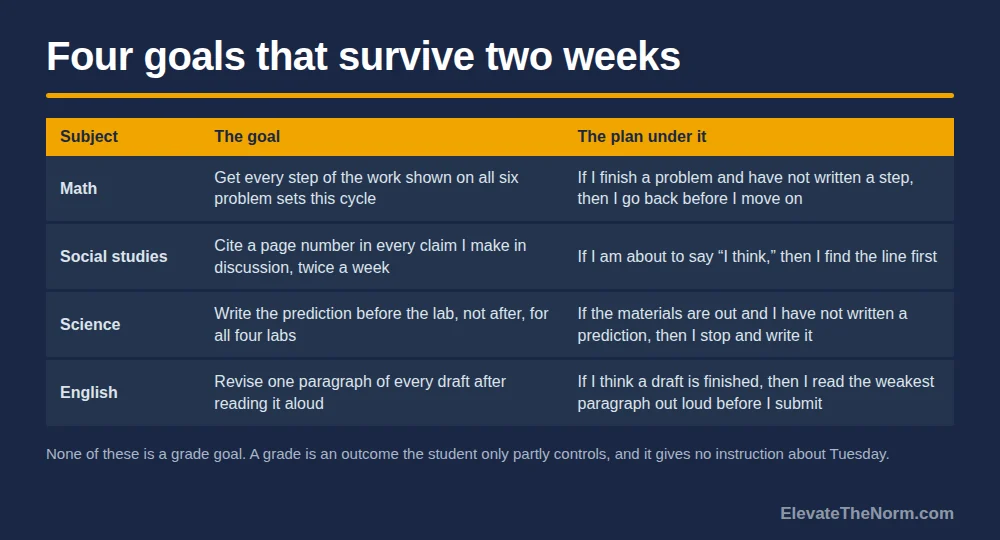
    A usable goal names a behavior, a number and a date, and is followed by a plan that names a moment. Here is the difference in practice, by subject.

    Table of four student goal setting examples in math, social studies, science and English, each paired with the if-then plan that sits under it
    Four subjects, four goals, and the plan that makes each one survive two weeks.

    Notice what every one of the good versions has that the bad version does not: a specific when. Not “I will study more” but “when I sit down Tuesday after practice.” The when is the whole mechanism. Without it the student has written a wish with a deadline attached.

    One more thing about the examples above: none of them is about a grade. Grade goals are the ones students reach for first, and they are the least useful, because a grade is an outcome the student only partly controls and it gives no instruction about behavior. “Get a B” tells you nothing to do Tuesday. If a student insists on a grade goal, ask the follow-up: what would have to be different in your week for that to happen? The answer is the actual goal.

    What Teachers Should Not Do With Student Goals

    Three things, and all three are common.

    Do not grade the goal. A graded goal is a goal a student sets low, which destroys the only thing a goal is for. Grade the work; the goal is instrumentation. If you need a grade out of the process, grade whether the reflection is honest and specific — a student who writes “I did not do this and here is why” has done the assignment correctly.

    Do not post them. Goal walls, goal charts and public trackers look like accountability and function as ranking. A student setting a goal is disclosing what they are not good at yet, in front of everyone they eat lunch with. Some students can carry that and some cannot, and you will not know which is which until it goes wrong. Keep goals in a folder, a document, or a conversation.

    Do not let a classroom goal collide with an IEP goal. If a student has goals written into an IEP or a 504 plan, those are legal documents with their own review cycle and their own people attached. A classroom goal that restates them turns your folder into a parallel record of a student’s disability, and one that pulls against them creates a conflict the student has to resolve. Ask the case manager first. Usually the answer is simple — keep the classroom goal about something the IEP does not cover — but it should be a decision rather than an accident.

    And tell families what this is before they hear about it secondhand. One sentence in a syllabus or an email does it: students set a short-term learning goal every two weeks, the goals are not graded and are not a judgment about the student, and a missed goal is a normal part of how the routine works. Parents who learn about a goal folder from a worried fourteen-year-old will assume it is an evaluation, and they will be reasonable to assume it.

    Do not let a goal become a record. If a student’s goal sheet contains anything about their home life, their diagnosis, their family or their mental health — and if you ask an open enough question, eventually one will — then you are holding a document you did not plan to hold. Keep the prompts academic and behavioral, say clearly what you do and do not do with the sheets, and know your school’s policy before you build a system that collects them. A goal-setting routine is a data-collection routine whether you designed it as one or not.

    How Often Should Students Revisit a Goal?

    Every two weeks, on a date that is already on the calendar, and in writing. Anything longer and the goal stops being operative; anything shorter and you are spending class time on the system instead of the work.

    The review is three questions and it takes six minutes. Did you do the thing you said you would do? What is the evidence? What is the goal for the next two weeks — the same one, or a different one? A student who missed and says why has not failed the routine. A student who quietly rewrites history has, and the way you prevent that is by making it clearly safe to have missed.

    The version I trust most is not a form at all. I pull students over one at a time and ask them to defend their own decisions out loud — why this goal, why that plan, what the evidence is. It takes longer than collecting sheets and it is harder to fake. A student who has to say it to your face either has a reason or discovers on the spot that they do not, and both of those outcomes are more useful than a folder.

    The arithmetic does not work at scale, and pretending otherwise is how this advice gets ignored. Six minutes times a hundred and forty students is not a thing anyone is doing every two weeks. So rotate: five or six conversations per cycle, everybody else writes, and every student gets a real check-in roughly once a quarter. Choose the five deliberately rather than by who volunteers — the students who most need to say it out loud are rarely the ones raising a hand.

    One thing to watch for across cycles: a student who misses every goal is not a student who is failing at goal setting. It is a miscalibration, and the calibration is the adult’s job. Sit down, cut the goal in half, and let them hit one. A student who has never once hit a target they set has learned only that setting targets is pointless, which is worse than not having asked. When these check-ins feed a conversation with families, they are also most of the preparation for a conference the student actually leads.

    What to Do Next

    Pick one class. Have every student write one two-week goal that names a behavior and a number, and then — this is the part that matters — have them write one sentence underneath it in the form “If [specific moment], then I will [specific action].” Put the review date in your plans before the students leave the room.

    Then run it twice before you judge it. The first cycle teaches them the format. The second one is the first real data you will get, and it will tell you more about your class than the goals themselves do.

    And set your expectations where the evidence sets them. This is a promising practice that works as part of something — planning, feedback, honest self-assessment, a conversation — and does very little on its own. A worksheet in September is not a goal-setting system. A date on the calendar is.

    Before you go: grab the free The Student Goal and If-Then Plan Sheet (PDF) — ElevateTheNorm.com branded, printable, no email required.

    Frequently Asked Questions

    What is student goal setting?

    It is a short repeating cycle in which a student names a specific, near-term target for their own learning, plans what they will actually do to reach it, gathers evidence, and judges honestly whether they got there. The key word is “own” — a target the teacher assigns and the student copies onto a sheet is an objective in the student’s handwriting, not a goal.

    Does student goal setting improve achievement?

    The federal evidence review rates it Tier III, “promising evidence” — the third-highest of four tiers. A five-year study of 1,273 high school students found a significant relationship between goal writing and proficiency, but it had no control group. A randomised trial of about 1,400 first-year college students found no effect at all on grades, credits or persistence. The honest summary is that it helps when it is attached to planning and feedback and does little by itself.

    Are SMART goals good for students?

    They are a reasonable checklist for describing a destination and a weak intervention on their own. Specific and measurable are genuinely supported by the research on goal specificity. What SMART does not include is any statement of what the student will do differently, and that is the part that predicts whether the goal gets reached. Use it if your school uses it, then add an if-then plan underneath.

    What is an if-then plan and why does it matter more than the goal?

    It is a sentence in the form “if [specific situation], then I will [specific action]” — researchers call it an implementation intention. Across 94 studies it had a medium-to-large effect on goal attainment, d = .65, with d = .61 for getting started and d = .77 for getting back on track after getting derailed. A goal describes where you want to end up. The if-then plan names the moment you will act.

    How often should students revisit their goals?

    About every two weeks, on a date that is already in your plans. Longer than that and the goal stops being operative; shorter and you spend class time on the system instead of the work. The review is three questions and takes six minutes: did you do it, what is the evidence, and what is the goal for the next two weeks.

    Should student goals be graded?

    No. A graded goal is a goal the student sets low, which removes the only thing a goal is useful for. If you need a grade from the process, grade whether the reflection is honest and specific. A student who writes “I did not do this, and here is why” has done the assignment correctly.

    Should I post student goals on the wall?

    No. A public goal chart looks like accountability and functions as a ranking, because a student setting a goal is disclosing what they are not good at yet in front of everyone they eat lunch with. Keep goals in a folder, a document or a conversation. Visibility is not the mechanism; the plan and the review date are.

    Why do goal-setting systems stop working after a few weeks?

    Almost always because nothing after the goal was scheduled. The four usual causes are a goal that is too far away, a goal that describes a wish rather than a behavior, a review that never got a date, and a system students correctly perceive as being for the teacher’s binder. Only the last one is about motivation, and it is fixed by keeping the goals out of anything that gets inspected.

    Sources

    1. U.S. Department of Education, Institute of Education Sciences, Regional Educational Laboratory Midwest. Student Goal Setting: An Evidence-Based Practice. 2018. ERIC ED589978. Rates student goal setting Tier III, “promising evidence,” under federal evidence standards; identifies optimally challenging, proximal, specific, self-set and mastery-oriented goals as the supported components; and states that goal setting “in isolation cannot be assumed to produce positive outcomes for students.” https://files.eric.ed.gov/fulltext/ED589978.pdf
    2. Moeller, Aleidine J., Janine M. Theiler, and Chaorong Wu. “Goal Setting and Student Achievement: A Longitudinal Study.” The Modern Language Journal, vol. 96, no. 2, 2012, pp. 153–169. Five-year quasi-experimental study, 1,273 high school students, 21 teachers, 23 Nebraska schools; goal writing and action-plan writing significantly related to proficiency scores independent of teacher effects. No control group; the authors state causation cannot be established. https://www.ncssfl.org/wp-content/uploads/2017/11/MLJ.2012.GoalSettingandStudentAchievementLongitudinalStudy.pdf
    3. Dobronyi, Christopher R., Philip Oreopoulos, and Uros Petronijevic. “Goal Setting, Academic Reminders, and College Success: A Large-Scale Field Experiment.” Journal of Research on Educational Effectiveness, vol. 12, no. 1, 2019, pp. 38–66. Randomised trial, approximately 1,400 first-year university students; “no evidence of an effect of treatment” on grades, credits or persistence, precise enough to detect a 7 percent standardised effect. A failed replication of a pilot reporting more than half a standard deviation on GPA. Population: undergraduates, not secondary students. https://oreopoulos.faculty.economics.utoronto.ca/wp-content/uploads/2020/05/dobronyi-et-al-goal-setting-academic-reminders-and-college-success-jree-2019.pdf
    4. Gollwitzer, Peter M., and Paschal Sheeran. “Implementation Intentions and Goal Achievement: A Meta-Analysis of Effects and Processes.” Advances in Experimental Social Psychology, vol. 38, 2006, pp. 69–119. 94 studies; overall d = .65, with d = .61 for getting started and d = .77 for getting derailed. Notes that effects are reduced when few barriers exist and that strong effects appeared “predominantly when the underlying goal intention was strong and activated.” Spans health and behaviour-change contexts across a wide age range, not secondary classrooms specifically. https://cancercontrol.cancer.gov/sites/default/files/2020-06/goal_intent_attain.pdf

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • Formative Assessment Strategies for Reading: Five Checks That Fit a Real Week

    Formative Assessment Strategies for Reading: Five Checks That Fit a Real Week

    By Clay Shumate

    Formative assessment strategies for reading are short, ungraded checks that show you what students understood from a text while the lesson is still running. A two-sentence gist, a flagged confusion, a prediction. They take two minutes, they are not graded, and they are only worth doing if the answer changes what you teach next.

    What follows is the honest version: five checks that survive a real secondary schedule, a routine that does not require reading 120 responses, and the numbers — including the ones that are smaller than your last in-service claimed.

    Key Takeaways

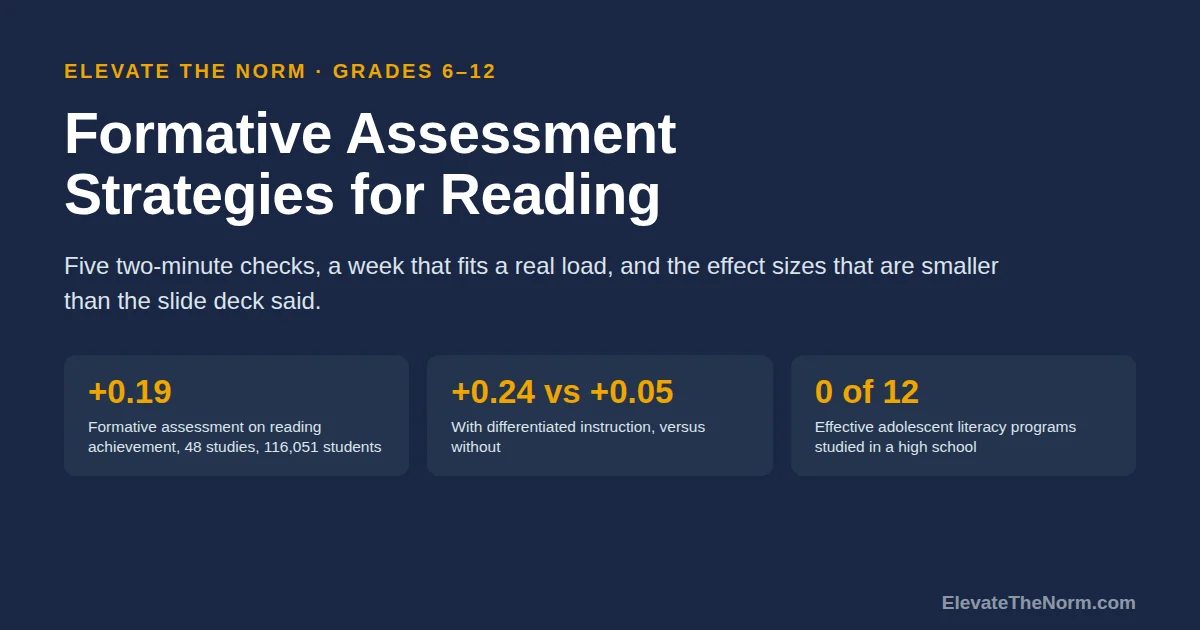
    • The check is not the intervention. What you do with the answer is. Studies where reading checks fed differentiated instruction showed nearly five times the effect of studies where they did not.
    • The honest effect is modest. Around +0.19 to +0.20, not the 0.40 to 0.70 that gets quoted. English language arts does better than math or science at 0.32.
    • Sort, do not mark. Twenty-eight gist statements is a five-minute sort into three piles. Marking them is what kills the practice by week three.
    • Nothing here requires reading aloud in front of the class. That is a design decision, not an oversight.
    • The high school evidence gap is real. An IES review found twelve adolescent literacy programs with positive effects and not one of them studied in a high school.

    Free Download · PDF

    Formative Assessment Quick-Use Pack

    A strategy decision matrix, an evidence tracker, four exit-ticket formats, and a next-day response planner — four pages built around changing the next instructional move.

    Download the free PDF

    Free. No email address required. Designed for grades 6–12. Browse every printable in Your Free Library.

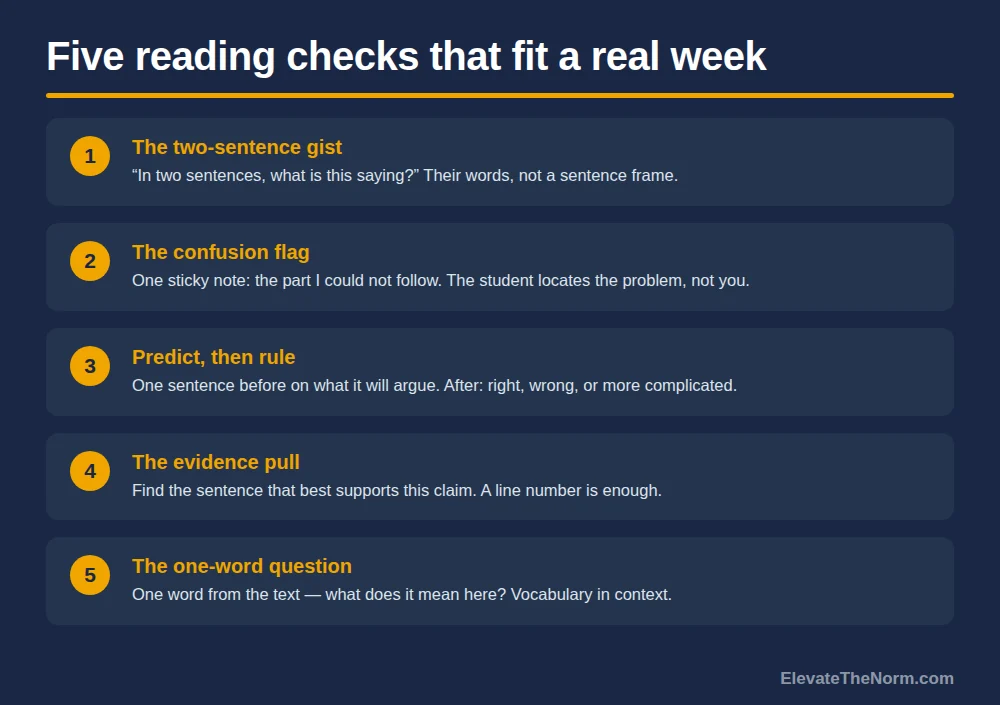
    Numbered list of five formative reading checks: the two-sentence gist, the confusion flag, predict then rule, the evidence pull, and the one-word question, each with a one-line description
    Five checks. None takes more than three minutes and none requires reading aloud.

    What Counts as a Formative Assessment Strategy for Reading?

    Any short check that tells you what a student took from a text in time for you to act on it. The format is negotiable. The timing is not.

    That definition rules more out than it rules in. A comprehension worksheet collected at the bell and returned Thursday is not formative — not because worksheets are bad, but because the information arrived after the decision it was supposed to inform. A five-question quiz you grade and record is summative wearing different clothes. The line is whether the answer reaches you while you can still change the next ten minutes.

    It also rules out the thing most reading checks actually measure, which is whether a student did the reading. That is a useful fact and it is not comprehension. “Did you read it” and “what did you understand” require different questions, and conflating them is how a teacher ends up with a stack of evidence that everyone read a chapter nobody understood. The broader version of this distinction is covered in the cross-subject guide to choosing a check and acting on it; this page is the reading-specific case.

    What Does the Research Actually Show?

    A modest, consistent benefit — smaller than the number most professional development quotes.

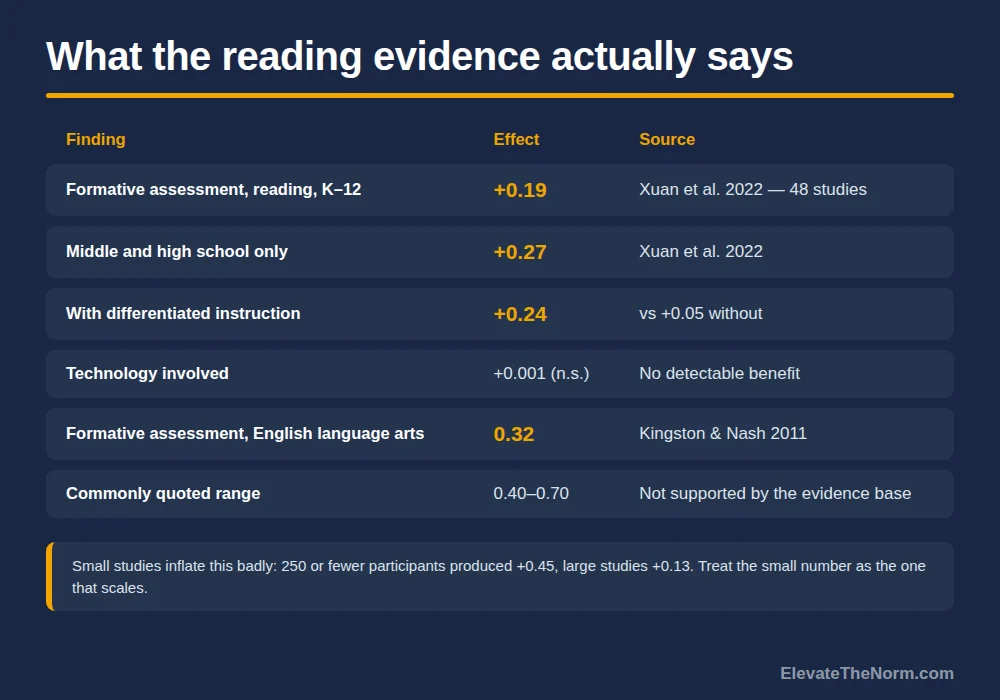
    The most direct evidence is a 2022 meta-analysis by Xuan, Cheung and Sun covering 48 qualifying studies and 116,051 K–12 students. The pooled effect of formative assessment on reading achievement was +0.19 (95% CI 0.15–0.23). By grade band: kindergarten +0.28, elementary +0.16, and middle and high school +0.27 — though the meta-regression found grade-level differences were not significant once other variables were controlled. Secondary students are not the weak case here.

    The older and more quoted number is worse than people think. Kingston and Nash reviewed more than 300 studies, found only 13 with enough data to analyze, and reported a weighted mean effect of 0.20. Their conclusion is unusually blunt for a meta-analysis: the 0.40 to 0.70 figure “often claimed for the efficacy of formative assessment… is not supported by the existing research base.” The one genuinely encouraging row for a reading teacher is the subject breakdown — English language arts came in at 0.32, against 0.17 for mathematics and 0.09 for science.

    So: real, replicated, worth two minutes a day. Not transformational, and anyone selling it as transformational is selling something.

    Table of effect sizes for formative assessment on reading: plus 0.19 across K-12, plus 0.27 for middle and high school, plus 0.24 with differentiated instruction versus plus 0.05 without, plus 0.001 for technology involvement, and 0.32 for English language arts
    The numbers, including the one that contradicts the slide deck.

    What Makes the Difference Between a Check That Works and One That Does Not?

    Two moderators did most of the work, and neither is the check itself.

    First, who uses the information. In the Xuan meta-analysis, teacher-directed approaches alone produced significantly smaller effects than approaches that integrated teacher and student use of the results (coefficient −0.12, p < 0.001). Purely student-directed assessment showed no significant advantage either. The winning configuration is both: you see the pattern, and the student sees their own answer against what the text actually said.

    Second, whether anything got differentiated. Studies in which the information fed differentiated instruction showed an effect of +0.24. Studies where it did not: +0.05. That is close to the whole finding. A reading check that produces a number you record and nothing you change is worth almost nothing, and the meta-analysis says so with a p-value.

    And one thing that made no difference at all: technology. The moderator coefficient for technology involvement was +0.001 (p = 0.978). A Google Form and a sticky note perform identically. Pick the one your students will finish in ninety seconds.

    Which Five Reading Checks Fit a Real Secondary Schedule?

    These five take two to three minutes, need no materials beyond paper, and none requires a student to read aloud in front of peers.

    • The two-sentence gist. After a passage: “In two sentences, what is this saying?” Not a summary, not a main idea in a sentence frame. Two sentences in their own words. The students who can’t do it in their own words are the ones you need to find.
    • The confusion flag. One sticky note, one sentence: the part of this text I could not follow. Nothing else on it. Collected at the door. This is the highest-yield check on the list because it is the only one where the student, not you, locates the problem.
    • Pre-reading prediction, post-reading verdict. Before: one sentence on what you expect this will argue. After: right, wrong, or more complicated, and why. The post-reading half is the assessment; the pre-reading half is what makes them read looking for something.
    • The evidence pull. “Find the sentence in the text that best supports this claim.” Line number is enough. It is fast to scan and it catches the student who agrees with an argument without being able to find it on the page.
    • The one-word question. Give a single word from the text and ask what it means here. Vocabulary in context is the check with the strongest evidence behind it — explicit vocabulary instruction is one of the two practices the What Works Clearinghouse panel rates strong for adolescent literacy.

    The WWC practice guide is worth reading alongside these. Its five recommendations carry explicit evidence ratings: explicit vocabulary instruction (strong), direct and explicit comprehension strategy instruction (strong, based on five randomized experiments), extended discussion of text meaning (moderate), increasing motivation and engagement (moderate), and intensive individualized intervention for struggling readers (strong). The panel is honest about its own limits: most of the discussion studies used narrative texts, which is a meaningful caveat if you teach history or science. When I need a quick way to analyze a source with students, I use my Current Events and Media Literacy Bundle on TPT.

    How Do You Run This Without Reading 120 Responses?

    You sort them. You do not mark them.

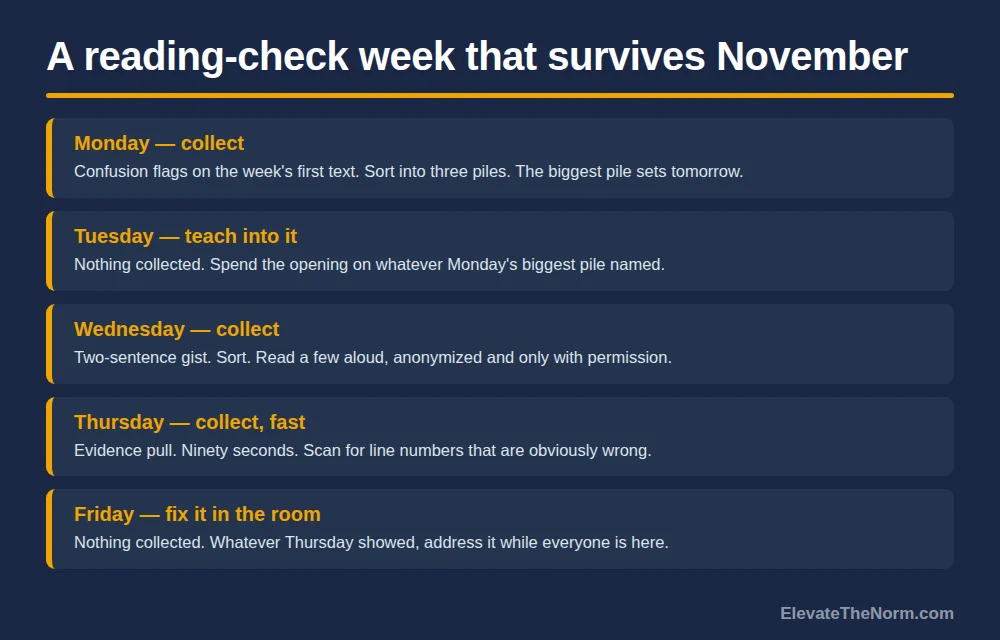
    This is the single practical thing that decides whether a teacher is still doing reading checks in November. Twenty-eight two-sentence gist statements is not a marking job. It is a five-minute sort into three piles — got it, partial, missed the point — and the only thing you write down is how many are in each pile. Three numbers. That is your instructional decision. If you would rather not design the recording sheet yourself, the free quick-use pack includes a class evidence tracker built for exactly that three-pile sort.

    Here is a week that fits a normal load:

    • Monday. Confusion flags on the week’s first text. Sort into piles. Whatever the biggest pile names becomes Tuesday’s opening five minutes.
    • Tuesday. Nothing collected. Teach into Monday’s biggest pile. This is the differentiation the research is actually measuring.
    • Wednesday. Two-sentence gist. Sort. Read four aloud — anonymized, and only with the writer’s permission, because every student recognizes their own sentences.
    • Thursday. Evidence pull on the same text. Ninety seconds. Scan for line numbers that are obviously wrong.
    • Friday. Nothing collected. Whatever Thursday showed, fix it in the room.

    Two collection days, two teaching-into days, one flexible. That is the whole system, and it is deliberately smaller than what a district rollout would design, because a smaller system that runs every week beats a comprehensive one that runs until October.

    Five-day routine showing Monday collect confusion flags, Tuesday teach into the biggest pile, Wednesday collect two-sentence gists, Thursday collect a fast evidence pull, and Friday fix what Thursday showed
    Two collection days. Two days spent on what they showed. That is the ratio that matters.

    What Does This Look Like in a Room?

    My room runs as a workshop, and the piece of furniture that does the most work is a whiteboard table I built, set in a corner under a lower lamp, with a rug and better chairs than the rest of the room has. Students ask to go there. That matters more than it sounds like it should.

    When a confusion flag says something I cannot fix from the front of the room, that table is where the conversation happens — not as a remediation station, because it is the seat everyone wants. A student reading a paragraph out loud at that table, with one other person, is doing the same thing that would humiliate them standing at their desk. The check tells you who needs the conversation. The room decides whether the conversation costs them anything.

    That is the part no meta-analysis measures and the part a teacher controls completely.

    Two ready-to-run versions of that table, one for grades 6–8 and one for grades 9–12, are laid out in the site’s guide to small group instruction in middle and high school.

    Where Does the Evidence Run Out?

    At high school, more precisely than most people admit.

    An IES review summarizing twenty years of adolescent literacy research screened 111 studies, found 33 meeting What Works Clearinghouse evidence standards, and identified 12 programs and practices with positive or potentially positive effects on reading comprehension, vocabulary or general literacy across grades 6–12. And then the line that belongs in every conversation about this: none of the 12 was conducted in a high school setting. The evidence base for adolescent literacy is, in practice, a middle school evidence base.

    Three more honest limits from the meta-analytic work. Small studies inflate the result badly — studies with 250 or fewer participants produced an effect of +0.45 against +0.13 for large ones, which is the usual sign that tightly-supervised implementations outperform real ones. The Xuan authors found no significant difference between published and unpublished studies, so publication bias is not the explanation, but the sample-size gap is a warning about what happens when a practice scales. And only 8 of the 48 studies came from Confucian-heritage contexts against 40 Anglophone, so the authors caution against moving interventions across cultures unadapted.

    None of that is a reason not to run a two-minute gist check. It is a reason not to build a district initiative on a number somebody rounded up.

    What Should You Do Next?

    Pick one check — the confusion flag if you want the highest yield for the least work — and run it twice a week for three weeks on a text you were teaching anyway. Sort, do not mark. Spend one whole class period in those three weeks teaching into whatever the biggest pile said, and notice whether the next set of flags moves.

    If it does, add a second check. If it does not, the problem is probably that the flags are not changing your lesson yet, which is the failure mode the research is loudest about. Two related pages are worth having open: the site’s guide to what counts as evidence that a class understood something for the general-purpose version of these moves, and the version that runs while a draft is still being written for the same problem on the production side. If your reading happens on screens, the medium changes some of this — digital reading has its own comprehension research and its own accessibility upside. And if you want students doing more of the judging themselves, which is what the strongest moderator in the meta-analysis points at, start with student self-assessment.

    Before you go: grab the free Formative Assessment Quick-Use Pack (PDF) — ElevateTheNorm.com branded, printable, no email required.

    Frequently Asked Questions

    What is a formative assessment strategy for reading, exactly?

    It is any short, ungraded check that shows you what a student understood from a text while you can still do something about it. A two-sentence gist statement, a confusion flag, a one-question prediction, a retell in the student’s own words. The test is not the format. The test is whether the information changes what you do in the next ten minutes. If you collect it and file it, you ran a quiz.

    Should reading checks be graded?

    No, and the reason is practical rather than philosophical. The moment a gist statement counts for points, students write what they think you want instead of what they actually understood, and the check stops telling you anything. Keep them in a separate column or in no column at all. If your school requires a reading grade, take it from something summative and say out loud that the daily checks do not feed it.

    How do I do this without reading 120 responses every night?

    Sort, do not mark. A stack of 28 two-sentence gist statements is a five-minute sort into three piles — got it, partial, missed the point — and the only thing you write is the number in each pile. That number is the instructional decision. Reading every response carefully is what makes teachers abandon this in week three, and it is not what produces the benefit.

    Does the research actually support this for high school students?

    Partly, and the gap is worth knowing before anyone quotes a number at you. The meta-analysis evidence for formative assessment and reading achievement includes middle and high school studies and finds them performing at least as well as elementary. But an IES review of twenty years of adolescent literacy research found that of twelve programs with positive or potentially positive effects on reading outcomes, none was conducted in a high school setting. The practices are defensible. The claim that they are proven in a high school is not.

    Is the effect size big enough to be worth the class time?

    It is modest and it is real. The most recent meta-analysis puts formative assessment’s effect on reading achievement at +0.19 across 48 studies and 116,051 students. An earlier meta-analysis found a weighted mean of 0.20 overall and 0.32 for English language arts specifically — and explicitly rejected the 0.40 to 0.70 range that gets quoted in professional development. Two or three minutes a day for a modest, reliable gain is a good trade. A forty-minute assessment system for the same gain is not.

    What about the student who cannot read the text at all?

    A comprehension check tells you that, which is most of its value. What it must not do is tell the whole room. None of the checks here require reading aloud in front of peers, and that is deliberate. A written gist, a confusion flag on a sticky note, or a quiet conversation at a side table all give you the same information without making a struggling reader perform. The WWC panel rates intensive individualized support for struggling adolescent readers as a strong recommendation, and a daily check is how you find out who needs it — not a substitute for it.

    Does technology make these checks better?

    The evidence says not much. The same meta-analysis that found a +0.19 effect for formative assessment in reading tested whether technology involvement moderated it and found essentially nothing — a coefficient of +0.001. A form on a laptop and a sticky note produce the same result. Use whichever one your students will actually complete in ninety seconds.

    What actually predicted bigger effects, if not technology?

    Two things, and both are about what happens after the check. Approaches that integrated teacher and student use of the information beat teacher-directed approaches alone by a significant margin. And studies where the information fed differentiated instruction showed an effect of +0.24 against +0.05 for those where it did not. Collecting the data is not the intervention. Changing the next lesson is.

    Sources

    1. Xuan, Qingzhi, Alan C. K. Cheung, and Danping Sun. “The Effectiveness of Formative Assessment for Enhancing Reading Achievement in K-12 Classrooms: A Meta-Analysis.” Frontiers in Psychology, vol. 13, 2022. 48 studies, 116,051 students; pooled ES +0.19; middle/high school +0.27; differentiated instruction +0.24 vs +0.05; technology coefficient +0.001 (n.s.); small-sample studies +0.45 vs +0.13 for large. https://www.frontiersin.org/journals/psychology/articles/10.3389/fpsyg.2022.990196/full
    2. Kingston, Neal, and Brooke Nash. “Formative Assessment: A Meta-Analysis and a Call for Research.” Educational Measurement: Issues and Practice, vol. 30, no. 4, 2011, pp. 28–37. 13 studies, 42 effect sizes; weighted mean 0.20, median 0.25; English language arts 0.32, mathematics 0.17, science 0.09. https://eric.ed.gov/?id=EJ951173
    3. Kamil, Michael L., et al. Improving Adolescent Literacy: Effective Classroom and Intervention Practices. IES Practice Guide, NCEE 2008-4027, What Works Clearinghouse, 2008. Five recommendations with evidence levels; explicit vocabulary instruction and explicit comprehension strategy instruction both rated strong. https://ies.ed.gov/ncee/wwc/docs/practiceguide/adlit_pg_082608.pdf
    4. Institute of Education Sciences, Regional Educational Laboratory Southeast. Summary of 20 Years of Research on the Effectiveness of Adolescent Literacy Programs and Practices. 111 studies screened, 33 met WWC evidence standards, 12 programs with positive or potentially positive effects — none conducted in a high school setting. https://ies.ed.gov/use-work/resource-library/report/systematic-literature-review/summary-20-years-research-effectiveness-adolescent-literacy-programs-and-practices
    5. Agarwal, Pooja K., Ludmila D. Nunes, and Janell R. Blunt. “Retrieval Practice Consistently Benefits Student Learning: A Systematic Review of Applied Research in Schools and Classrooms.” Educational Psychology Review, vol. 33, no. 4, 2021, pp. 1409–1453. 50 experiments, 5,374 participants; 57% of effect sizes medium or large. https://link.springer.com/article/10.1007/s10648-021-09595-9

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • Formative Assessment Strategies for Writing: Checks That Fit a Real Week

    Formative Assessment Strategies for Writing: Checks That Fit a Real Week

    By Clay Shumate

    Formative assessment strategies for writing are the checks a teacher runs while a piece is still being written, so the information can still change the draft. Exit tickets and comprehension checks do not transfer here. Writing has its own set, because the thing being assessed takes days, gets revised, and is too long to read thirty times a week. The equivalents for reading work on a different clock and are collected separately.

    That last constraint is the real problem. Almost every writing-feedback system that gets abandoned was abandoned because it required reading every draft. What follows is what the research supports, the number that should worry you, and a set of checks that fit an ordinary secondary schedule.

    Key Takeaways

    • Feedback works, and the size depends on who gives it. A meta-analysis found adult feedback at an effect size of 0.87, self-evaluation at 0.62 and peer feedback at 0.58 — but that study covered grades 1–8.
    • Two popular practices showed no meaningful effect in the same analysis. Teacher progress monitoring and the 6+1 Trait Writing model did not improve writing quality.
    • The federal practice guide rates the assessment recommendation as its weakest. Of three recommendations for teaching secondary writing, “use assessments to inform instruction and feedback” carries minimal evidence. That is worth knowing before anyone sells you a system.
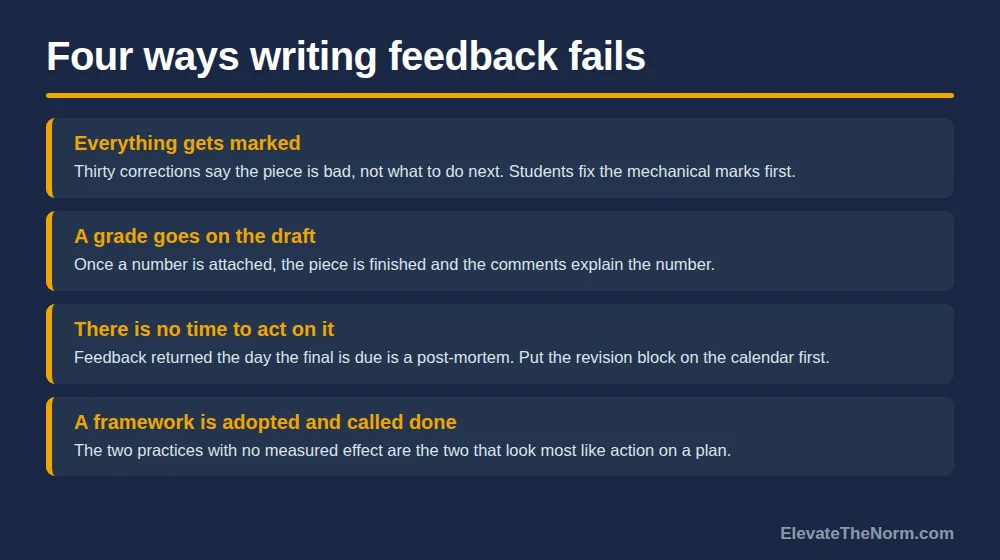
    • Assess one thing at a time. A draft marked for everything gets revised for nothing. Pick the criterion the lesson taught and check only that.
    • Never put a grade on a draft you want revised. Self-assessment that counts toward a mark stops being honest, and the same logic applies to a draft.

    Free Download · PDF

    Formative Assessment Quick-Use Pack

    A strategy decision matrix, an evidence tracker, four exit-ticket formats, and a next-day response planner — four pages built around changing the next instructional move.

    Download the free PDF

    Free. No email address required. Designed for grades 6–12. Browse every printable in Your Free Library.

    What Makes a Writing Check Formative?

    Timing and use. A check is formative if it happens while the piece can still change and if somebody acts on it. Both conditions. A rubric applied to a final draft, however detailed, is a grade with extra steps.

    That rules out more of the standard toolkit than teachers expect. Marking a finished essay is summative no matter how much you write in the margin. A reading quiz is not a writing check. A participation grade for peer editing measures compliance with a procedure, not the quality of anything. The general versions of these checks are covered in the general version, twenty techniques sorted by lesson phase; this page is about the ones built for a text that takes a week.

    What is distinctive about writing is that the product has stages. A thesis exists before the paragraph does, an outline before the draft, a draft before the revision. Each stage is a place to check something cheaply, while it is still cheap to fix. The whole art is checking the earliest stage at which the problem is visible — because a thesis fixed on Monday saves five paragraphs that never had to be written.

    What Does the Research Actually Show?

    That feedback on writing works, that two popular practices do not, and that the evidence for the whole assessment-driven approach is weaker than its popularity suggests. All three are worth having straight.

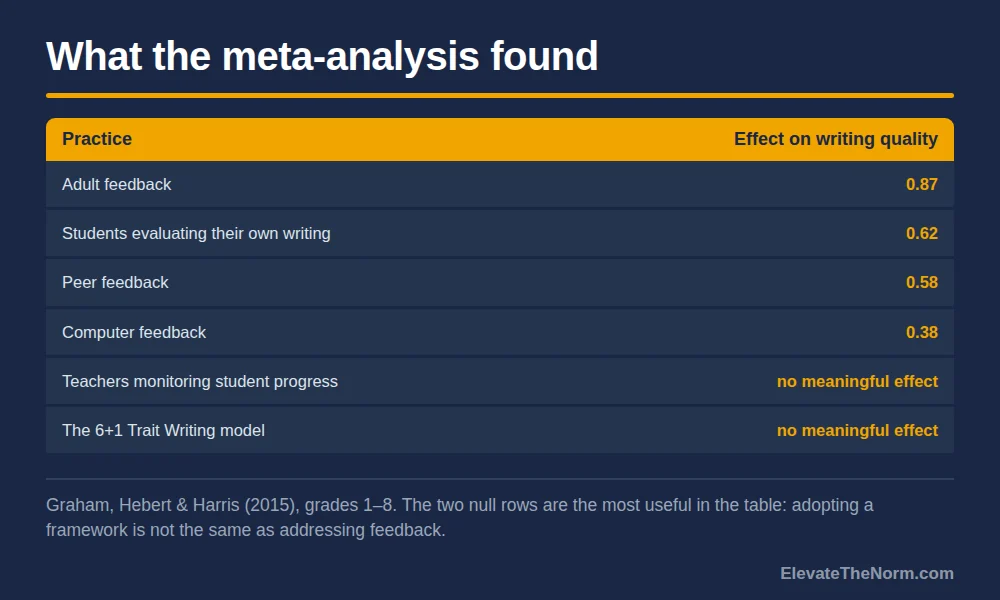
    The central study is Graham, Hebert and Harris’s 2015 meta-analysis in the Elementary School Journal, which pooled experimental studies of formative writing assessment and reported effect sizes by who does the assessing:

    PracticeEffect on writing quality
    Adult feedback0.87
    Students evaluating their own writing0.62
    Peer feedback0.58
    Computer feedback0.38
    Teachers monitoring student progressno meaningful improvement
    The 6+1 Trait Writing modelno meaningful improvement

    Three things to notice. First, the grade band is 1 through 8. Only the top three grades of that range are secondary, and none of it is high school. The practices are reasonable to carry upward; the numbers do not travel with them.

    Second, the two null results are the most useful rows in the table. Progress monitoring — tracking writing scores over time to inform instruction — showed no meaningful improvement, and neither did 6+1 Trait, which is a widely adopted framework. That does not make either worthless, but it does mean a department should not treat adopting them as having addressed writing feedback.

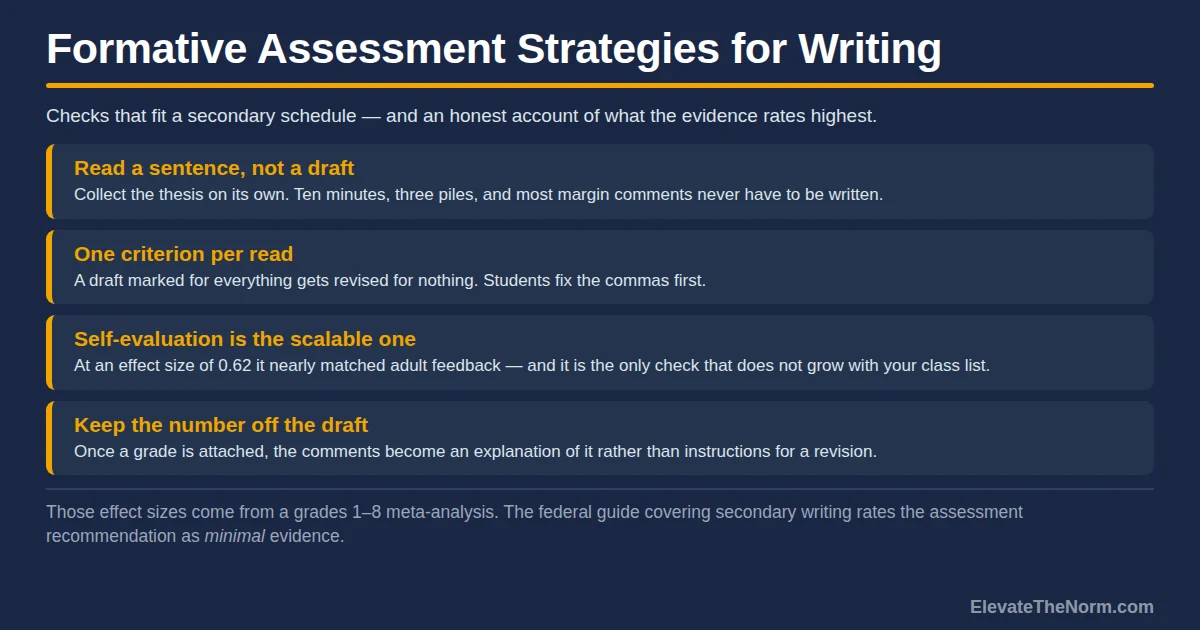
    Third, student self-evaluation at 0.62 nearly matched adult feedback and beat peer feedback. For a teacher with 120 students, that is the most consequential number in the table, because it is the only one that does not scale with your reading time.

    Now the part most articles omit. The What Works Clearinghouse practice guide on teaching secondary students to write effectively, written by a panel including Steve Graham, Jill Fitzgerald, Linda Friedrich, Katie Greene, James Kim and Carol Booth Olson, makes three recommendations and rates the evidence behind each. Explicitly teaching writing strategies through a model–practice–reflect cycle is rated strong. Integrating writing and reading using exemplar texts is rated moderate. Using assessments to inform instruction and feedback is rated minimal.

    Minimal is the lowest rating in that system, and it is attached to the recommendation this article is about. Read it as a statement about proportion rather than a reason to stop. If you have a fixed amount of energy for improving writing in your classroom, the guide says to spend it first on explicitly teaching strategies and modeling them — and the assessment practices below are what you run inside that, not instead of it.

    Table of effect sizes on writing quality from a formative assessment meta-analysis: adult feedback 0.87, student self-evaluation 0.62, peer feedback 0.58, computer feedback 0.38, and no meaningful effect for teacher progress monitoring or the 6+1 Trait Writing model
    Graham, Hebert and Harris (2015), grades 1-8. The two null rows are the most useful in the table.

    Which Checks Fit a Secondary Schedule?

    The ones that read a sentence rather than a draft. Every strategy below is designed around the fact that you cannot read 120 full drafts and still have a weekend.

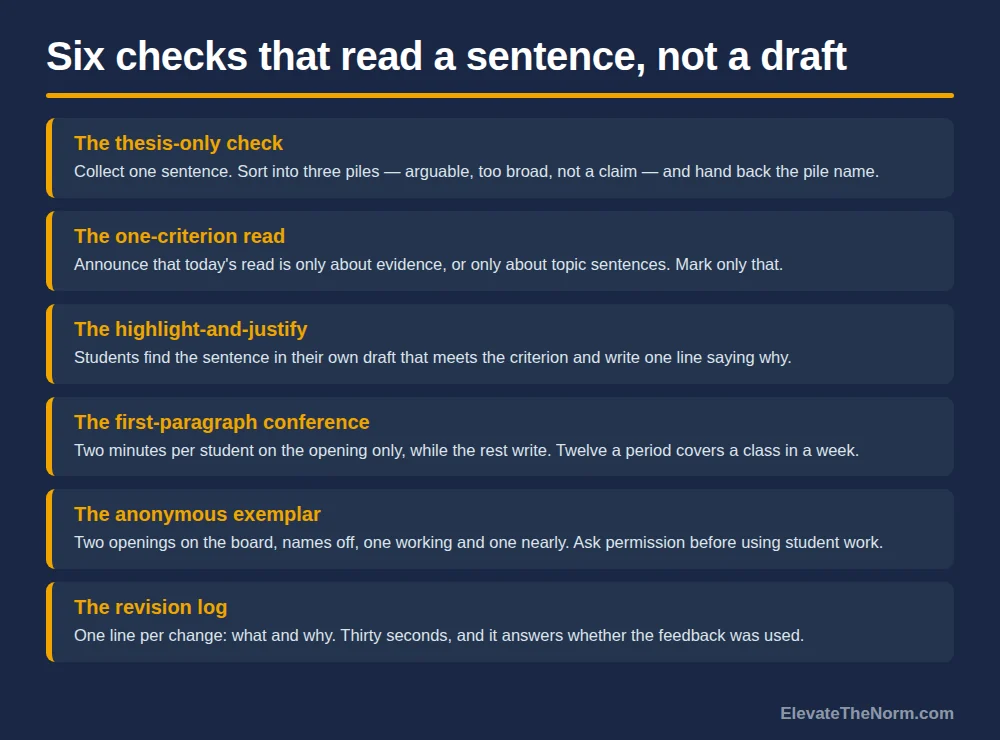
    • The thesis-only check. Collect one sentence. Read all of them in ten minutes, sort into three piles — arguable, too broad, not a claim — and hand them back with the pile name. Fixing this on day one prevents most of what you would otherwise write in margins on day six.
    • The one-criterion read. Announce that today’s read is only about evidence, or only about topic sentences. Mark only that. A draft marked for everything gets revised for nothing, because a student facing thirty marks does not know where to start and usually starts with the commas.
    • The highlight-and-justify. Students highlight the sentence in their own draft that meets a specific criterion, and write one line explaining why. If they cannot find it, that is the check — and they have found it themselves, which is the part that matters.
    • The first-paragraph conference. Two minutes per student, on the opening paragraph only, while the rest write. Twelve students a period, everybody covered across a week.
    • The anonymous exemplar. Put two short pieces of writing on the board with names removed — one that does the thing, one that nearly does it — and have the class say which and why. This is the model–practice–reflect cycle the WWC rates as strong evidence, run as a five-minute check. Ask before you use a student’s work, even anonymized, because the writer always recognizes their own sentences and so do the people sitting next to them. Asking takes ten seconds, almost nobody says no, and the ones who do have a reason. Writing your own two versions, or using last year’s with permission, works just as well.
    • The revision log. One line per revision: what changed, and why. It takes a student thirty seconds and tells you whether feedback was used, which is the only question a progress tracker was ever trying to answer.

    Notice what is missing: reading every draft, writing extended comments, and any system requiring a spreadsheet. Those are the things that get abandoned in October, and abandonment is the real failure mode — not choosing the second-best check. If you would rather start from something printed, the free formative assessment quick-use pack has a general version to adapt.

    Graphic listing six formative writing checks: the thesis-only check, the one-criterion read, the highlight-and-justify, the first-paragraph conference, the anonymous exemplar, and the revision log
    Every one of these reads a sentence rather than a draft. That is what makes them survive past October.

    How Do You Make Self-Evaluation Work?

    Give the criteria first, keep it out of the gradebook, and ask for evidence rather than a rating. At 0.62 this is the best return per minute of teacher time in the whole table, and all three conditions matter.

    Heidi Andrade’s 2019 critical review in Frontiers in Education supplies the design rules. Criterion-referenced self-assessment showed main effects on every criterion assessed, and concrete task-specific criteria outperformed vague competence-based ones — a result she attributes to Fastré and colleagues. In writing terms, “every claim is followed by a quotation and an explanation of it” is checkable. “Uses evidence effectively” is not.

    The decisive rule is about grading. Andrade cites Tejeiro and colleagues, where self-assessment counted toward the final grade: overestimation rose dramatically and no correlation remained between the instructor’s assessment and the student’s. Run formatively, agreement improved substantially, and all twenty studies in her review that used self-assessment formatively showed a positive association with learning.

    Andrade makes one more point worth carrying. There is little evidence that inaccurate self-assessment produces worse learning, and students act on their predictions regardless of accuracy. You are not trying to make a student’s judgment match yours. You are trying to make them read their own draft as a reader. The broader version of the practice is in the student self assessment guide; writing only changes what sits in the criteria.

    Is Peer Feedback Worth the Class Time?

    Yes at 0.58, and only if you narrow what you ask for. Unstructured peer review produces “I liked it, maybe add more detail,” which is the outcome most teachers have seen and correctly concluded is a waste of twenty minutes.

    There is a useful finding from an adjacent literature. Falchikov and Goldfinch’s meta-analysis of 48 higher-education studies comparing peer marks with teacher marks found that agreement was closest when students made a global judgment against well-understood criteria, and worse when asked to break the judgment into many separate dimensions and score each. Those were undergraduates marking work, not teenagers giving revision advice, so treat it as a design hint rather than a transferred result — but the hint points somewhere useful: the twelve-box peer editing checklist is probably the worst available format.

    What works better is narrower and more concrete:

    • Ask for a location, not a judgment. “Underline the sentence where the argument actually starts.” A reader can do that honestly; “rate the organization” they cannot.
    • Ask what the reader could not follow. This is the one thing a peer knows that you do not, because they read it without already knowing what the writer meant.
    • Ask for one question, not one suggestion. Suggestions are advice from a novice. A genuine question — “is this the same person as in paragraph two?” — is information the writer can act on without deferring to anyone.

    Two cautions. Peer feedback has a social cost that teacher feedback does not. A fifteen-year-old asked to critique a classmate’s writing is managing a relationship as well as a text, and most will resolve that tension by being vague. Asking for locations and questions rather than evaluations removes the tension rather than asking students to override it. And decide who reads what before you start. Writing is personal in a way a math worksheet is not; a student writing about something that matters to them should know in advance whether a classmate will see it, and should have a way out.

    A One-Week Routine That Does Not Require Reading Every Draft

    Four checks across a week, none of which takes you more than fifteen minutes.

    1. Day one — collect the thesis only. One sentence per student. Sort into three piles, hand back with the pile name, and give the “not a claim” pile five minutes to try again.
    2. Day two — the anonymous exemplar. Two openings on the board, names off, one working and one nearly working. The class names the difference. This is the modeling step, and it is the one with the strongest evidence behind it.
    3. Day three — highlight and justify. Students find the sentence in their own draft that meets today’s single criterion and write one line saying why. Walk the room and read over shoulders; collect nothing.
    4. Day four — peer question round. Swap drafts. Each reader underlines where the argument starts and writes one genuine question. Ten minutes, no checklist.

    Then the revision log on day five: one line per change, what and why. That log is the whole assessment record, and unlike a score tracker it answers the question that actually matters, which is whether any of this changed the draft.

    Two adjustments. First, differentiate the container rather than the criterion — a student who cannot produce the written justification quickly can say it to you in the last minute of class, and a student working in a second language can highlight and point. The judgment against criteria is what has to survive. Second, if a student’s draft has a problem that is not today’s criterion, note it for yourself and leave it. You will get to organization on the week you are checking organization, and a student who receives one correctable thing at a time actually corrects it. For the general version of this discipline, see what actually counts as evidence that a class understood something.

    Four Ways Writing Feedback Fails

    All four are common, and all four are about the system rather than the student.

    Everything gets marked. A draft returned with thirty corrections communicates that the piece is bad, not what to do next. Students respond by fixing the easiest marks, which are almost always the mechanical ones. One criterion per read is not a compromise — it is what makes revision possible.

    A grade goes on the draft. Once a number is attached, the piece is finished in the student’s mind, and the comments underneath it become an explanation of the number rather than instructions for a revision. If you need the draft in the gradebook, grade completion rather than quality, and say which you are doing.

    The one-criterion rule is also the thing families most often ask about, usually in the form of why the teacher did not correct all the errors. It deserves a straight answer rather than a defensive one: every error was noticed, and marking all of them is what produces a draft a student fixes the commas in and hands back otherwise unchanged. The errors get their turn, one at a time, on the assignment where that is the thing being taught. Said in advance, in a sentence on the assignment sheet, that lands as a deliberate method. Said after a parent email, it sounds like an excuse.

    There is no time to act on it. Feedback returned the day the final is due is a post-mortem. If the schedule does not contain a revision block after the feedback, the feedback is decorative, and it is more honest to admit that than to keep writing comments into a void.

    Graphic listing four ways writing feedback fails: everything gets marked, a grade goes on the draft, there is no time to act on it, and a framework is adopted and called done
    All four are about the system rather than the student.

    The department adopts a framework and calls it done. This is where the two null results earn their keep. Adopting 6+1 Trait or installing a progress-monitoring spreadsheet is a visible action that showed no meaningful effect on writing quality in the meta-analysis. The things that did work — someone reads a piece of writing and responds to it, or a student reads their own against criteria — are less visible on a plan, and are the ones worth protecting time for.

    What to Try on the Next Assignment

    Take the next piece of writing you have already assigned. Collect the thesis on its own, before anything else exists, and sort the sentences into three piles. That single move costs you ten minutes and changes more drafts than any set of margin comments you will write later.

    Then pick one criterion for the whole assignment and check only that — in the exemplar, in the self-evaluation, in the peer round, in your own read. Put a revision block on the calendar before you give any feedback, and keep a number off the draft.

    None of this is a system, and that is deliberate. The evidence for assessment-driven writing instruction is rated minimal by the people best placed to judge it, while explicit strategy instruction and modeling are rated strong. The checks here are worth running because they are cheap and they surface problems early. They are not a substitute for teaching students how to write, and any resource presenting them as one has the proportions backwards.

    Before you go: grab the free Formative Assessment Quick-Use Pack (PDF) — ElevateTheNorm.com branded, printable, no email required.

    Frequently Asked Questions

    Do these effect sizes apply to high school students?

    Not directly, and it matters. The meta-analysis behind the headline numbers — adult feedback 0.87, self-evaluation 0.62, peer feedback 0.58 — covered grades 1 through 8, so only its top three grades are secondary at all and none is high school. The practices are reasonable to carry upward because the mechanisms are not age-specific, but the numbers should not be quoted as a high school result. The federal practice guide that does cover secondary writing rates the assessment recommendation as having minimal evidence.

    Should I put a grade on a draft?

    Not if you want it revised. Once a number is attached, most students treat the piece as finished and read the comments as justification for the mark rather than instructions for a revision. The self-assessment research points the same way: when self-evaluation counted toward a grade, overestimation rose sharply and agreement with the instructor disappeared. If a draft has to appear in the gradebook, grade completion rather than quality and tell students that is what you are doing.

    Is 6+1 Trait Writing a waste of time?

    That is stronger than the evidence supports. What the meta-analysis found is that 6+1 Trait showed no meaningful improvement in writing quality, and the same was true of teachers monitoring student progress over time. That is a real finding and a department should not treat adopting the framework as having addressed writing feedback. It is not a finding that a shared vocabulary for talking about writing is harmful — it is a finding that the vocabulary alone does not move the writing.

    How do I give feedback to 120 students without losing every weekend?

    Stop reading whole drafts. Collect one sentence rather than one essay; mark one criterion rather than everything; run two-minute conferences on opening paragraphs while the rest write; and lean on self-evaluation, which came in at 0.62 and is the only practice in the table that does not scale with your reading time. A teacher who reads every draft thoroughly in September and nothing at all by November has given less useful feedback than one who reads one paragraph from everybody every week.

    Does peer feedback actually help, or is it busywork?

    It helped at an effect size of 0.58, which is real — but what most classrooms run is not what was studied. Unstructured peer review produces “I liked it, add more detail.” Narrow the ask instead: have readers underline where the argument starts, say what they could not follow, and write one genuine question rather than one suggestion. Those ask for information a peer actually has. Also settle who reads what before you begin, because writing is more personal than a worksheet and a student should know in advance.

    What if a student’s draft has problems that are not this week’s criterion?

    Note them for yourself and leave them alone. A student who receives one correctable thing at a time usually corrects it; a student who receives thirty fixes the commas. Keep your own running list and let it decide what the criterion is for the next assignment — that list is more useful as a planning document than as margin notes, and it means the pattern across the class shapes what you teach next rather than disappearing into thirty separate drafts.

    How is this different from just marking essays carefully?

    Timing and use. Marking a finished essay is summative however detailed it is, because nothing about that piece can change afterwards. A formative check happens while the writing is still in progress and is followed by time to act on it. The practical test is simple: if there is no revision block on the calendar after the feedback goes back, what you did was grading, and calling it formative assessment does not make it function like one.

    Where should I spend my energy if I can only change one thing?

    Not here, according to the people who reviewed the evidence. The What Works Clearinghouse panel rates explicitly teaching writing strategies through a model–practice–reflect cycle as strong evidence, integrating reading and writing with exemplar texts as moderate, and using assessments to inform instruction and feedback as minimal. If you have one change in you this year, make it the modeling. The checks on this page are cheap enough to run inside that work, and they are not a replacement for it.

    Sources

    1. Graham, Steve, Michael Hebert, and Karen R. Harris. “Formative Assessment and Writing: A Meta-Analysis.” Elementary School Journal, vol. 115, no. 4, 2015, pp. 523–547. https://eric.ed.gov/?id=EJ1068976
    2. Graham, Steve, Jill Fitzgerald, Linda D. Friedrich, Katie Greene, James S. Kim, and Carol Booth Olson. “Teaching Secondary Students to Write Effectively” (practice guide summary). What Works Clearinghouse, Institute of Education Sciences, U.S. Department of Education. https://ies.ed.gov/ncee/wwc/Docs/PracticeGuide/wwc_secwrit_summary_053117.pdf
    3. Andrade, Heidi L. “A Critical Review of Research on Student Self-Assessment.” Frontiers in Education, vol. 4, art. 87, 2019. https://www.frontiersin.org/journals/education/articles/10.3389/feduc.2019.00087/full (The Tejeiro et al. 2012 and Fastré et al. 2010 findings are reported in this review; the primary papers were not read directly.)
    4. Falchikov, Nancy, and Judy Goldfinch. “Student Peer Assessment in Higher Education: A Meta-Analysis Comparing Peer and Teacher Marks.” Review of Educational Research, vol. 70, no. 3, 2000, pp. 287–322. https://eric.ed.gov/?id=EJ630369

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

  • Student Self Assessment for Group Work: What to Ask and What to Skip

    Student Self Assessment for Group Work: What to Ask and What to Skip

    By Clay Shumate

    Student self assessment in group work is a short structured rating in which each student judges their own contribution against criteria everyone saw before the project started. It is not a popularity form and it is not a way to catch a freeloader. Its job is to make individual effort visible inside a shared product, which is the one thing a group grade cannot do.

    That is a narrower purpose than most group-work reflection sheets claim, and the narrowness is what makes it work. What follows is what the research supports, the one design decision that determines whether the ratings mean anything, and a form that takes a student four minutes.

    Key Takeaways

    • Ask for one overall judgment, not eight. The clearest finding in the peer-assessment literature is that ratings line up with a teacher’s when students make a global judgment against criteria they understand — and drift when they are asked to score many separate dimensions.
    • Self-assessment is the individual-accountability half of group work. Cooperative learning research names individual accountability as one of five elements that have to be present. A self-rating with evidence is the cheapest way to supply it.
    • Never let it change anybody’s grade. When self-assessment counts toward a mark, overestimation rises and agreement with the teacher disappears.
    • Criteria before the project, not after. A student cannot rate a contribution against a standard they are seeing for the first time on the last day.
    • Most of this evidence is from higher education. It transfers as a design principle. It is not a measured secondary-school result, and you should not be told otherwise.

    Free Download · PDF

    Student Self-Assessment Forms for Grades 6–12

    A general self-assessment form, a project reflection, a group-work accountability form, and a conference preparation sheet — reflection that asks for evidence instead of a confidence rating.

    Download the free PDF

    Free. No email address required. Designed for grades 6–12. Browse every printable in Your Free Library.

    What Is Student Self Assessment for Group Work?

    It is each student, separately and in writing, answering three questions about a shared project: what did I actually do, how well does it meet the criteria we agreed on, and what would I do differently next time. Three parts. Take away the criteria and it is a feelings check. Take away the evidence and it is a claim. The same evidence rule governs checking a draft while it is still a draft.

    It is worth distinguishing from the thing it gets confused with. Self-assessment is not peer assessment. Peer assessment asks students to rate each other, which raises questions about friendship, retaliation and social cost that a self-rating does not. The two can coexist, and plenty of published teamwork instruments combine them, but they are different instruments doing different jobs, and mixing them without saying so is how a reflection sheet turns into a blame form.

    The wider practice is covered in the guide to student self assessment. Group work only changes what sits in the criteria column — and it adds a problem that individual work does not have, which is that the product no longer tells you who did what.

    Why Bother, When the Project Already Has a Grade?

    Because a group grade is a measurement of the artifact, and you are also trying to teach something about contribution. One number on one poster cannot carry both jobs.

    Cooperative learning is one of the better-evidenced practices in education, and the research is specific about what has to be in place. Robyn Gillies’s 2016 review in the Australian Journal of Teacher Education names five elements: positive interdependence, promotive interaction, individual accountability, explicitly taught social skills, and group processing. The effect sizes she reports from Johnson and Johnson’s syntheses run in the 0.58 to 0.70 range across 117 studies, and the underlying work spans preschool to tertiary and most subject areas.

    The sentence in that review that matters most for a secondary teacher is the plainest one: simply placing students in groups does not guarantee cooperation. Gillies notes that discord shows up when students struggle with the task and with managing each other, and that without teacher mediation high-level talk appears with low frequency. Group work is not self-executing. Individual accountability and group processing are the two elements a self-assessment directly supplies, and they are the two most often left out.

    She also reports two structural findings worth acting on for free: optimal group size is three or four, and lower-attaining students benefit most from mixed-attainment grouping while middle-attaining students tend to do better in more homogeneous groups. Neither costs anything to apply.

    What Should Students Rate — and How Many Things?

    One overall judgment against two or three criteria they already know. Not a scorecard. This is the single most actionable finding in this whole literature and almost every classroom teamwork form gets it backwards.

    Falchikov and Goldfinch’s 2000 meta-analysis in the Review of Educational Research pooled 48 studies comparing peer marks with teacher marks. Their central result: agreement was closest when students made global judgments based on well-understood criteria, and worse when they were asked to break a judgment into many separate components and score each one.

    That is the opposite of how most group-work forms are built. The typical sheet asks a student to rate themselves on participation, preparation, communication, reliability, respect, leadership and time management, on a five-point scale, seven times. The literature predicts exactly what you see when you collect them: rows of fours, no discrimination between the dimensions, and no usable information.

    The honest caveat: those 48 studies were higher education, and they were peer marks rather than self-marks. The mechanism — that people judge a whole thing against a standard better than they decompose it — is a reasonable thing to carry into a secondary classroom. It is not a measured result about fifteen-year-olds, and nobody should sell it to you as one.

    Two-column table contrasting trait rating scales such as rate your participation one to five with fact-based questions such as name the part of the final product you built and which deadline did you miss
    Every item on the right asks for a fact that can be checked against the product.

    So what goes on the form:

    Skip thisAsk this instead
    Rate your participation 1–5Name the part of the final product you built, and point to it
    Rate your communication 1–5What did the group have to redo because of something you did or did not do?
    Rate your reliability 1–5Which deadline did you meet, and which did you miss?
    Rate your leadership 1–5What decision did the group make that you argued for?
    How well did your group work together?Overall, how close is your own contribution to the standard we set on day one? One rating, with a reason.

    Every item on the right asks for a fact rather than a number about a personality trait. Facts are checkable against the product, and a student who claims to have built the timeline can be asked to show it. That is also what makes the sheet safe: it never requires a teenager to say something negative about a classmate in writing.

    Does a Rubric Make the Self-Rating Better?

    For the work, clearly. For the teamwork part, less clearly, and the evidence is thinner than the enthusiasm.

    Heidi Andrade’s 2019 critical review in Frontiers in Education reports that criterion-referenced self-assessment — using a rubric or checklist — showed main effects on every criterion assessed, and that concrete, task-specific criteria outperform vague competence-based criteria. If the rubric says “the claim is supported by at least two sources,” a student can check. If it says “demonstrates strong collaboration,” they cannot.

    On the teamwork side specifically, one study is worth reporting honestly because it cuts both ways. Pang, Kootsookos, Fox and Pirogova compared two cohorts of 186 first-year engineering undergraduates on a team design project: one got a marking scheme, the next got a detailed rubric. The rubric cohort reported more helpful feedback, higher satisfaction and achieved higher grades, and 96 percent said the rubric helped them reach the learning goals. But only 52 percent found it useful for constructive feedback on teamwork specifically. The authors list the limits themselves: one course, one institution, one grading instructor.

    Read that as the useful signal it is. A rubric is very good at telling a student whether the work meets a standard. It is much weaker at telling them whether they were a good group member, because that is a harder thing to write criteria for. So write the rubric for the product, and handle contribution with the evidence questions above rather than by inventing a collaboration scale. The project rubric guide covers the product side.

    A Four-Minute Group Work Self-Assessment

    Five prompts, filled in individually, before anyone talks about it. Individually and before matters: a student who has already heard the group’s version writes the group’s version.

    1. Name your piece. Which part of the finished product did you make? Point at it. If you cannot point at anything, say that — it is real information and it is not a punishment.
    2. Give one piece of evidence. A file, a draft, a section, a specific decision. This is the step that does the work; a contribution claim with no evidence is an opinion.
    3. One overall rating against the day-one standard. 0–3, with the anchors written out, and a one-sentence reason. One rating, not seven.
    4. What did the group have to redo because of you? The most useful question on the sheet, and the one students answer more honestly than you expect, because it is about a task rather than a character.
    5. One thing you would do differently on the next project. Specific and small. “Start the research before the night before” is a plan.
    Numbered graphic of five group work self assessment prompts: name your piece, give one piece of evidence, give one overall rating, say what the group had to redo because of you, and name one thing you would do differently
    Filled in individually, before the group talks about it. Prompt four is the most useful one on the sheet.

    The first time you run it, teach it. Students have almost never been asked to describe their own contribution in specific terms, and left alone most will write “I helped with the slides.” Show a worked example on the board — a vague answer next to a specific one — and say plainly that naming a real limit is not going to be held against them. Ten minutes once. Every version of this that gets abandoned was abandoned because the first round produced nothing and the teacher concluded students could not do it.

    Then hold the group conversation. Gillies’s fifth element is group processing — students reflecting together on how the work went and what to do next. The sheet is the private half; five minutes of the group comparing what each person wrote is the public half, and the sequence only works in that order. If you want a ready-made form to adapt, the free self-assessment pack has one you can retype the criteria into.

    Be realistic about what reading twenty-eight of these costs you. It is not a stack to mark. Read them once, fast, looking only for the two things that matter: who could not point at a piece of the product, and what any group says it had to redo. That is a scan, not a grading session, and it should take about fifteen minutes for a full class. If you find yourself writing responses on them, you have turned a diagnostic into an assignment and you will stop doing it by November.

    One accessibility note. The written form is one container, not the only one. A student who cannot produce five written answers quickly — a writing disability, a newcomer building English — can answer the same five prompts out loud in ninety seconds while you note it down. The judgment against criteria is the part that has to survive, not the paragraph.

    Should Any of This Touch the Grade?

    No. Not the student’s own, and not anybody else’s. This is the one place where the research gives a clean answer and the answer is unambiguous.

    Andrade’s review reports the Tejeiro finding directly: when self-assessment counted toward a final grade, student overestimation increased dramatically and no correlation emerged between the instructor’s assessment and the student’s. Run formatively, agreement with external evaluators improved substantially, and every study in the review that used self-assessment formatively showed a positive association with learning.

    There is a second reason specific to group work, and it is about fairness rather than accuracy. A self-rating that moves a grade creates an incentive to inflate, which rewards confidence rather than contribution — and confidence is not evenly distributed across a class. The students most likely to under-claim are often the ones who did the quiet, unglamorous work. Attaching marks to self-report turns that into a penalty.

    This is also the answer to the most common complaint families raise about group work, which is that a child did most of the work and shared the grade with people who did not. That complaint is often correct, and the fix families usually ask for — let my child report who slacked, and grade accordingly — is the one the evidence says not to build. The better answer, and the one worth putting in an email before the project starts rather than after it: the group grade covers the product, every student also produces something individual, the groups are small enough that contribution is visible, and the self-assessment exists so a student’s own account of their work is on the record. That is a real answer rather than a deflection, and it holds up at a conference.

    If you have a genuine contribution problem, solve it with the design instead. Assign distinct, visible roles so the product itself shows who did what. Keep the groups at three or four, where hiding is harder. Collect an individual artifact from every student alongside the group one. All three make effort visible without asking a sixteen-year-old to adjudicate it in writing.

    Four Ways This Goes Wrong

    All four are design errors, and all four are cheaper to prevent than to repair.

    The criteria arrive at the end. A student handed a rating scale on the last day is being asked to judge work against a standard they did not have while doing it. The criteria go up on day one, in the same words you will use on the form.

    Graphic listing four failure modes for group work self assessment: the criteria arrive at the end, it quietly becomes peer assessment, nothing happens next, and it is used to settle a dispute
    All four are design errors, and all four are cheaper to prevent than to repair.

    It quietly becomes peer assessment. A question like “did everyone pull their weight?” is a peer rating wearing a self-assessment label. If you want peer input, say so openly, design it properly, and be clear about who reads it. Do not smuggle it in.

    Nothing happens next. If the sheets go in a folder and the next project is organized the same way, students learn the form is ceremony. The minimum honest follow-through is one change to the next project that came from reading them — a different group size, a required interim deadline, distinct roles.

    It is used to settle a dispute. When a group is already in conflict, a self-assessment form becomes evidence in a case, and everything anyone writes becomes strategic. Deal with the conflict as a conflict. The sheet is a routine instrument for ordinary projects; it is not an investigation tool and it will not survive being used as one.

    Where to Start on the Next Project

    Pick the next group project you already have planned. On day one, put two criteria for the product on the board in the words you will use again at the end. Keep the groups at three or four. On the last day, before any group talks, give every student the five prompts and four minutes.

    Then read them for one thing only: which groups had someone who could not point at a piece of the product. That is the design question, not a discipline question, and the answer usually turns out to be that the task had fewer real jobs in it than it had people.

    Keep it out of the gradebook, keep it to one overall rating, and change one thing about the next project because of what you read. The point is not to catch anybody. It is that a student who has had to name their own contribution in writing, against a standard, has done something a group grade will never make them do — which is the same argument as handing a teenager the job of naming their own conduct against a standard they were taught rather than waiting to be told how they did.

    Before you go: grab the free Student Self-Assessment Forms for Grades 6–12 (PDF) — ElevateTheNorm.com branded, printable, no email required.

    Frequently Asked Questions

    Should a group work self-assessment ever change a student’s grade?

    No. Andrade’s review reports that when self-assessment counted toward a final grade, overestimation rose sharply and the correlation with the instructor’s own assessment disappeared; run formatively, agreement improved substantially. There is a fairness reason on top of the accuracy one: attaching marks to self-report rewards confidence rather than contribution, and the students most likely to under-claim are often the ones who did the quiet work. If you have a contribution problem, fix it with distinct roles, smaller groups and an individual artifact — not with a self-rating that moves numbers.

    How do I stop one student doing all the work without making others rate each other?

    Change the task before you change the paperwork. Three or four to a group rather than five or six, so there is less room to disappear. Distinct visible roles, so the product itself shows who did what. An individual artifact from every student alongside the group one. Those three do more about free-riding than any rating form, and none of them asks a teenager to write something negative about a classmate.

    Why one overall rating instead of scoring several categories?

    Because the evidence points that way. Falchikov and Goldfinch’s meta-analysis of 48 studies found that student ratings matched teacher marks most closely when students made a global judgement against well-understood criteria, and less closely when asked to break the judgement into many separate dimensions. The seven-category teamwork form produces rows of fours and no usable information. Be aware that those studies were higher education and were peer rather than self ratings — the mechanism travels, the measurement has not been repeated with secondary students.

    What do I do with a student who writes that they did nothing?

    Take it as information and not as a confession. A student who says honestly that they cannot point at a piece of the product has told you something valuable and has told you the truth, which is exactly the behaviour the form is supposed to make safe. Ask what the group’s tasks were and how they got divided. About half the time the answer is that the project had three real jobs and four people in the group, which is a design problem you own.

    Is peer assessment ever worth adding?

    Sometimes, but never by stealth. Peer rating carries social costs that self-rating does not — friendship, retaliation, and the position you put a student in by asking them to write something about a classmate that a teacher will read. If you use it, say plainly that you are using it, be specific about who sees the responses, keep it to observable contributions rather than judgements about people, and never let it move a grade. A question like “did everyone pull their weight?” buried in a self-assessment is peer assessment without the safeguards.

    When should students fill this in — during the project or at the end?

    Both is better than either, and the end alone is the common mistake. A short version at the halfway point can still change something while the project is running, which is the whole difference between formative and post-mortem. The end-of-project version is where the overall rating and the “what would you do differently” question belong. What matters more than timing is that students write individually before the group discusses anything.

    Does this work for a long project or only a short one?

    It scales better to longer projects, because a longer project has more distinguishable pieces for a student to point at. On a two-day task, the honest answer to “name your piece” is often that everyone did a bit of everything, and the form has little to work with. If your groups are doing short tasks, run the group processing conversation and skip the written self-assessment until there is a project big enough to have parts.

    Sources

    1. Gillies, Robyn M. “Cooperative Learning: Review of Research and Practice.” Australian Journal of Teacher Education, vol. 41, no. 3, 2016. https://files.eric.ed.gov/fulltext/EJ1096789.pdf (The Johnson & Johnson and Slavin effect sizes quoted above are reported in this review; the primary syntheses were not read directly.)
    2. Falchikov, Nancy, and Judy Goldfinch. “Student Peer Assessment in Higher Education: A Meta-Analysis Comparing Peer and Teacher Marks.” Review of Educational Research, vol. 70, no. 3, 2000, pp. 287–322. https://eric.ed.gov/?id=EJ630369
    3. Andrade, Heidi L. “A Critical Review of Research on Student Self-Assessment.” Frontiers in Education, vol. 4, art. 87, 2019. https://www.frontiersin.org/journals/education/articles/10.3389/feduc.2019.00087/full (The Tejeiro et al. 2012 and Fastré et al. 2010 findings are reported in this review; the primary papers were not read directly.)
    4. Pang, Vinh, Alex Kootsookos, Rebecca Fox, and Elena Pirogova. “Does an assessment rubric provide a better learning experience for undergraduates in developing transferable skills?” Journal of University Teaching & Learning Practice, vol. 19, no. 3, 2022. https://files.eric.ed.gov/fulltext/EJ1361716.pdf
    5. Avina, A., Boyle, S., Duble Moore, T., Hicks, T., and Wiggins, A. “Intensive Intervention Practice Guide: Self-Monitoring Systems to Support Students’ Behavioral Needs.” U.S. Department of Education, Office of Special Education Programs / National Center on Intensive Intervention, Fall 2022. https://files.eric.ed.gov/fulltext/ED628226.pdf

    About Clay Shumate

    Clay Shumate is a certified secondary Social Studies teacher in the public schools of West Alabama, with seven years of classroom experience, a B.A. in History, and an M.Ed. in Secondary Education. He writes about project-based learning, student responsibility, respect, and practical ways to hold young people to a higher standard while giving them room to learn from mistakes. He is a member of the Society of Professional Journalists and writes to its Code of Ethics; this site’s editorial standards and corrections policy are published in full. More about Clay.

Teacher Emergency Toolkit — practical resources, real classroom support. Shop on TPT.Teacher Emergency Toolkit — practical resources, real classroom support. Shop on TPT.